US English


7 Data Science Engineer - Legal Document Analytics CV Templates with Example
By Ria · Last Updated On 23 October 2026
CV example — page 1

This guide shows you how to create a clear, focused Data Science Engineer - Legal Document Analytics CV. You will learn how to organise your evidence so recruiters can quickly see your fit for this specialist role.

For this work, a strong CV connects data engineering with analysis of legal documents. Use concise evidence to show how you build reliable pipelines and apply machine learning, natural language processing, entity resolution and information extraction.

Compare the example presented in 7 layouts through their PNG image previews, then open a version in the editor to customise it. The guide also explains how to organise experience, skills and education, and how to use role-specific keywords such as Python, SQL, PySpark, Microsoft Fabric, Databricks, data quality and governance.

What Makes a Great Data Science Engineer - Legal Document Analytics CV in 2026

A strong CV makes your data engineering and legal document analytics work easy to review. Clear bullets link your actions to useful products, dependable data and informed decisions.

Use relevant keywords such as PySpark, lakehouse modelling, NLP, entity resolution and data lineage. Support claims with evidence from your own work, including results you can explain.

Note: CV examples are for educational purposes only. Use only information that accurately reflects your experience and qualifications. References to real organisations do not imply affiliation or endorsement.

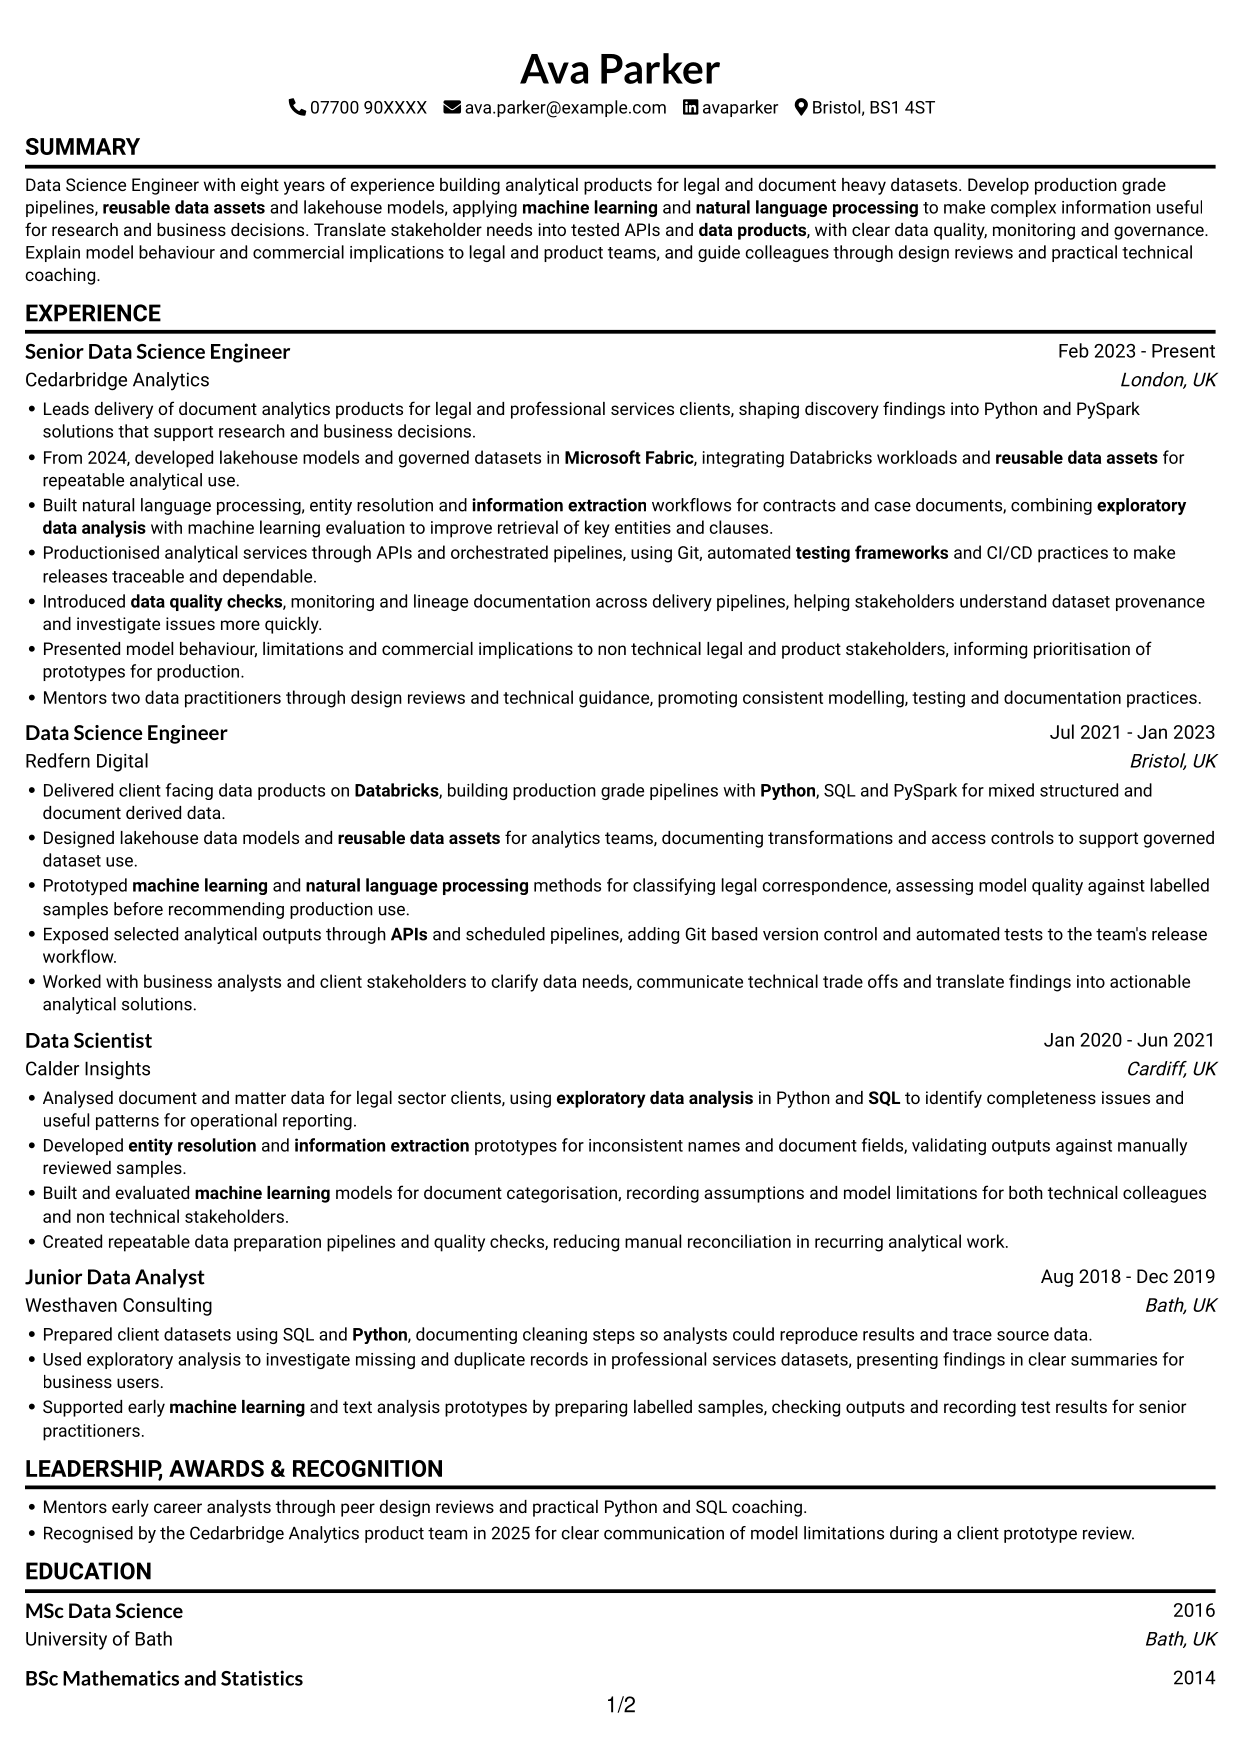
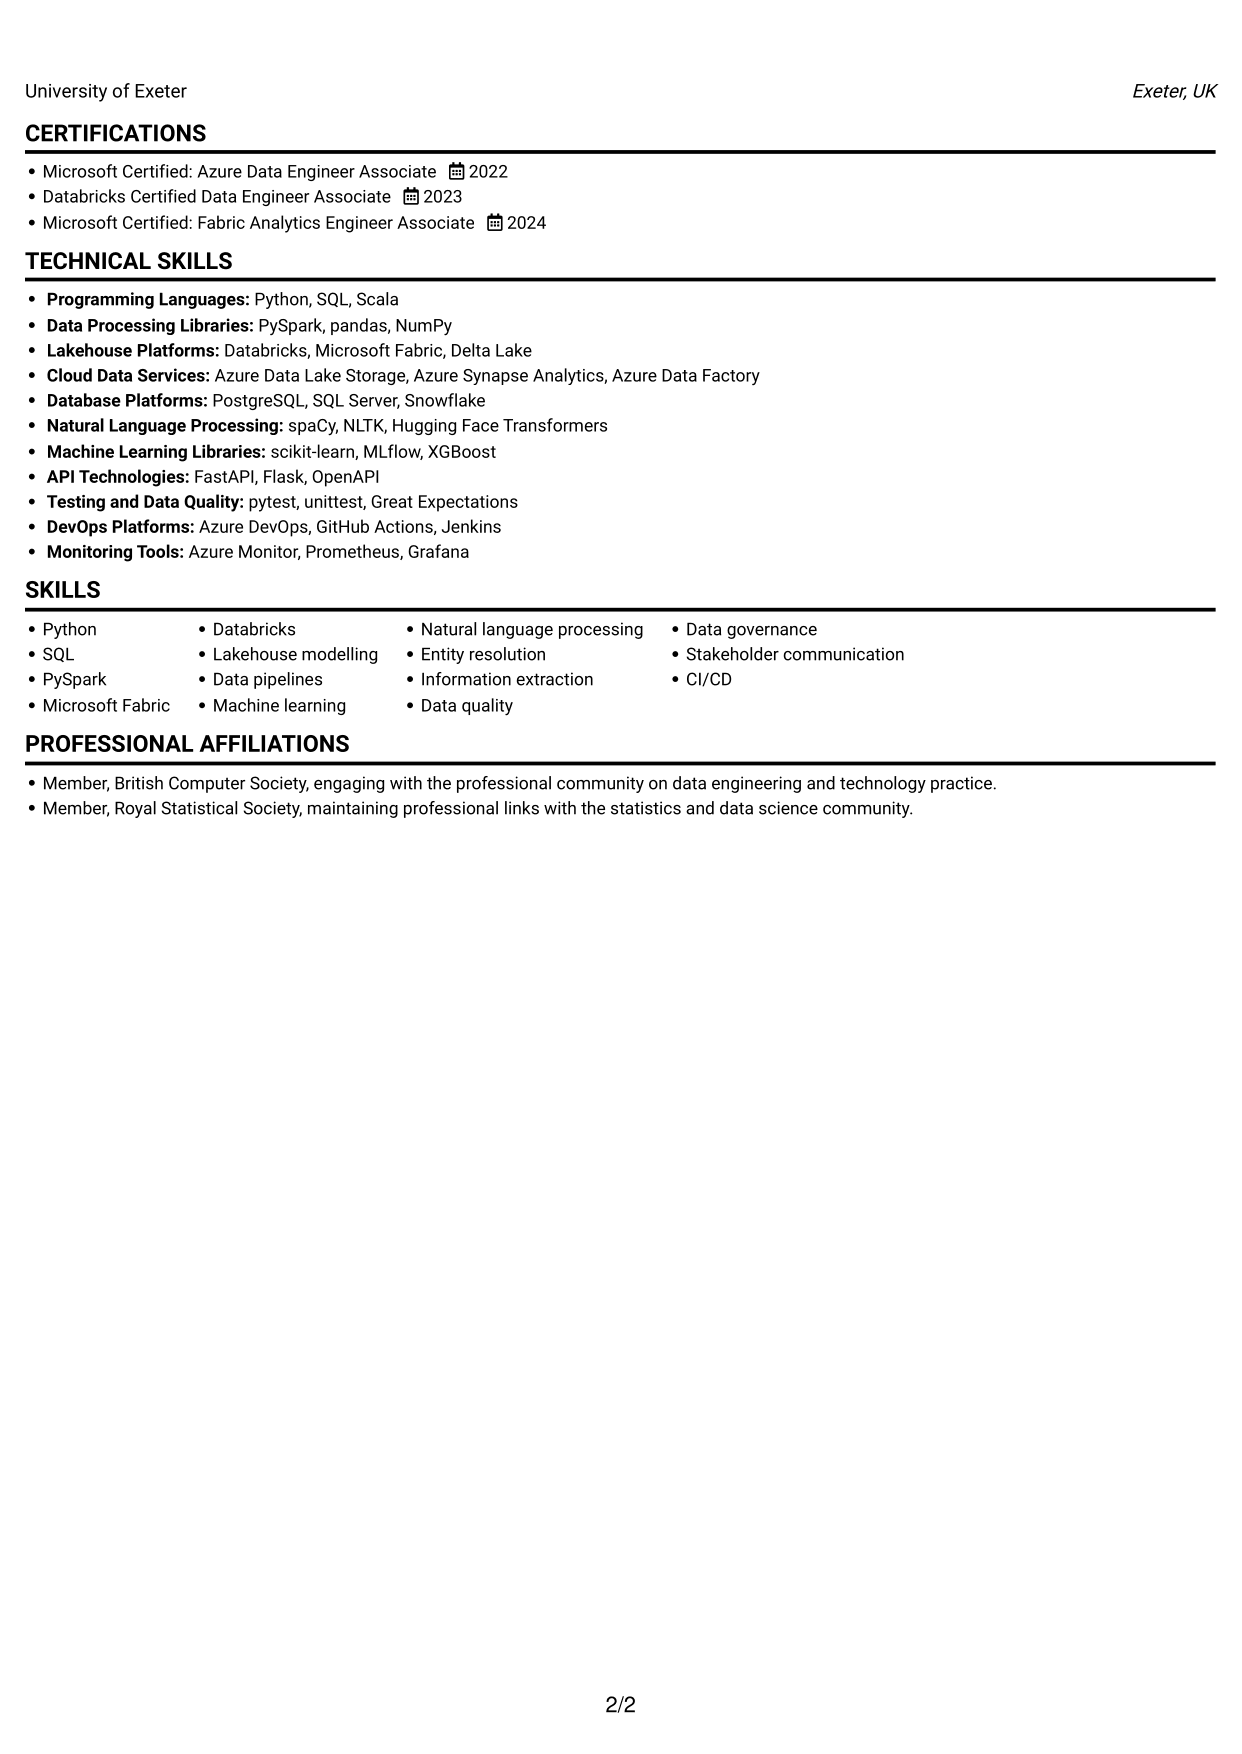
#1 Simple One Column Format CV Example

A single-column body gives this CV a direct reading route, helping reviewers follow its sections in order.
 
CV example — page 1   CV example — page 2

Why This Format Works

  • A clear experience sequence helps reviewers follow career progression across successive roles.
  • Achievement bullets can be read alongside their role details in one path.
  • The shared text flow keeps skills and education connected to the wider CV.

Best For

  • One-column reading preference
  • Chronological career histories
  • Bulleted achievement records
  • Text-led applications
  • CVs with several evidence sections

CV Keywords

  • Python
  • SQL
  • PySpark
  • Microsoft Fabric
  • Databricks
  • Productionised analytical services through APIs and orchestrated pipelines
  • machine learning
  • reusable data assets
  • developed lakehouse models and governed datasets in Microsoft Fabric
  • natural language processing
  • entity resolution
  • information extraction
  • Built natural language processing, entity resolution and information extraction workflows for contracts and case documents
  • data products
  • APIs
See all keywords
 

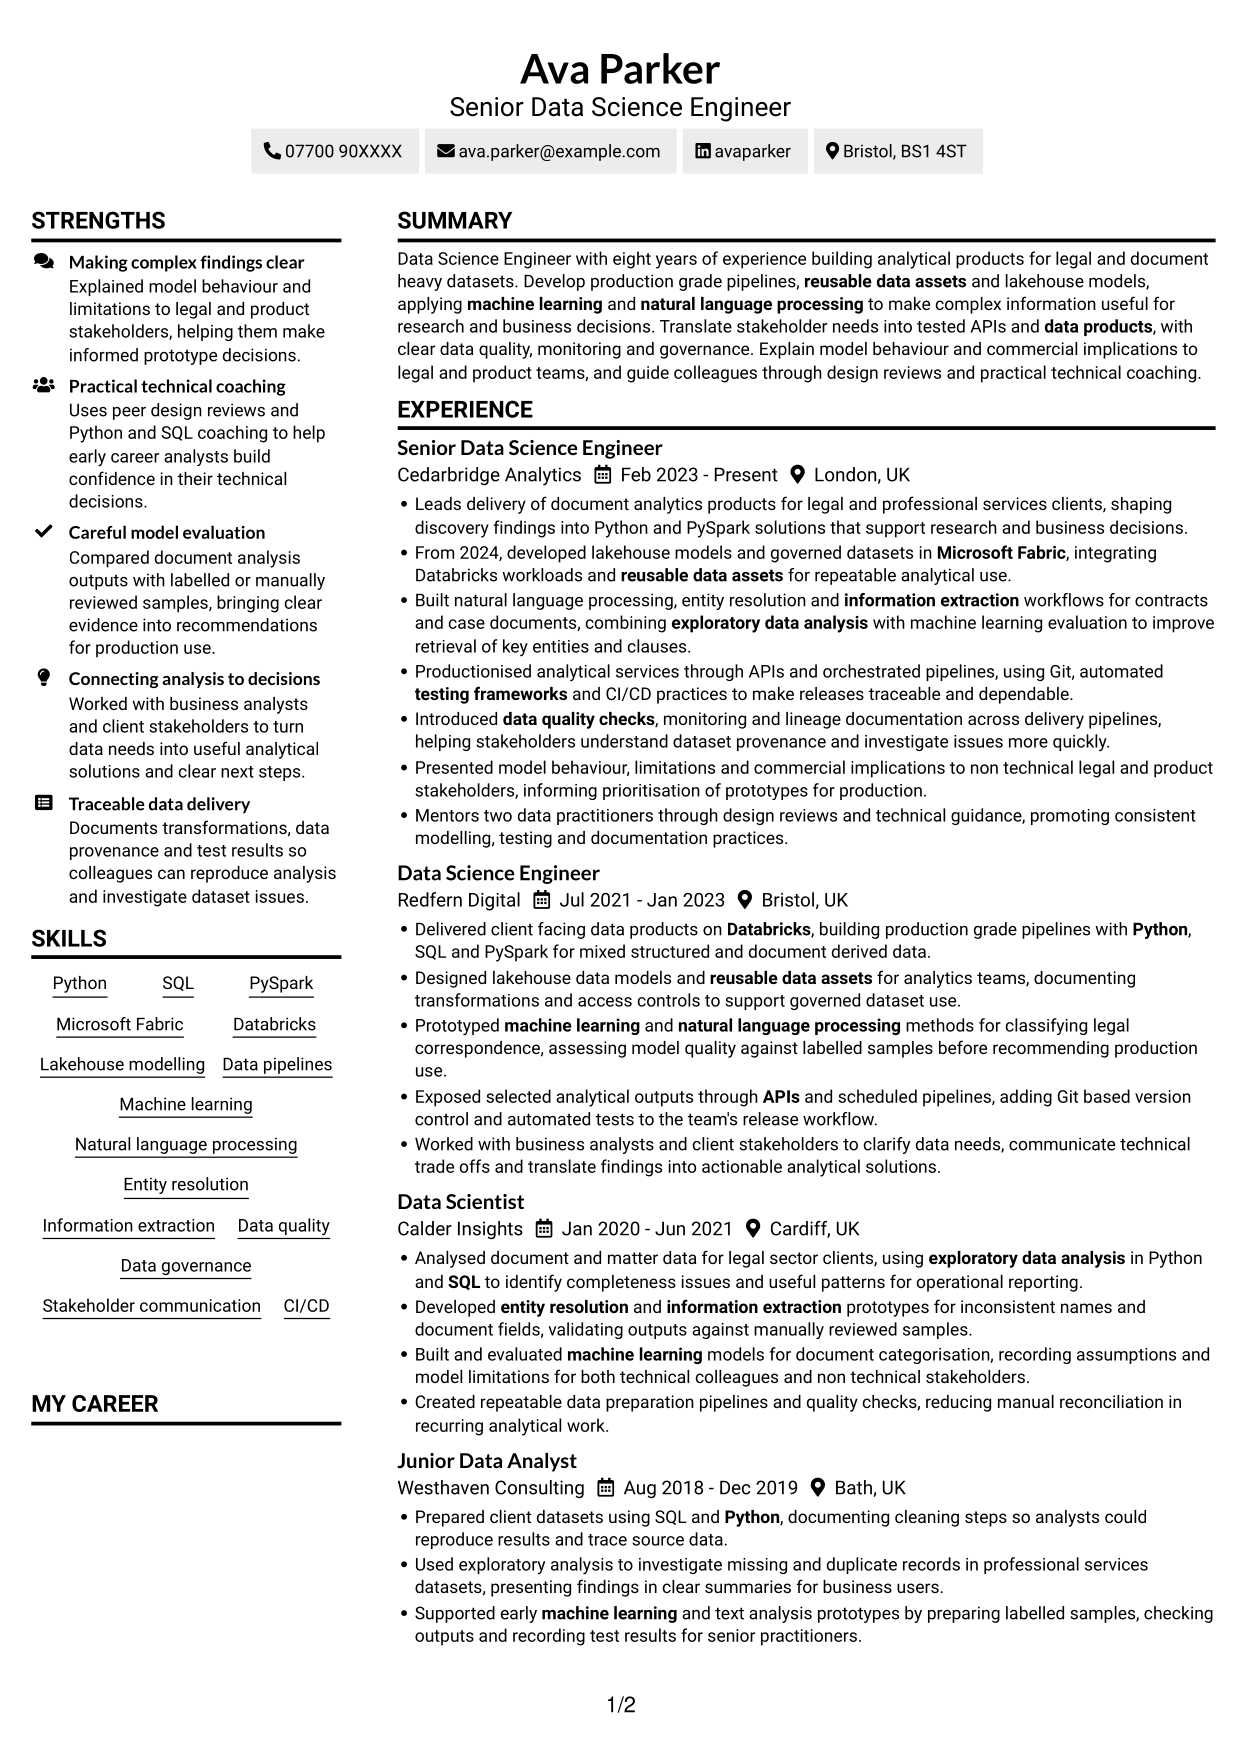
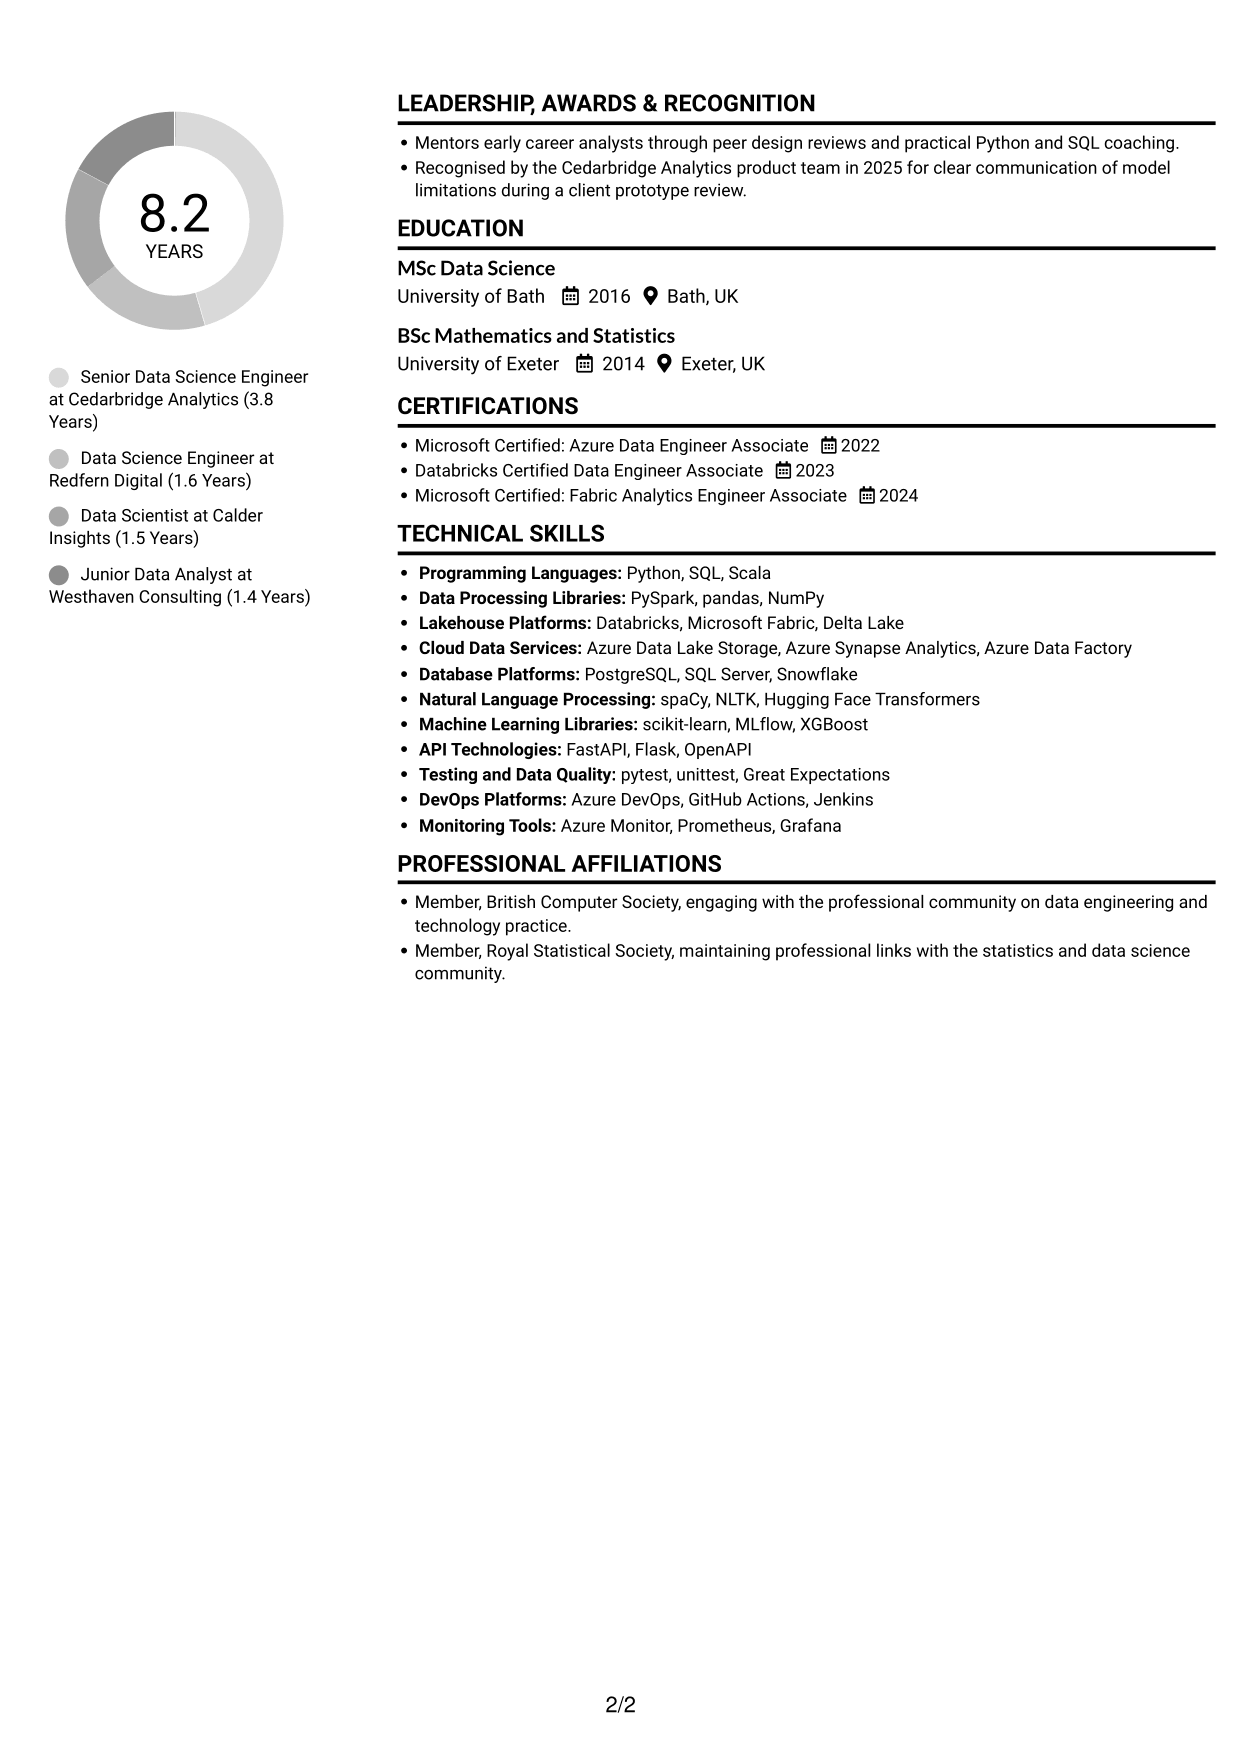
#2 Simple Two Column Format CV Example

The two-column body places CV content in parallel areas, a practical choice for readers who prefer grouped information.
 
CV example — page 1   CV example — page 2

Why This Format Works

  • Experience details remain easier to follow when set apart from supporting sections.
  • A two-column reading order helps reviewers scan varied CV sections efficiently.
  • Skills and credentials can be found without reading every work detail.

Best For

  • Two-column reading preference
  • CVs with varied section types
  • Quick section navigation
  • Text-rich career records
  • Parallel content grouping

#3 Plain One Column with Shaded Labels CV Example

This one-column format keeps CV sections in a vertical order, suiting readers who prefer a familiar linear read.
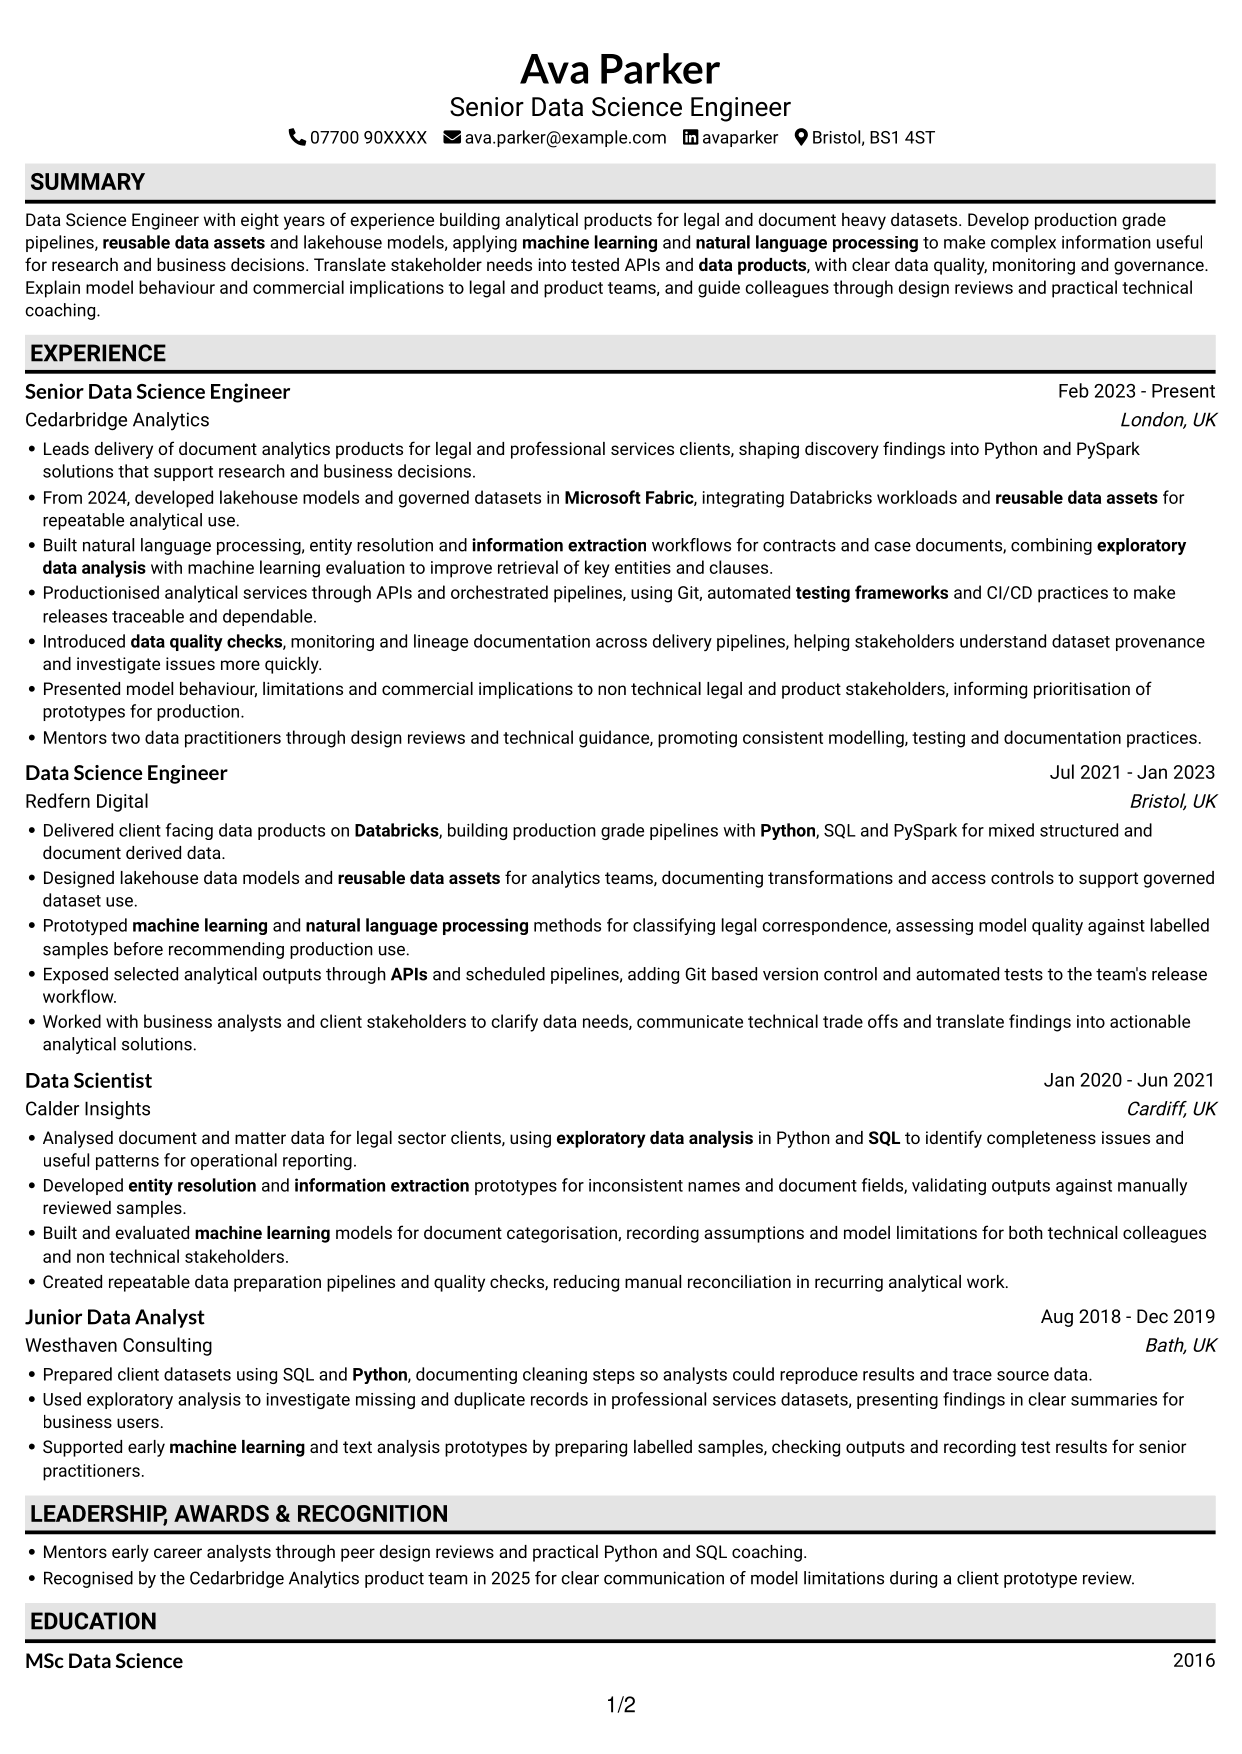
 
CV example — page 1   CV example — page 2

Why This Format Works

  • The vertical sequence lets reviewers trace career history from role to role.
  • Education and credentials stay within the same reading route as experience.
  • A single content path helps readers return to skills without crossing columns.

Best For

  • Linear CV reading
  • Sequential career histories
  • CVs with several section types
  • Text-first applications
  • Simple content navigation
 

#4 One Column Format with Photo Right CV Example

A photo accompanies the single-column body, offering a portrait-led option while keeping CV content in one reading route.
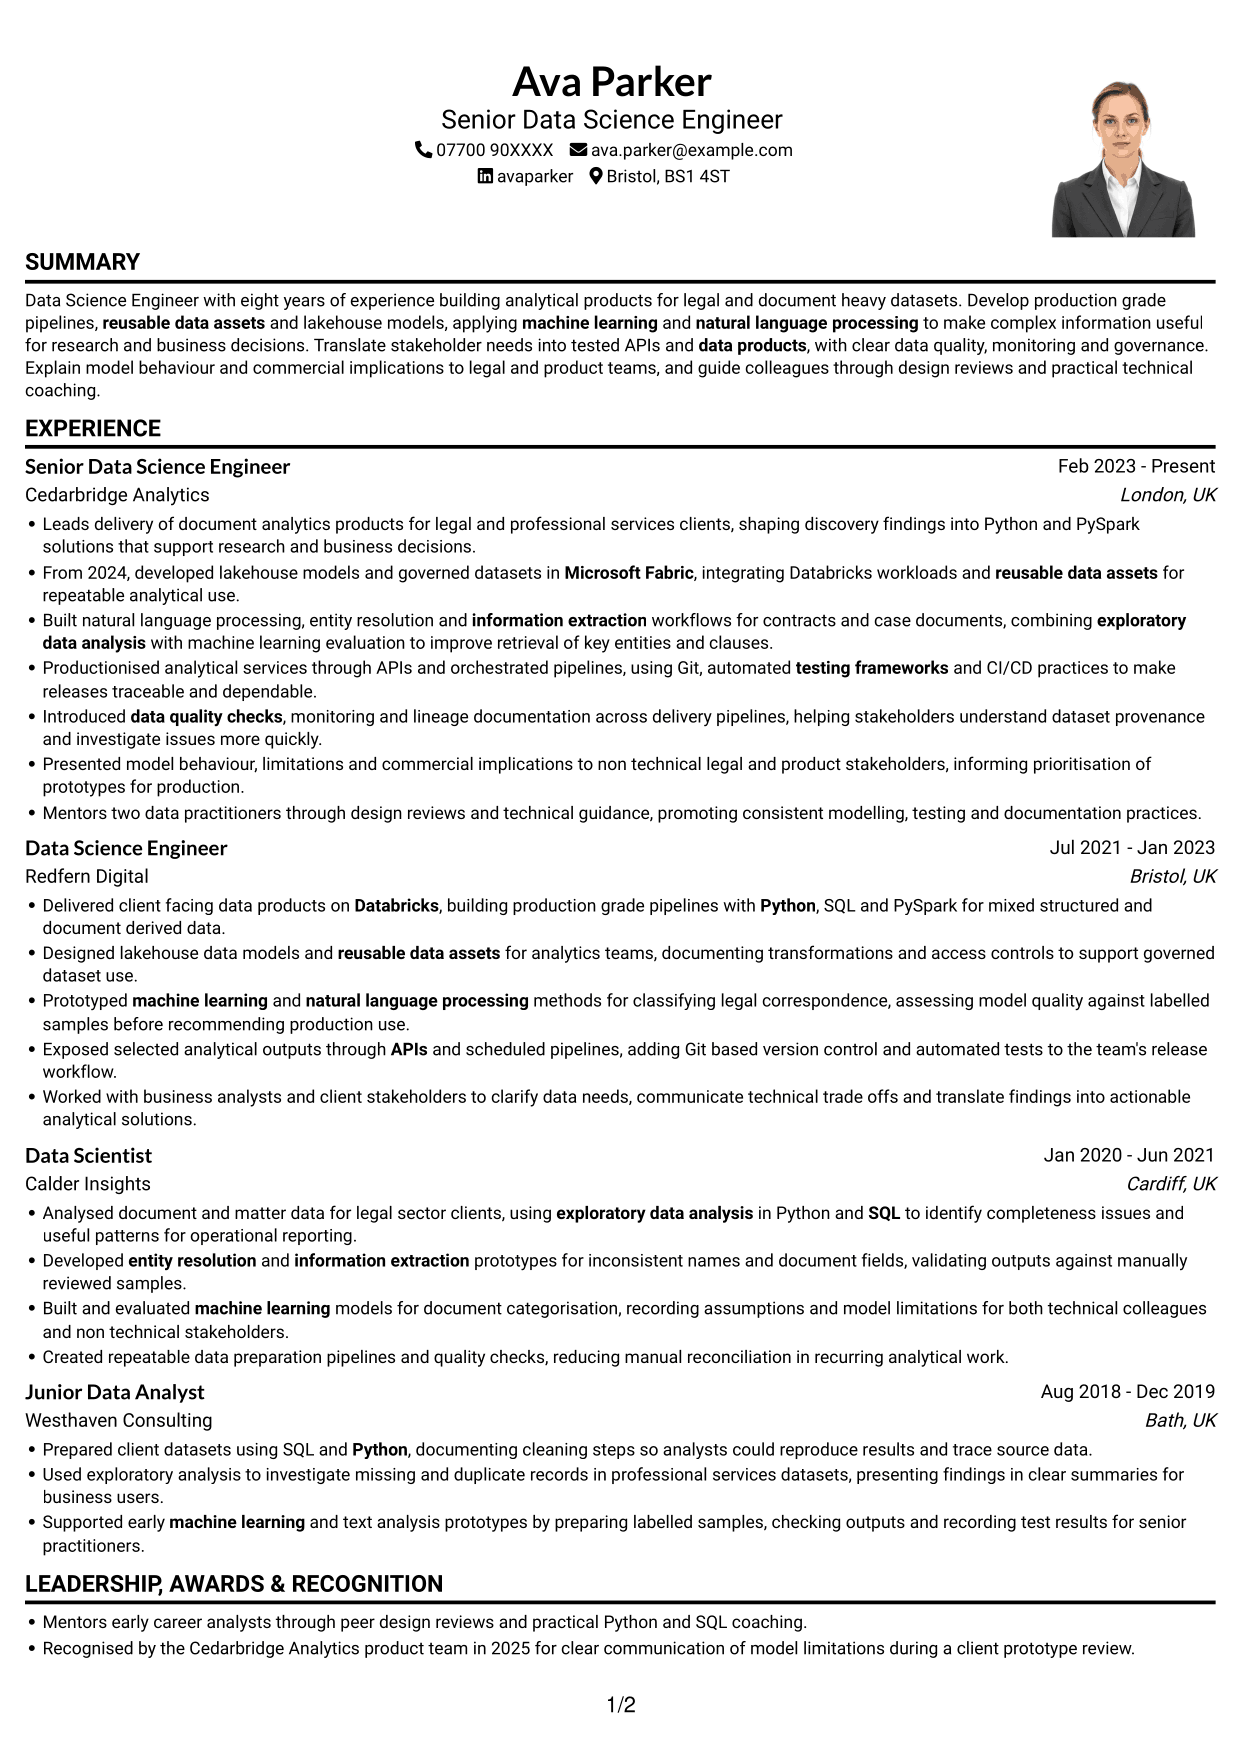
 
CV example — page 1   CV example — page 2

Why This Format Works

  • Experience entries follow one route, making career progression clear to reviewers.
  • The continuous content order keeps achievement details with their related roles.
  • Education and skills remain within the same direct reading path.

Best For

  • CVs with a portrait
  • Single-column reading preference
  • Career histories in date order
  • Achievement-led work records
  • Personal visual presentation
 

#5 Clean Two Column Sidebar Format CV Example

The two-column body groups CV content in parallel areas, giving readers a clear alternative to a single vertical sequence.
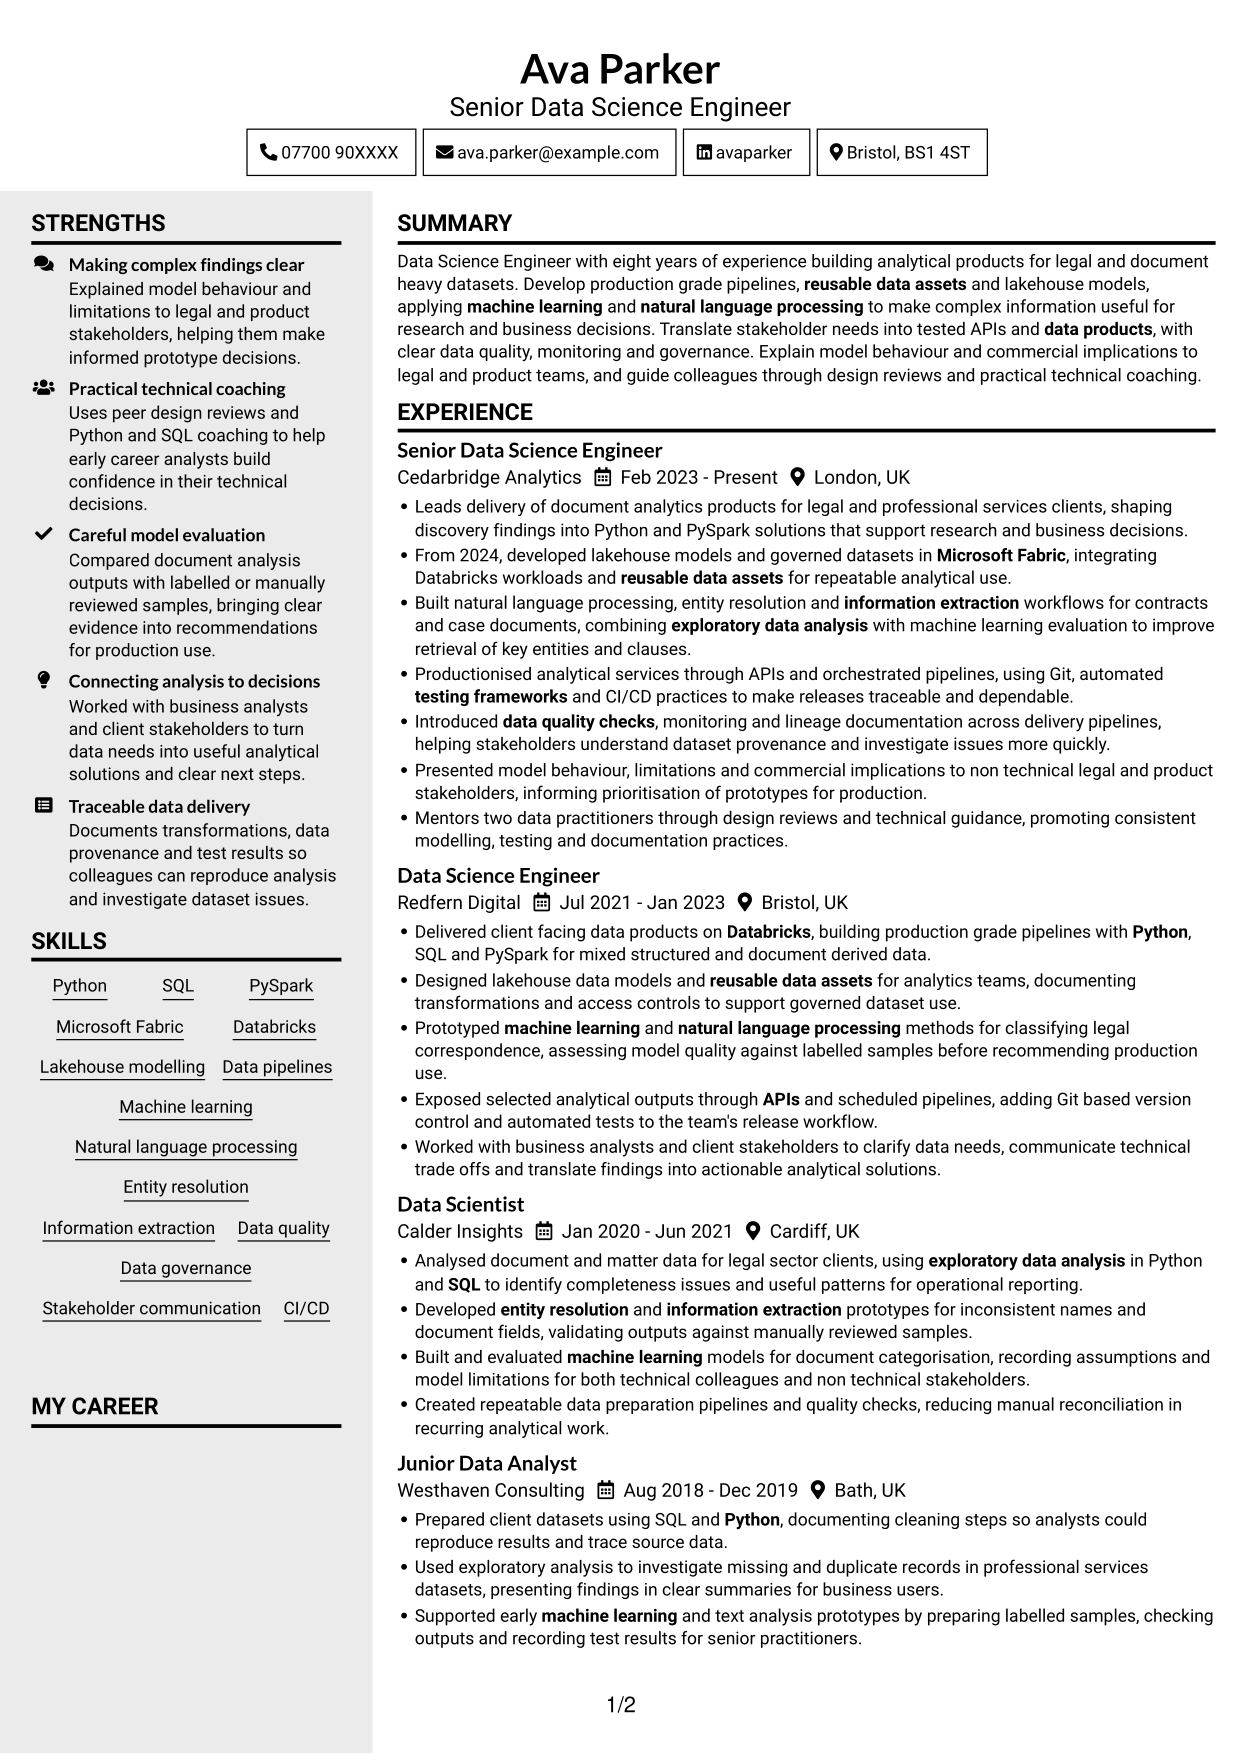
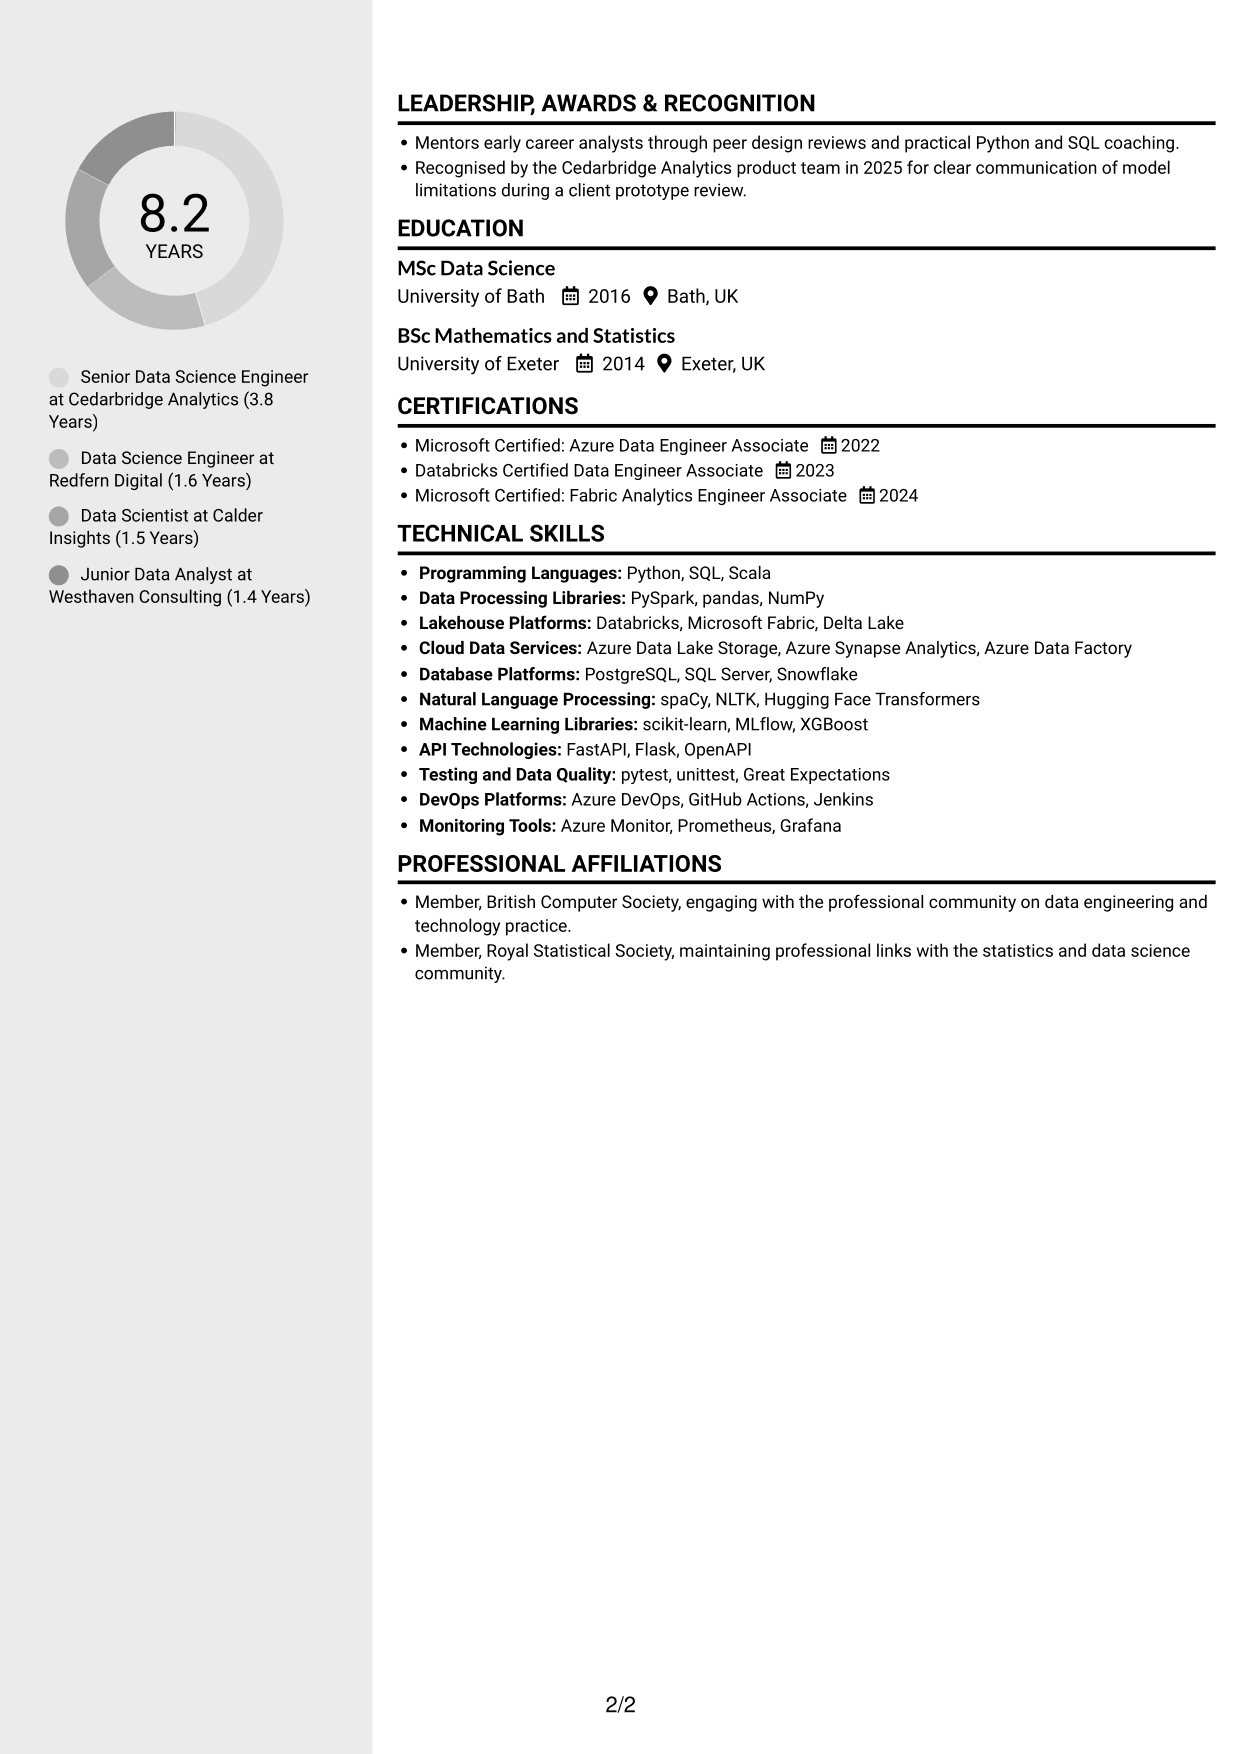
 
CV example — page 1   CV example — page 2

Why This Format Works

  • Distinct column areas help reviewers move between experience and other CV sections.
  • Role details stay together, supporting a clear view of career progression.
  • Skills and education are easier to locate across the grouped content.

Best For

  • Parallel content organisation
  • CVs with varied section types
  • Readers who scan by section
  • Career history with supporting evidence
  • Two-column reading preference


#6 Two Column Format CV Example

Two columns provide a compact way to arrange CV sections side by side for readers who value a grouped view.
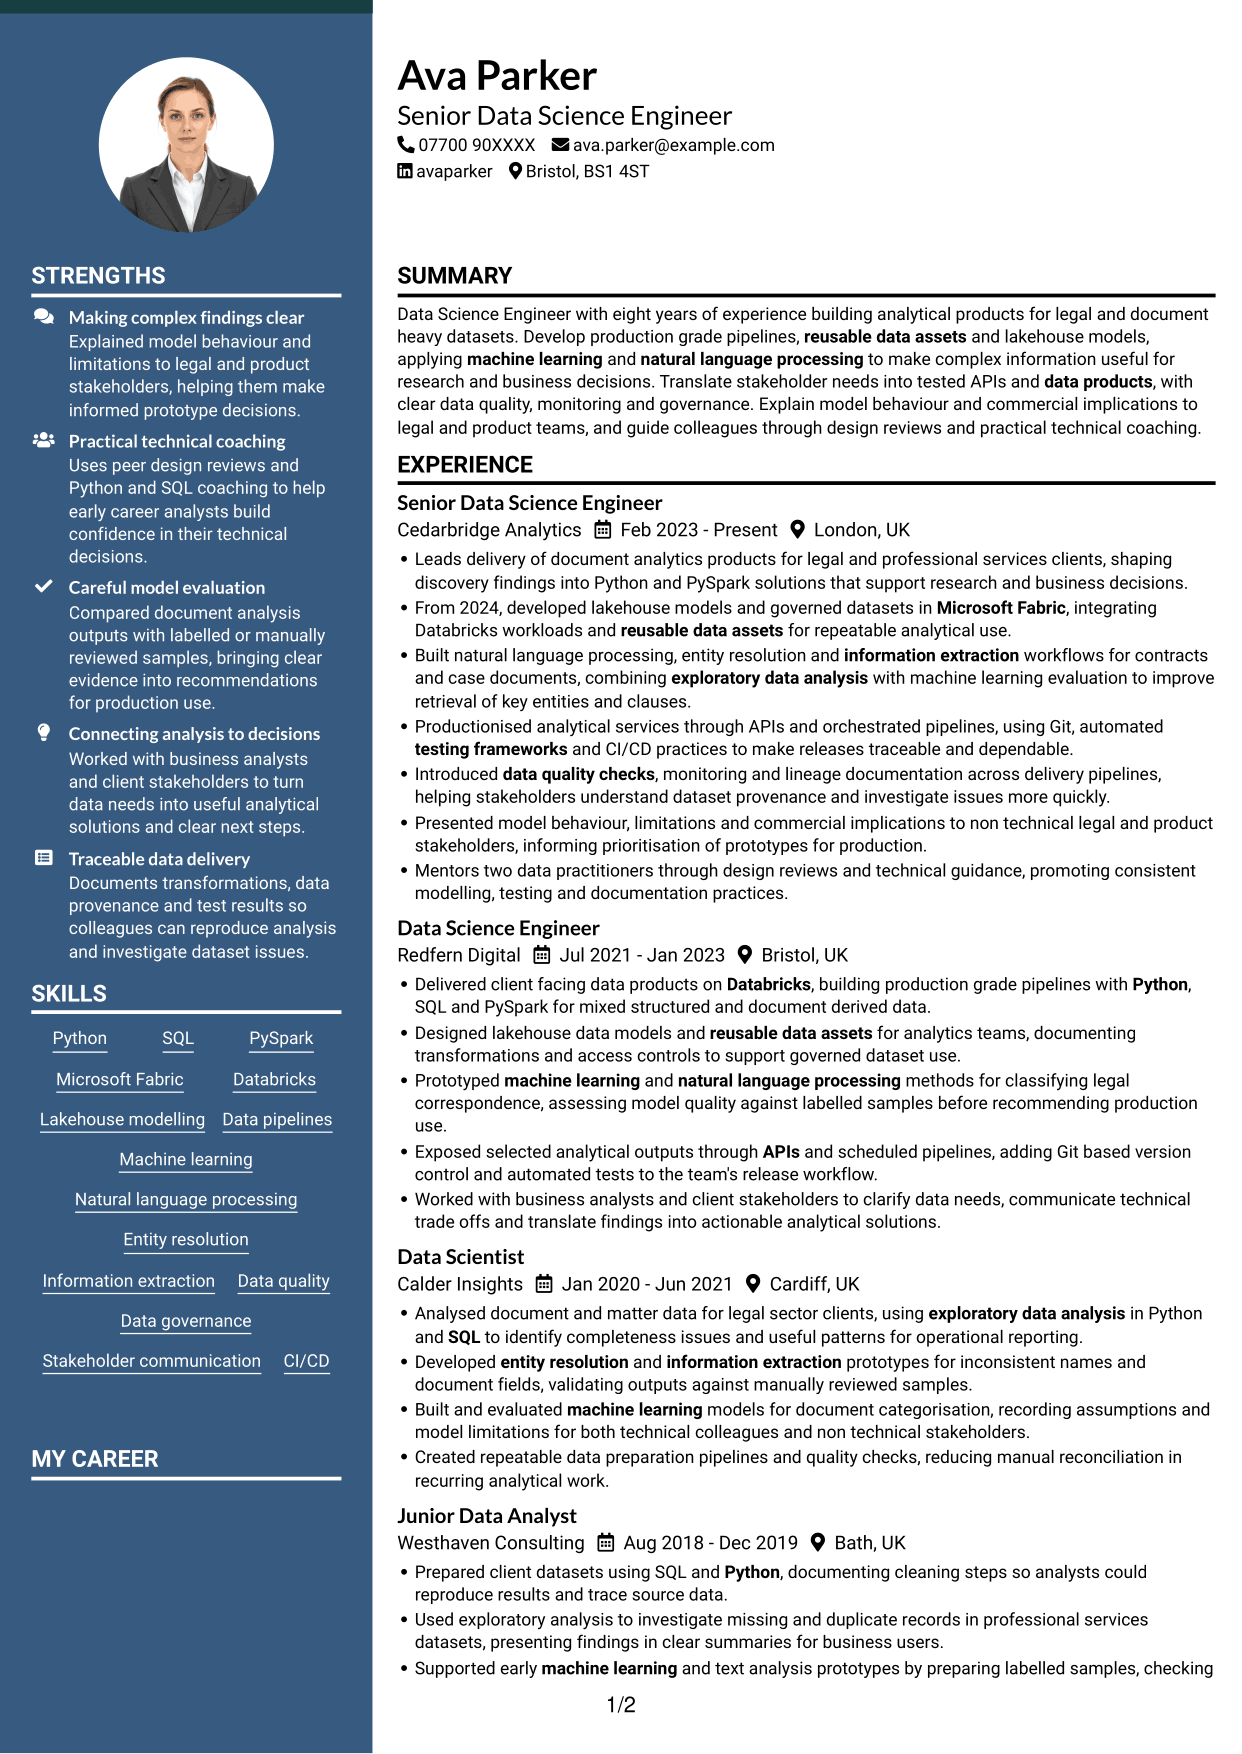
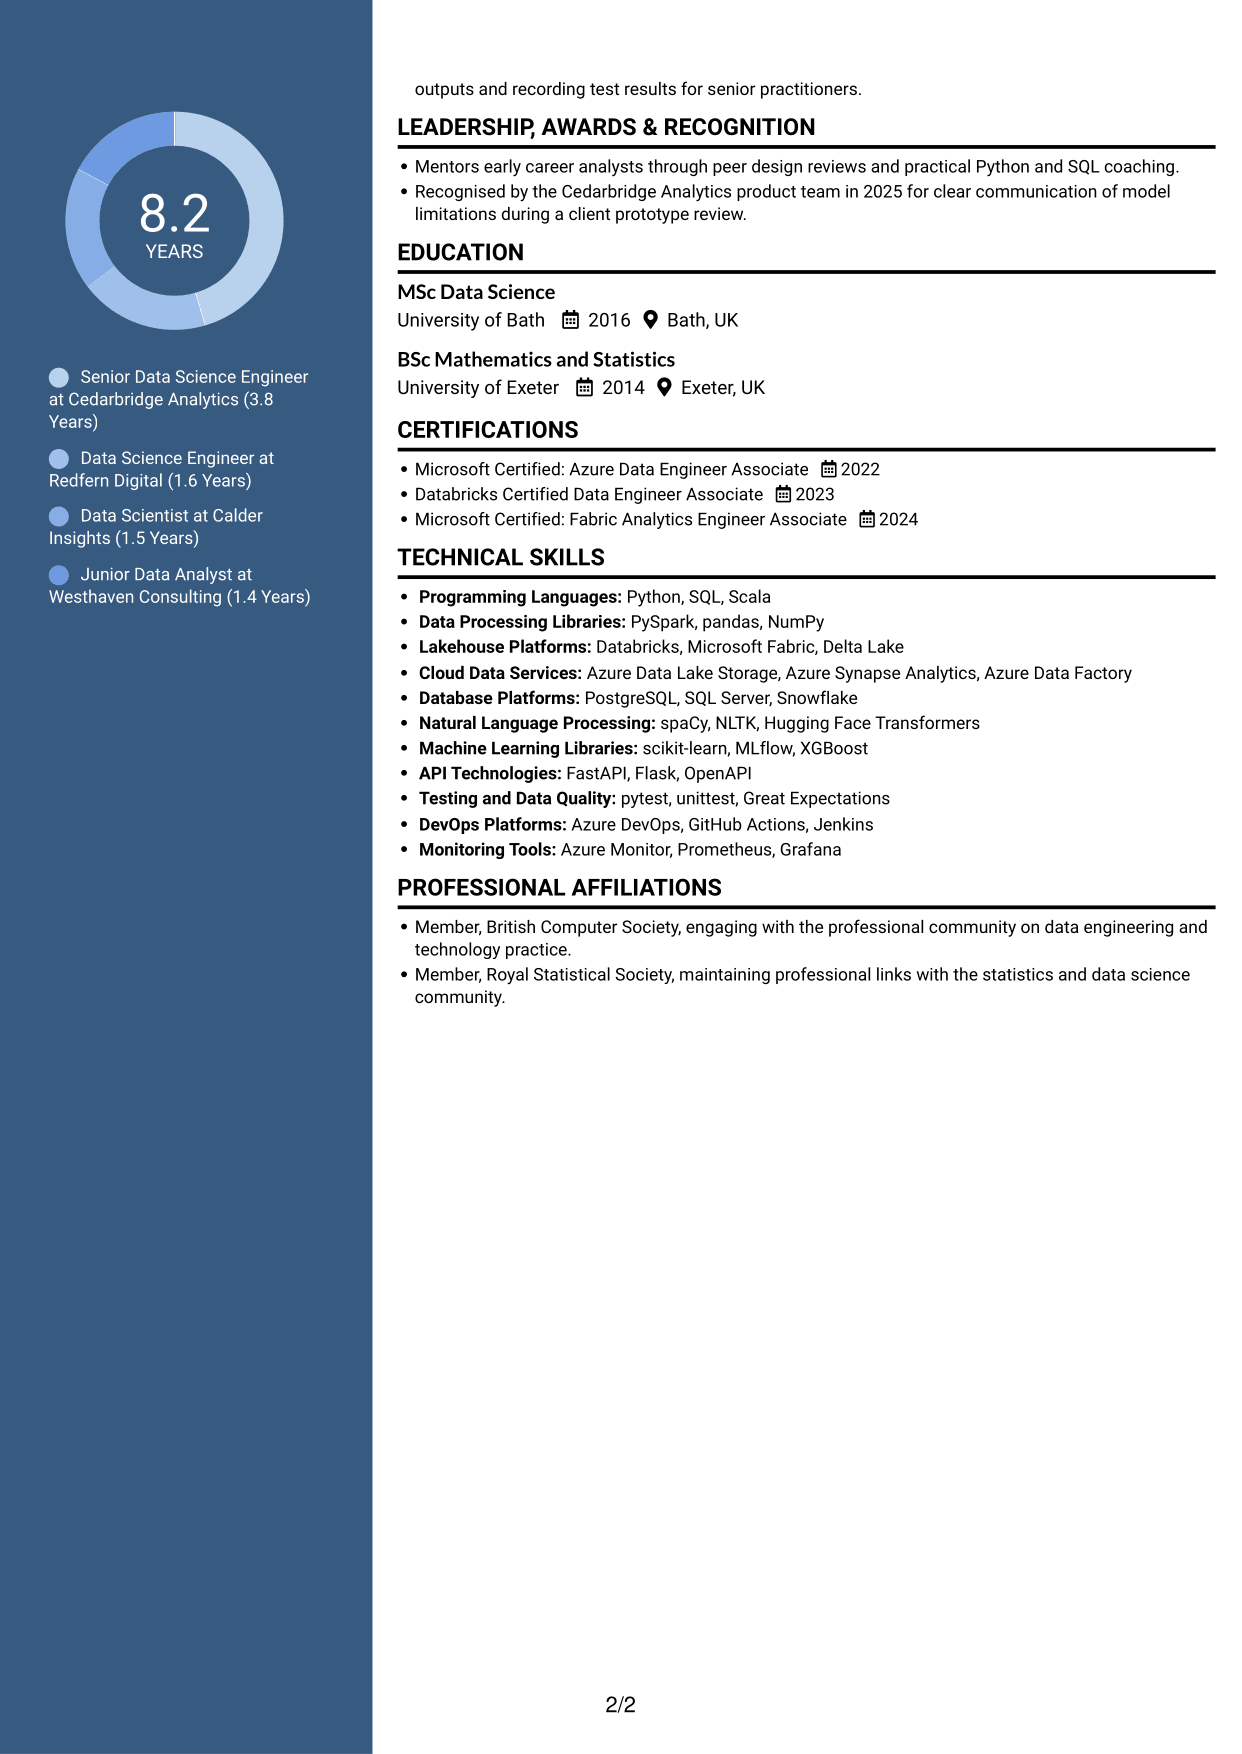
 
CV example — page 1   CV example — page 2

Why This Format Works

  • The parallel areas let reviewers scan career history and supporting sections separately.
  • Experience bullets remain grouped, helping readers track changes across roles.
  • Education and credentials are accessible without following every achievement bullet.

Best For

  • Side-by-side section organisation
  • CVs with multiple content areas
  • Fast section scanning
  • Detailed career records
  • Readers who prefer grouped information
 

#7 Photo Header Two Column Format CV Example

A photo paired with two body columns suits readers who want a portrait as well as grouped CV content.
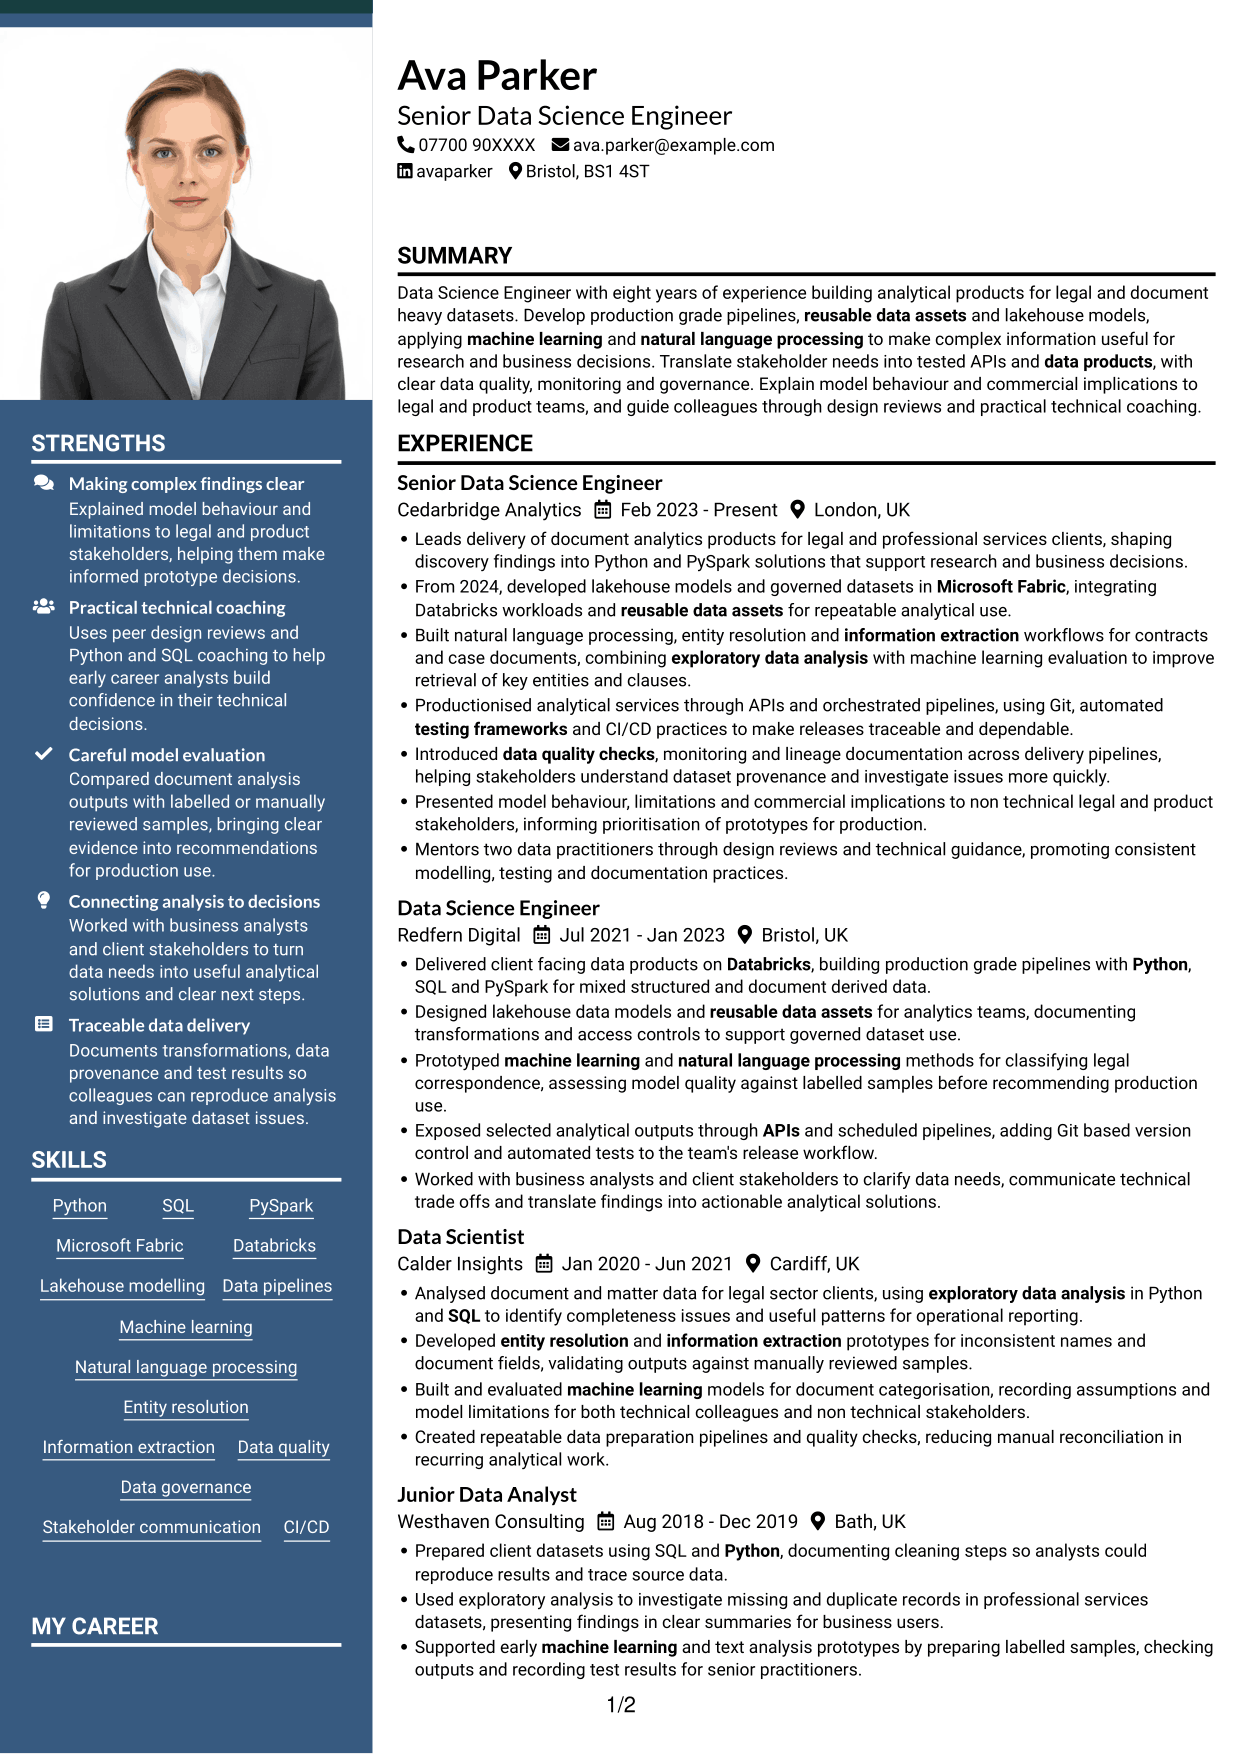
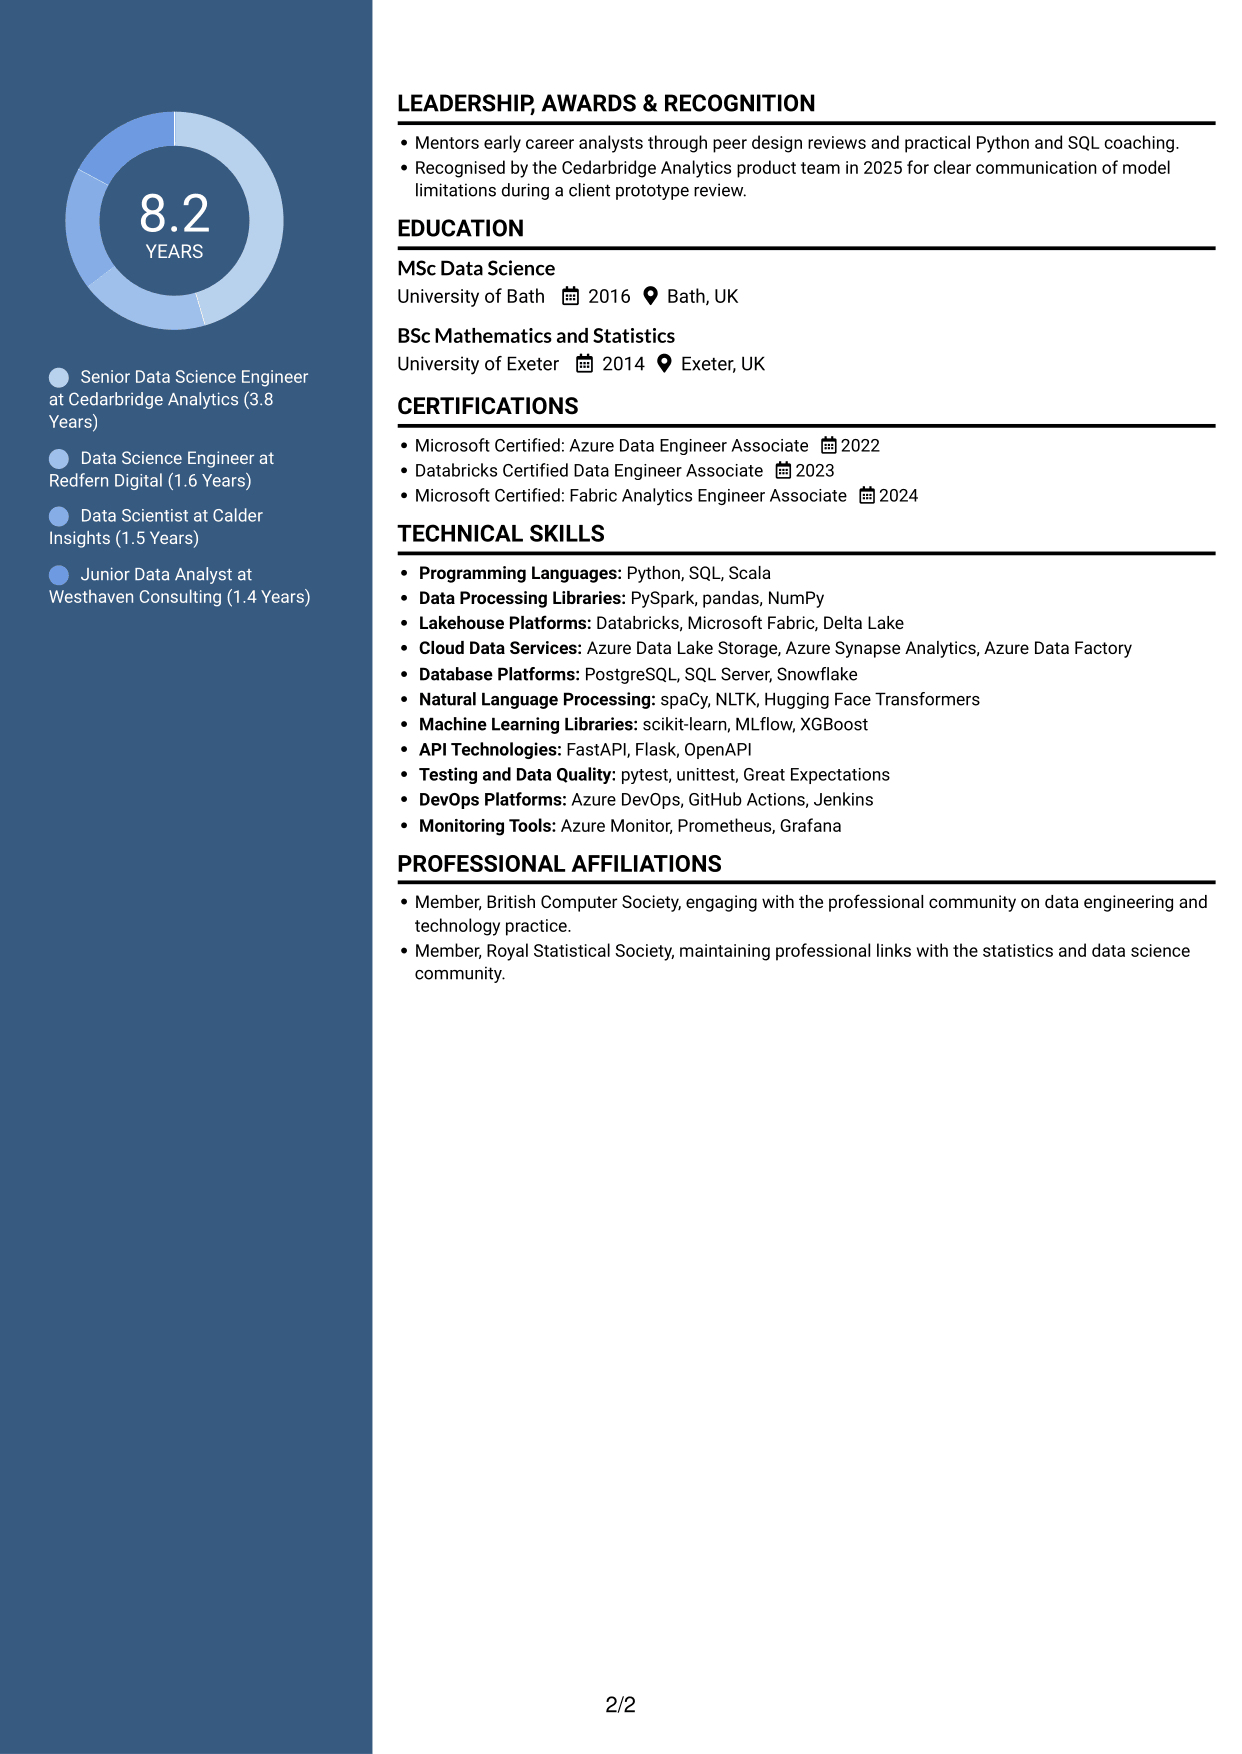
 
CV example — page 1   CV example — page 2

Why This Format Works

  • The two-column body gives career history and other sections distinct reading areas.
  • Grouped experience details help reviewers follow progression across roles.
  • Skills and credentials can be located without moving through every work entry.

Best For

  • Two-column CV organisation
  • CVs with a portrait
  • Grouped section reading
  • Career histories with detailed evidence
  • Personal visual presentation


Why Build Your Data Science Engineer - Legal Document Analytics CV with ResumeInMinutes

ResumeInMinutes lets you compare CV examples and review how each layout presents technical skills, experience and education. View the PNG image previews, then open an example in the editor to customise its content and layout.

  • Clear CV layouts
  • Readable section structure
  • Space for role-specific keywords
  • Organised skills and experience
  • PNG image previews
  • CV customisation in the editor

Choose a format that makes your work easy to follow. Keep the focus on production-grade pipelines, legal document analysis, data quality and the decisions your work supports.


See Also


Frequently Asked Questions

Are these Data Science Engineer - Legal Document Analytics CV templates suitable for ATS review?

Use clear headings and a simple section order to help systems and recruiters scan your CV. Include relevant terms naturally, such as Python, SQL, PySpark, Microsoft Fabric, Databricks and data governance.

Are these separate CV examples or different layouts of one example?

This page shows one role-focused CV example in different layouts. Compare the PNG image previews, then open an example in the editor to customise it.

What should a Data Science Engineer - Legal Document Analytics CV include?

Include a focused summary, relevant experience, technical skills and education. Show evidence of pipelines, lakehouse models, document analytics, machine learning, APIs, data quality and communication with non-technical stakeholders.

Which CV layout works well for this role?

Choose a layout with clear headings and an easy-to-follow order for experience, skills and education. A simple structure helps readers find your technical evidence quickly.

How can I show legal document analytics achievements on my CV?

Write concise bullet points that explain the task, your contribution and the outcome. Where you have reliable figures, use them to show the effect of your work on data quality, retrieval or delivery.

Should I include a photo on my CV?

For UK applications, a photo is usually not needed. Use the space for relevant skills, experience and evidence of your results instead.
ATS Score 100%

How we calculate this score

  • Keywords: 60% of the total. AI extracts keywords from your job description. If you do not provide one, a standard job description for the title matching your CV is used. This is not a match to a specific vacancy.
  • Text-based CV: 20%. The text CV assessed here receives 100 for this part.
  • CV quality: 20%. We start at 100 and subtract points for issues found by our CV checks, down to a minimum of zero.
  • Keyword coverage = round(100 × confirmed matches ÷ total keywords). Exact matches and supported equivalents verified by AI receive full credit; unsupported keywords receive none. Live text checks use the saved equivalents and do not request a new AI review. Without keywords, no overall ATS score is available.
  • Final score = 60% of keyword coverage + 20% of the text score + 20% of the quality score, rounded to a whole number. Without keywords, no overall ATS score is available.

What this score means

Our scores are estimates, not employer ratings. They may contain errors and do not guarantee accurate parsing, a ranking, an interview, or a job. Check your document against the employer’s requirements. You are responsible for relying on this score.

Terms and Conditions

Score weights: Keywords 60% · Text based CV 20% · CV quality 20%

Keyword coverage: 26 of 26 (100%) · CV quality: 100%

CV quality 100% · Weight 20% · Issues (0)

Details
  • ✓Name present: Ava Parker
  • ✓Email format: ava.parker@example.com
  • ✓Phone format: 07700 90XXXX
  • ✓Experience 1: Job title: Senior Data Science Engineer
  • ✓Experience 1: Company name: Cedarbridge Analytics
  • ✓Experience 1: Work location: London, UK
  • ✓Experience 1: Employment dates: Feb 2023 - Present
  • ✓Experience 1: Description or achievements: Present
  • ✓Experience 2: Job title: Data Science Engineer
  • ✓Experience 2: Company name: Redfern Digital
  • ✓Experience 2: Work location: Bristol, UK
  • ✓Experience 2: Employment dates: Jul 2021 - Jan 2023
  • ✓Experience 2: Description or achievements: Present
  • ✓Experience 3: Job title: Data Scientist
  • ✓Experience 3: Company name: Calder Insights
  • ✓Experience 3: Work location: Cardiff, UK
  • ✓Experience 3: Employment dates: Jan 2020 - Jun 2021
  • ✓Experience 3: Description or achievements: Present
  • ✓Experience 4: Job title: Junior Data Analyst
  • ✓Experience 4: Company name: Westhaven Consulting
  • ✓Experience 4: Work location: Bath, UK
  • ✓Experience 4: Employment dates: Aug 2018 - Dec 2019
  • ✓Experience 4: Description or achievements: Present
  • ✓No placeholder fields
  • ✓No repeated achievement bullets
  • ✓No empty bullets

No issues found by the current checks.

Text Based CV 100% · Weight 20%

Parsed text
Ava Parker
07700 90XXXX
ava.parker@example.com
avaparker
Bristol, BS1 4ST
SUMMARY
Data Science Engineer with eight years of experience building analytical products for legal and document heavy datasets. Develop production grade pipelines, reusable data assets and lakehouse models, applying machine learning and natural language processing to make complex information useful for research and business decisions. Translate stakeholder needs into tested APIs and data products, with clear data quality, monitoring and governance. Explain model behaviour and commercial implications to legal and product teams, and guide colleagues through design reviews and practical technical coaching.
EXPERIENCE
Senior Data Science Engineer
Feb 2023 - Present
Cedarbridge Analytics
London, UK
Leads delivery of document analytics products for legal and professional services clients, shaping discovery findings into Python and PySpark solutions that support research and business decisions.
From 2024, developed lakehouse models and governed datasets in Microsoft Fabric, integrating Databricks workloads and reusable data assets for repeatable analytical use.
Built natural language processing, entity resolution and information extraction workflows for contracts and case documents, combining exploratory data analysis with machine learning evaluation to improve retrieval of key entities and clauses.
Productionised analytical services through APIs and orchestrated pipelines, using Git, automated testing frameworks and CI/CD practices to make releases traceable and dependable.
Introduced data quality checks, monitoring and lineage documentation across delivery pipelines, helping stakeholders understand dataset provenance and investigate issues more quickly.
Presented model behaviour, limitations and commercial implications to non technical legal and product stakeholders, informing prioritisation of prototypes for production.
Mentors two data practitioners through design reviews and technical guidance, promoting consistent modelling, testing and documentation practices.
Data Science Engineer
Jul 2021 - Jan 2023
Redfern Digital
Bristol, UK
Delivered client facing data products on Databricks, building production grade pipelines with Python, SQL and PySpark for mixed structured and document derived data.
Designed lakehouse data models and reusable data assets for analytics teams, documenting transformations and access controls to support governed dataset use.
Prototyped machine learning and natural language processing methods for classifying legal correspondence, assessing model quality against labelled samples before recommending production use.
Exposed selected analytical outputs through APIs and scheduled pipelines, adding Git based version control and automated tests to the team's release workflow.
Worked with business analysts and client stakeholders to clarify data needs, communicate technical trade offs and translate findings into actionable analytical solutions.
Data Scientist
Jan 2020 - Jun 2021
Calder Insights
Cardiff, UK
Analysed document and matter data for legal sector clients, using exploratory data analysis in Python and SQL to identify completeness issues and useful patterns for operational reporting.
Developed entity resolution and information extraction prototypes for inconsistent names and document fields, validating outputs against manually reviewed samples.
Built and evaluated machine learning models for document categorisation, recording assumptions and model limitations for both technical colleagues and non technical stakeholders.
Created repeatable data preparation pipelines and quality checks, reducing manual reconciliation in recurring analytical work.
Junior Data Analyst
Aug 2018 - Dec 2019
Westhaven Consulting
Bath, UK
Prepared client datasets using SQL and Python, documenting cleaning steps so analysts could reproduce results and trace source data.
Used exploratory analysis to investigate missing and duplicate records in professional services datasets, presenting findings in clear summaries for business users.
Supported early machine learning and text analysis prototypes by preparing labelled samples, checking outputs and recording test results for senior practitioners.
LEADERSHIP, AWARDS & RECOGNITION
Mentors early career analysts through peer design reviews and practical Python and SQL coaching.
Recognised by the Cedarbridge Analytics product team in 2025 for clear communication of model limitations during a client prototype review.
EDUCATION
MSc Data Science
2016
University of Bath
Bath, UK
BSc Mathematics and Statistics
2014
University of Exeter
Exeter, UK
CERTIFICATIONS
Microsoft Certified: Azure Data Engineer Associate
2022
Databricks Certified Data Engineer Associate
2023
Microsoft Certified: Fabric Analytics Engineer Associate
2024
TECHNICAL SKILLS
Programming Languages: Python, SQL, Scala
Data Processing Libraries: PySpark, pandas, NumPy
Lakehouse Platforms: Databricks, Microsoft Fabric, Delta Lake
Cloud Data Services: Azure Data Lake Storage, Azure Synapse Analytics, Azure Data Factory
Database Platforms: PostgreSQL, SQL Server, Snowflake
Natural Language Processing: spaCy, NLTK, Hugging Face Transformers
Machine Learning Libraries: scikit-learn, MLflow, XGBoost
API Technologies: FastAPI, Flask, OpenAPI
Testing and Data Quality: pytest, unittest, Great Expectations
DevOps Platforms: Azure DevOps, GitHub Actions, Jenkins
Monitoring Tools: Azure Monitor, Prometheus, Grafana
SKILLS
Python
SQL
PySpark
Microsoft Fabric
Databricks
Lakehouse modelling
Data pipelines
Machine learning
Natural language processing
Entity resolution
Information extraction
Data quality
Data governance
Stakeholder communication
CI/CD
PROFESSIONAL AFFILIATIONS
Member, British Computer Society, engaging with the professional community on data engineering and technology practice.
Member, Royal Statistical Society, maintaining professional links with the statistics and data science community.

Matched keywords (26)

  • Python
  • SQL
  • PySpark
  • Microsoft Fabric
  • Databricks
  • Productionised analytical services through APIs and orchestrated pipelinesOriginal keyword in JD: Production-grade data pipelines
  • machine learning
  • reusable data assets
  • developed lakehouse models and governed datasets in Microsoft FabricOriginal keyword in JD: Scalable lakehouse data modelling
  • natural language processingOriginal keyword in JD: Natural language processing (NLP)
  • entity resolution
  • information extraction
  • Built natural language processing, entity resolution and information extraction workflows for contracts and case documentsOriginal keyword in JD: Legal document analytics
  • data products
  • APIs
  • data quality checks
  • Introduced data quality checks, monitoring and lineage documentation across delivery pipelinesOriginal keyword in JD: Data monitoring
  • Introduced data quality checks, monitoring and lineage documentation across delivery pipelinesOriginal keyword in JD: Data lineage
  • Data governance
  • Git
  • testing frameworks
  • CI/CD
  • exploratory data analysis
  • Stakeholder communication
  • Presented model behaviour, limitations and commercial implications to non technical legal and product stakeholdersOriginal keyword in JD: Communicating technical concepts to non-technical audiences
  • Presented model behaviour, limitations and commercial implicationsOriginal keyword in JD: Explaining business impact

Missing keywords (0)

No missing keywords.

Disclaimer: All names, images, contact information, employment histories, achievements, security clearances, military credentials, and other qualifications shown in this content are fictional and used for illustrative purposes only. Any resemblance to actual persons, living or deceased, is purely coincidental.

CV and cover letter examples and recommendations in this article reflect general best practices and professional experience and are provided for guidance only. Results may vary based on role, industry, region, and hiring organisation.

Content Accuracy and Verification: To the fullest extent permitted by applicable law, we do not represent or warrant that CV or cover letter guidance, examples, recommendations, or related information are accurate, complete, current, error-free, or suitable for any particular purpose. You are responsible for independently reviewing and verifying the information before relying on it.

ATS and Cover Letter Scores: ATS scores are estimates calculated using our own formula, informed by publicly available guidance on CV formatting and keyword matching. They are not scores issued or endorsed by an ATS provider or employer. Cover letter scores are also our own assessments. Parsing, weighting, screening criteria, and results vary between systems, employers, job descriptions, and document formats. No score guarantees successful parsing, a particular ranking, an interview, or employment. Use scores as general guidance and independently check your documents against the employer’s requirements. To the fullest extent permitted by applicable law, we accept no liability for errors in scores or parsing, or losses arising from reliance on these assessments. Nothing in this notice excludes liability or limits consumer rights that cannot lawfully be excluded or limited.

Terms and Conditions
 
> JP 1 1
PDF Footer and Margins Setup
The margins are applied to the document, and the footer appears in both the preview and the PDF

Footer Font Settings

Are you applying for a specific job
so we can tailor your CV to it?
Are you applying for a specific job
so we can tailor your cover letter to it?

Your data stays private and is never used for training.Privacy Policy

Type your details as text to generate a personalised CV Type your details as text to generate a personalised cover letter
Website link found! Ready to create CV from:

Your data stays private and is never used for training.Privacy Policy

Drag the into the box to verify you're human.
Drop here

My CVs

Showing {number_of_files} files (out of {total_of_all_files} total)
Name File Type Last Modified: Description:

Rename File

Filename already exists!

Delete Files

Warning: This action is irreversible. Once you click submit, the files will be permanently deleted.

Heading text
Upload From Computer Upload
Select From Existing
LinkedIn
Drag & Drop files anywhere in this tab, or

Uploaded Files

Delete Name Last Updated Use This File
Select this to use the file for generating your CV and cover letter. Only one source—uploaded file, selected file, or LinkedIn text—can be used.

My Files

CVs or cover letters you create will appear here. No files available yet.
Delete Name Last Updated Use This File
Select this to use the file for generating your CV and cover letter. Only one source—uploaded file, selected file, or LinkedIn text—can be used.

Add LinkedIn Profile PDF

You can download your LinkedIn profile as a PDF by opening linkedin.com in a web browser, clicking your profile photo, selecting the “More” or “Resources” button, and choosing “Save to PDF.” You can then attach the PDF using the Upload From Computer tab.

Paste Your LinkedIn Profile Text

If you have copied the LinkedIn profile text, paste it below. See how to copy your profile from LinkedIn

Select this to use the LinkedIn profile text for generating your CV and covering letter. Only one source—uploaded file, selected file, or LinkedIn text—can be used.

Try these controls

<
>