US English


7 Data Scientist & Engineer - Legal Data Products CV Templates with Example
By Ria · Last Updated On 22 October 2026
CV example — page 1

This guide shows you how to create a Data Scientist & Engineer - Legal Data Products CV that presents your evidence clearly. You will learn how to shape a focused CV for this exact role and make relevant experience easy to review.

A strong CV links data engineering and data science work to trusted products for legal services. Show how you assess sources, build governed data assets, test models and explain their limits.

Explore the example presented in 7 layouts, compare the PNG image previews and open an example in the editor to customise it. The guide also covers ATS-friendly structure and role terms such as Microsoft Fabric, Databricks, data contracts, entity resolution, NLP and model validation.

What Makes a Great Data Scientist & Engineer - Legal Data Products CV in 2026

A strong CV makes data products, analytical work and results easy to scan. Clear bullets show your contribution to reliable pipelines, useful models and well-documented outputs.

Use relevant terms such as Microsoft Fabric, Databricks, data quality, lineage, NLP and entity resolution. Support claims with evidence, and state model limits where they matter.

Note: CV examples are for educational purposes only. Use only information that accurately reflects your experience and qualifications. References to real organisations do not imply affiliation or endorsement.

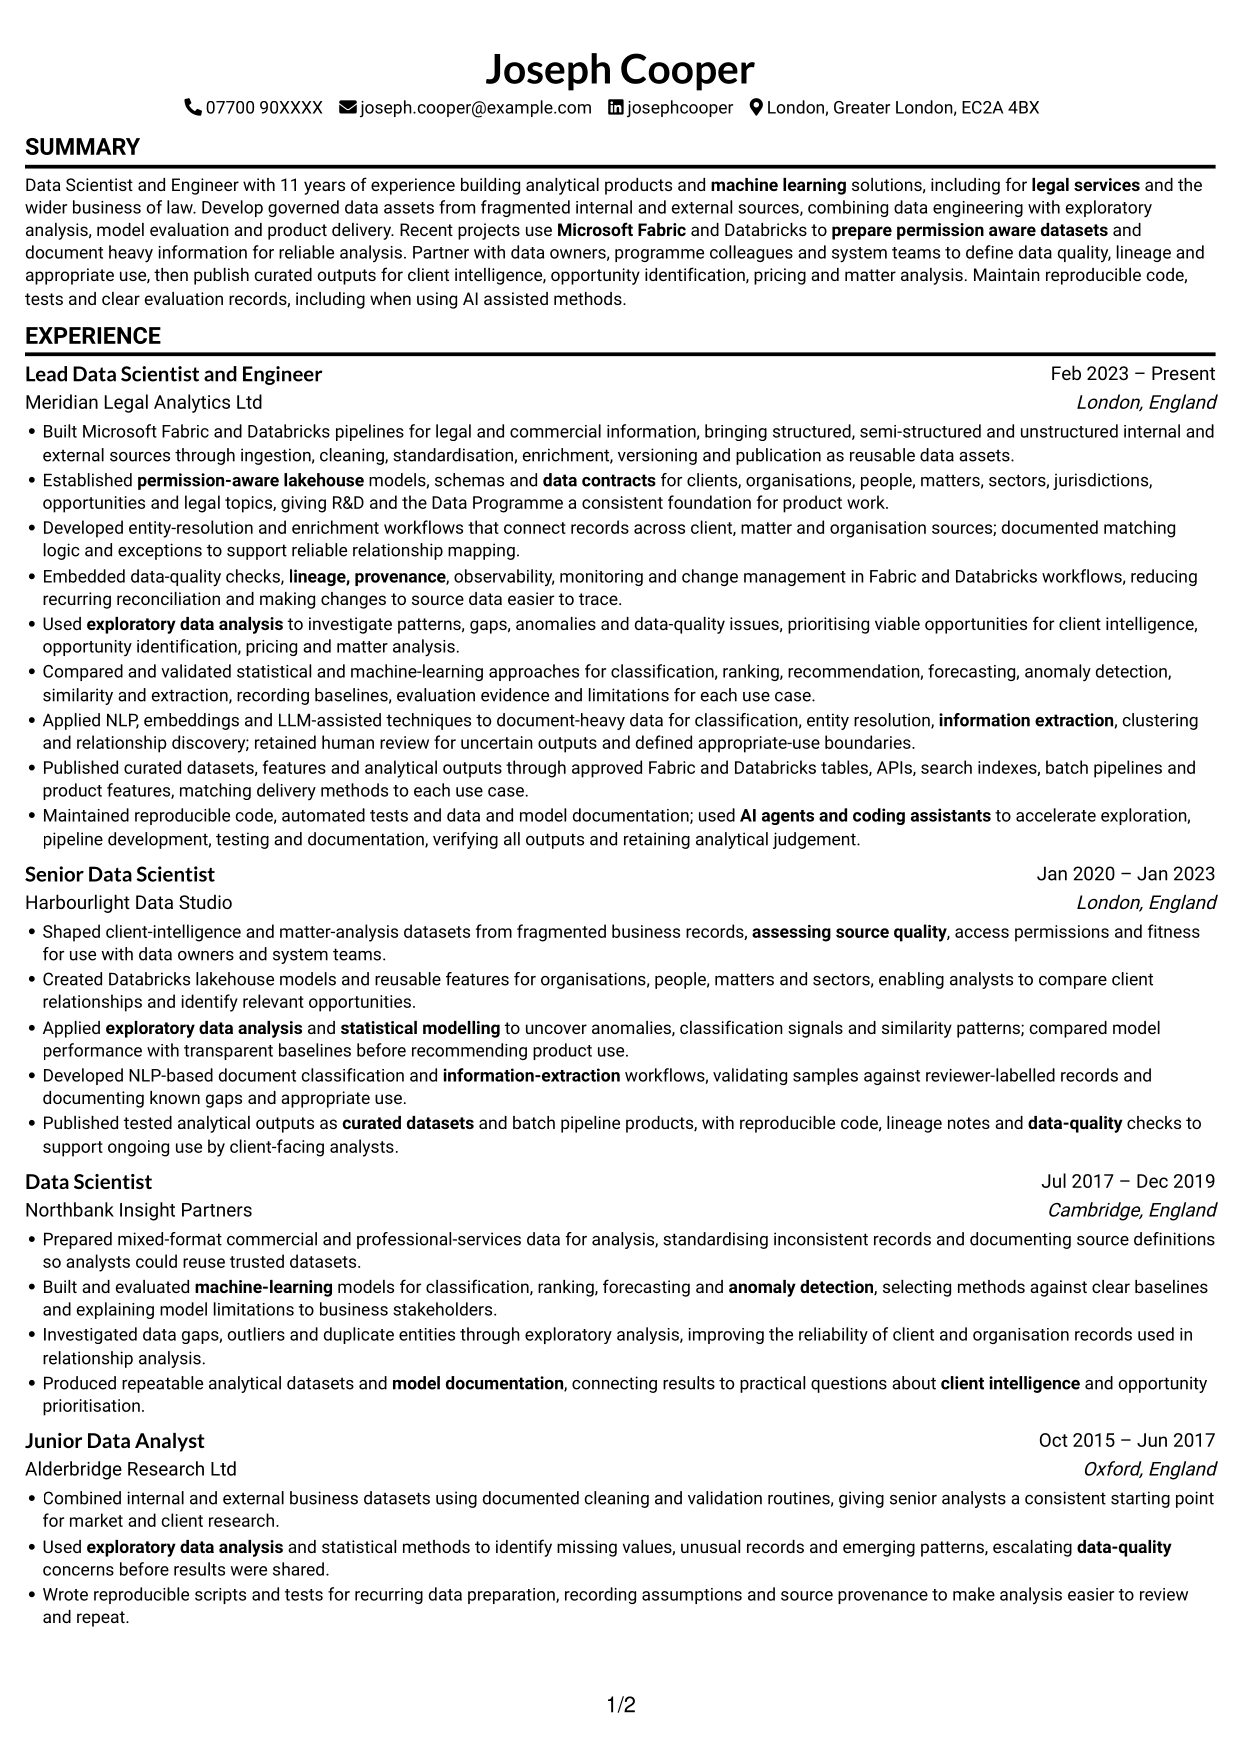
#1 Simple One Column Format CV Example

The Simple One Column Format keeps the CV in one reading column, a practical choice when a clear, uninterrupted text path matters.
 
CV example — page 1   CV example — page 2

Why This Format Works

  • One continuous column gives ATS systems a straightforward path through the CV.
  • Experience bullets retain their context without a parallel column competing for space.
  • Education and credentials can be followed within the same reading sequence.

Best For

  • ATS parsing preference
  • Detailed experience entries
  • Chronological work histories
  • Skills alongside education
  • Text-led CV presentation

CV Keywords

  • Microsoft Fabric
  • Databricks
  • data engineering
  • Data science
  • Built Microsoft Fabric and Databricks pipelines
  • Established permission-aware lakehouse models, schemas and data contracts
  • Lakehouse modelling
  • data contracts
  • data quality
  • Data governance
  • lineage, provenance
  • observability
  • exploratory data analysis
  • statistical modelling
  • machine learning
See all keywords
 

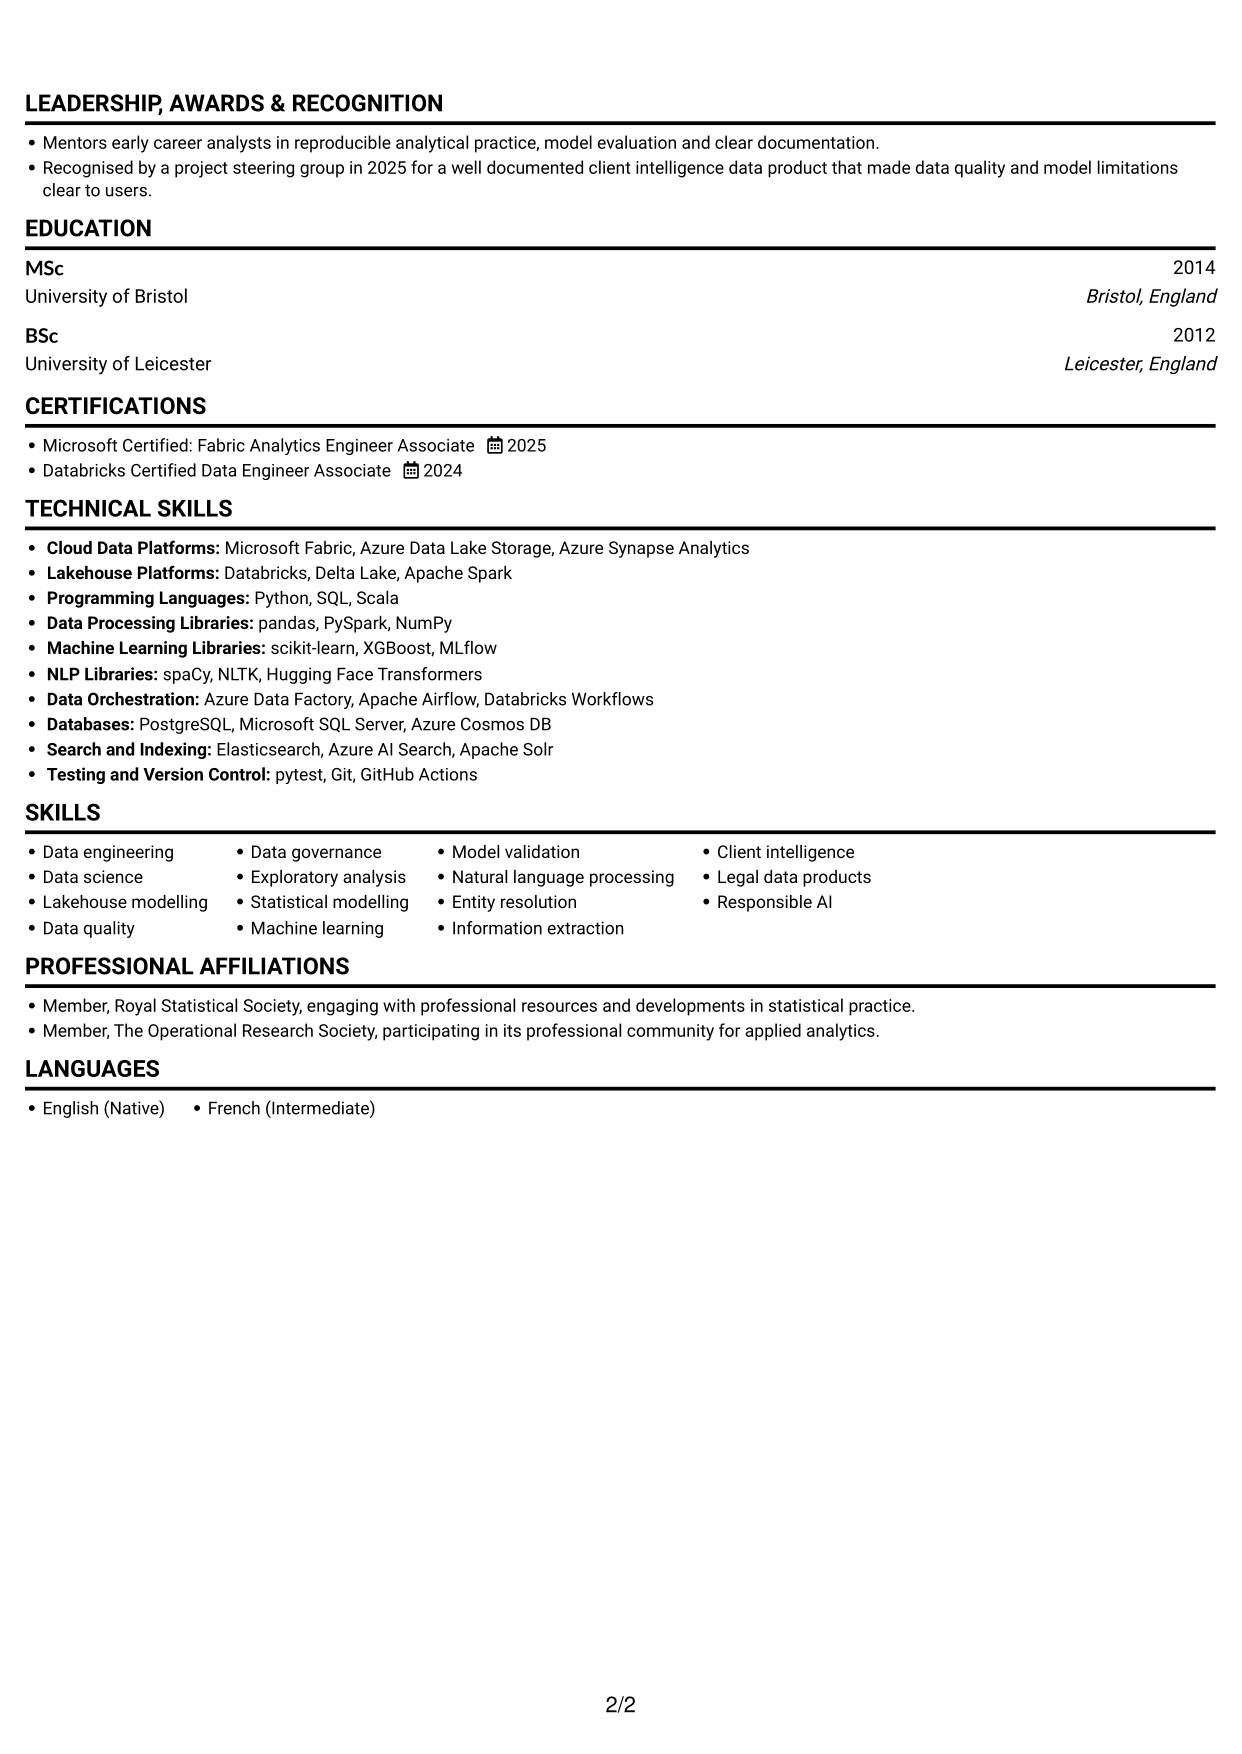
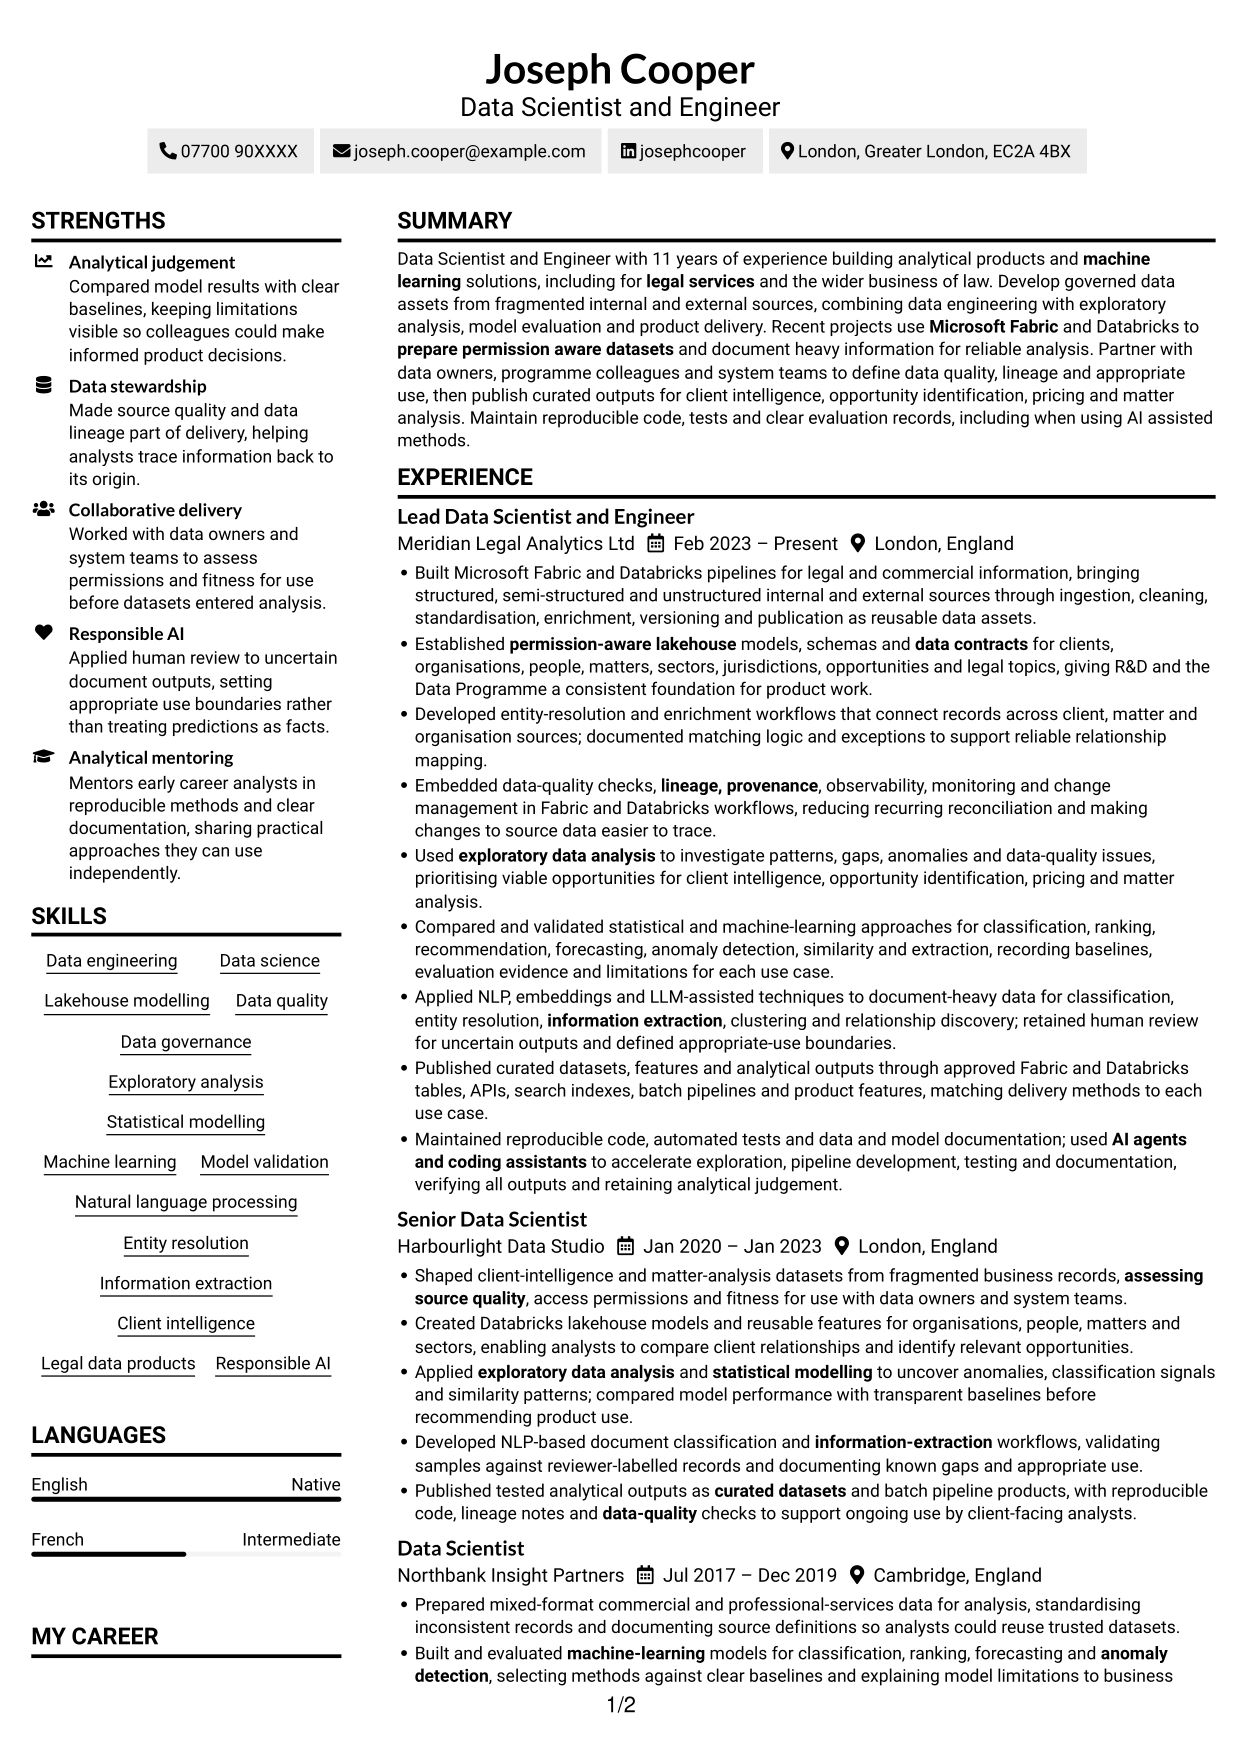
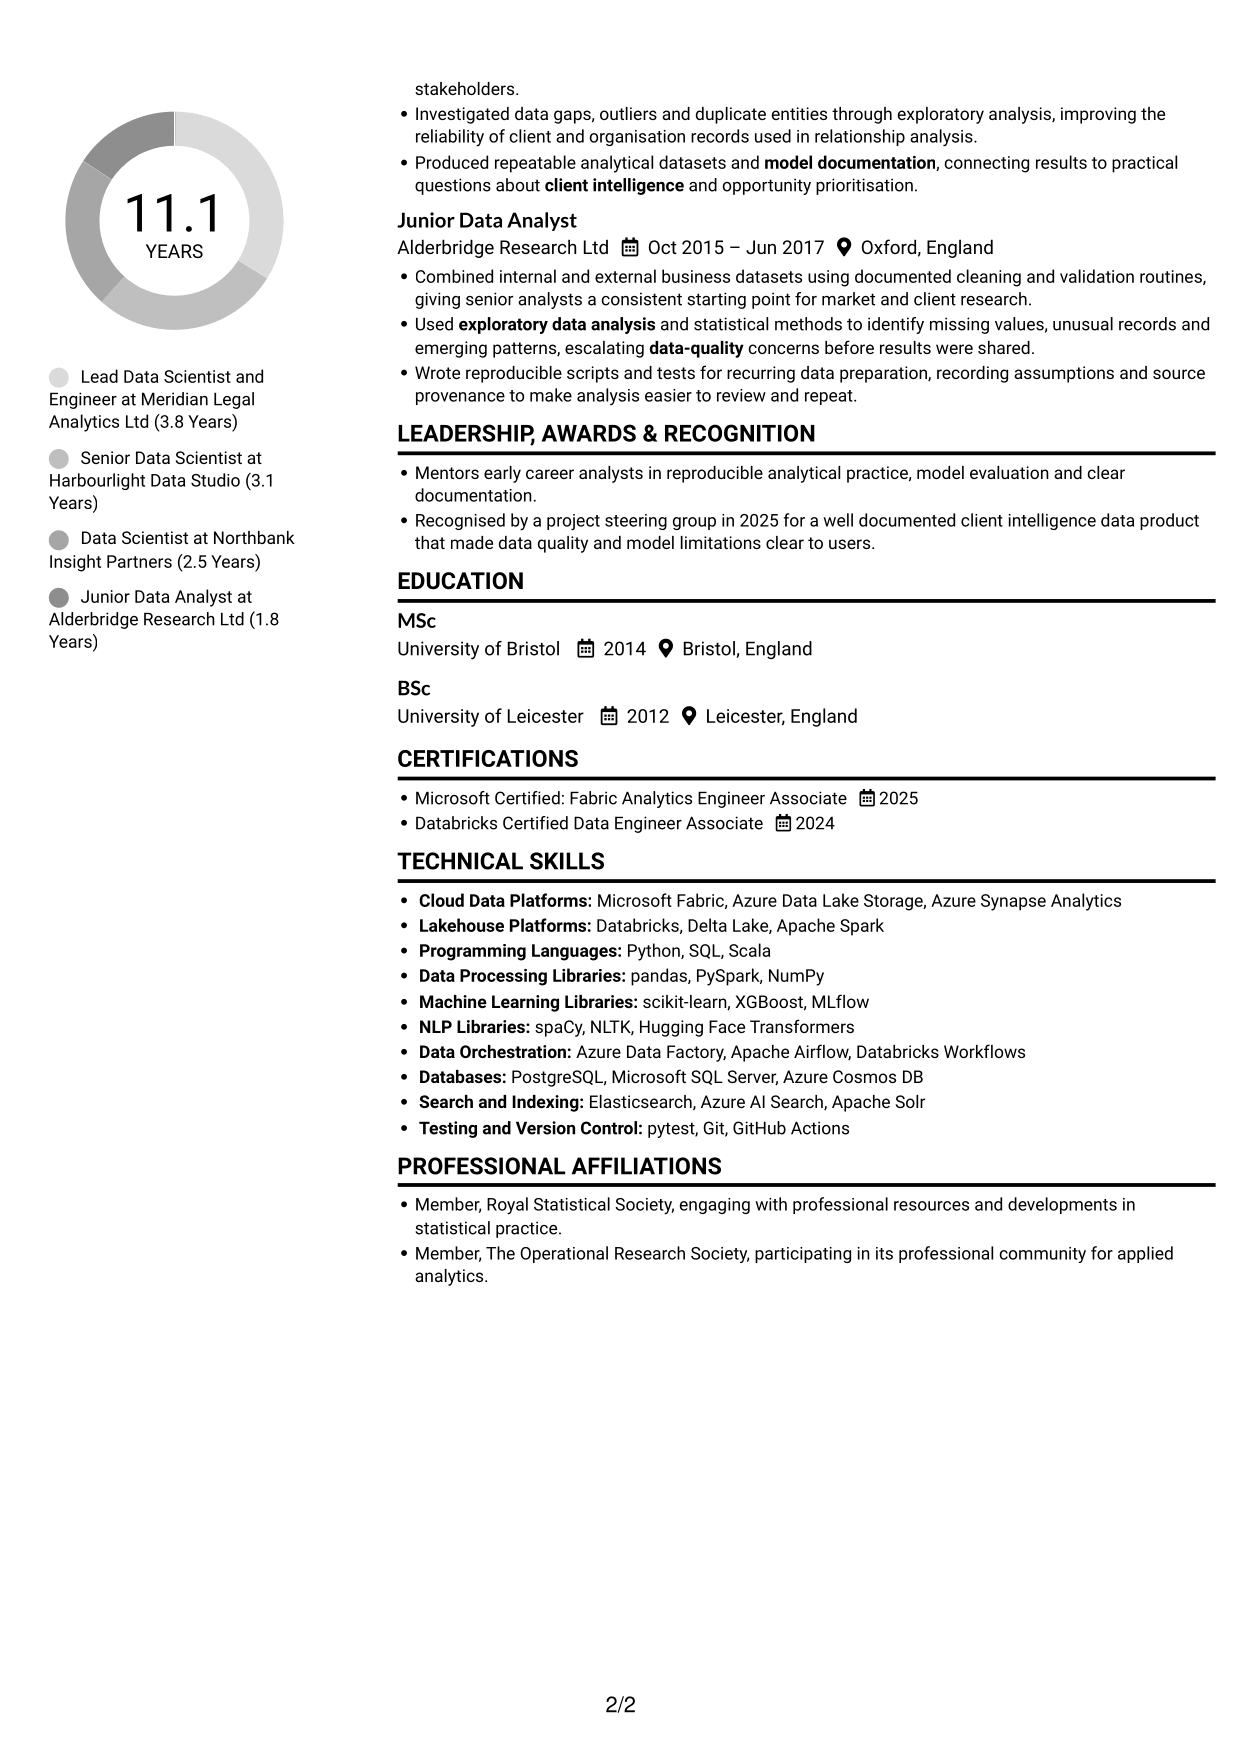
#2 Simple Two Column Format CV Example

The Simple Two Column Format places CV content in two columns, giving readers a practical way to distinguish career history from supporting details.
 
CV example — page 1   CV example — page 2

Why This Format Works

  • Side-by-side columns let reviewers distinguish career history from supporting information.
  • Skills and tools can sit apart from detailed experience bullets.
  • Education and credentials remain part of the same two-column reading order.

Best For

  • Separate experience and supporting details
  • Compact skills and tools sections
  • Mixed detail across CV sections
  • Quick access to education records
  • Two-column reading preference

#3 Plain One Column with Shaded Labels CV Example

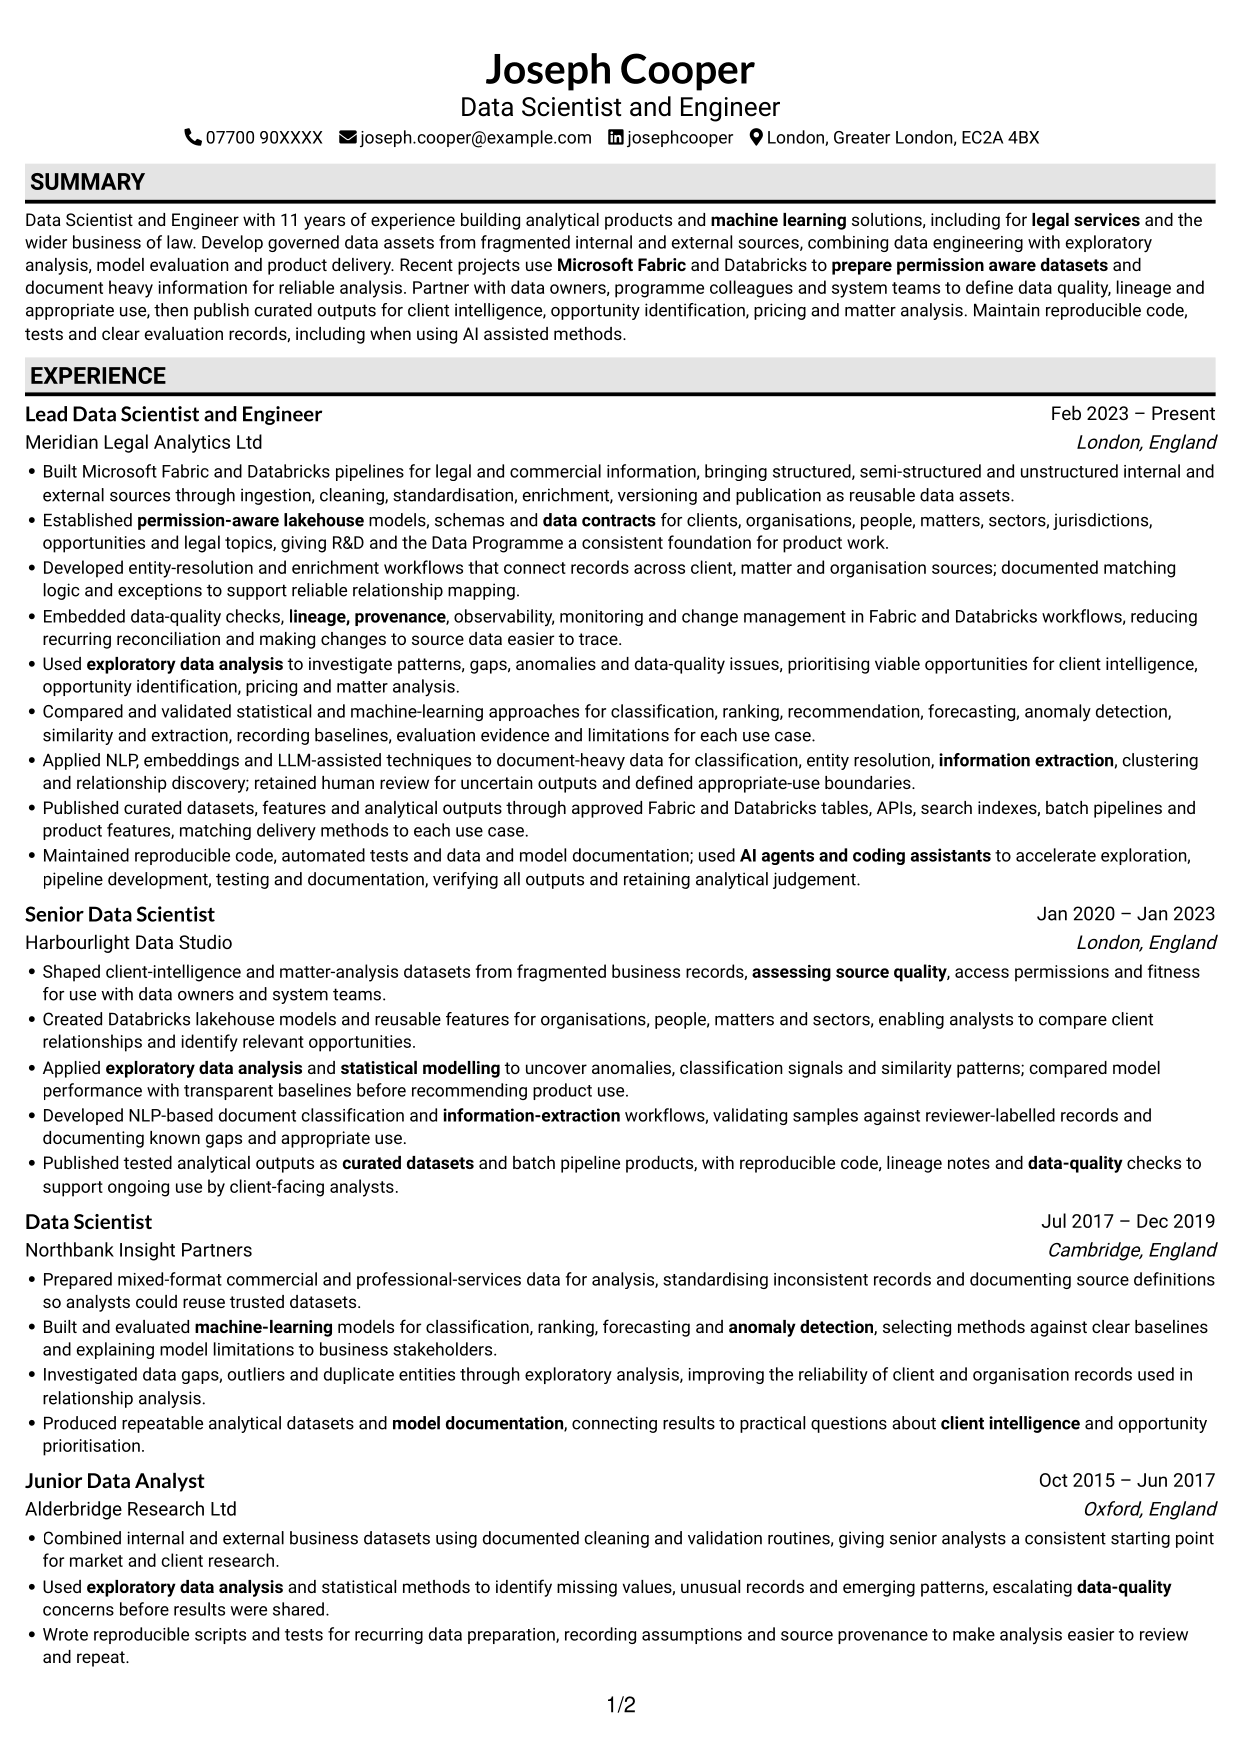
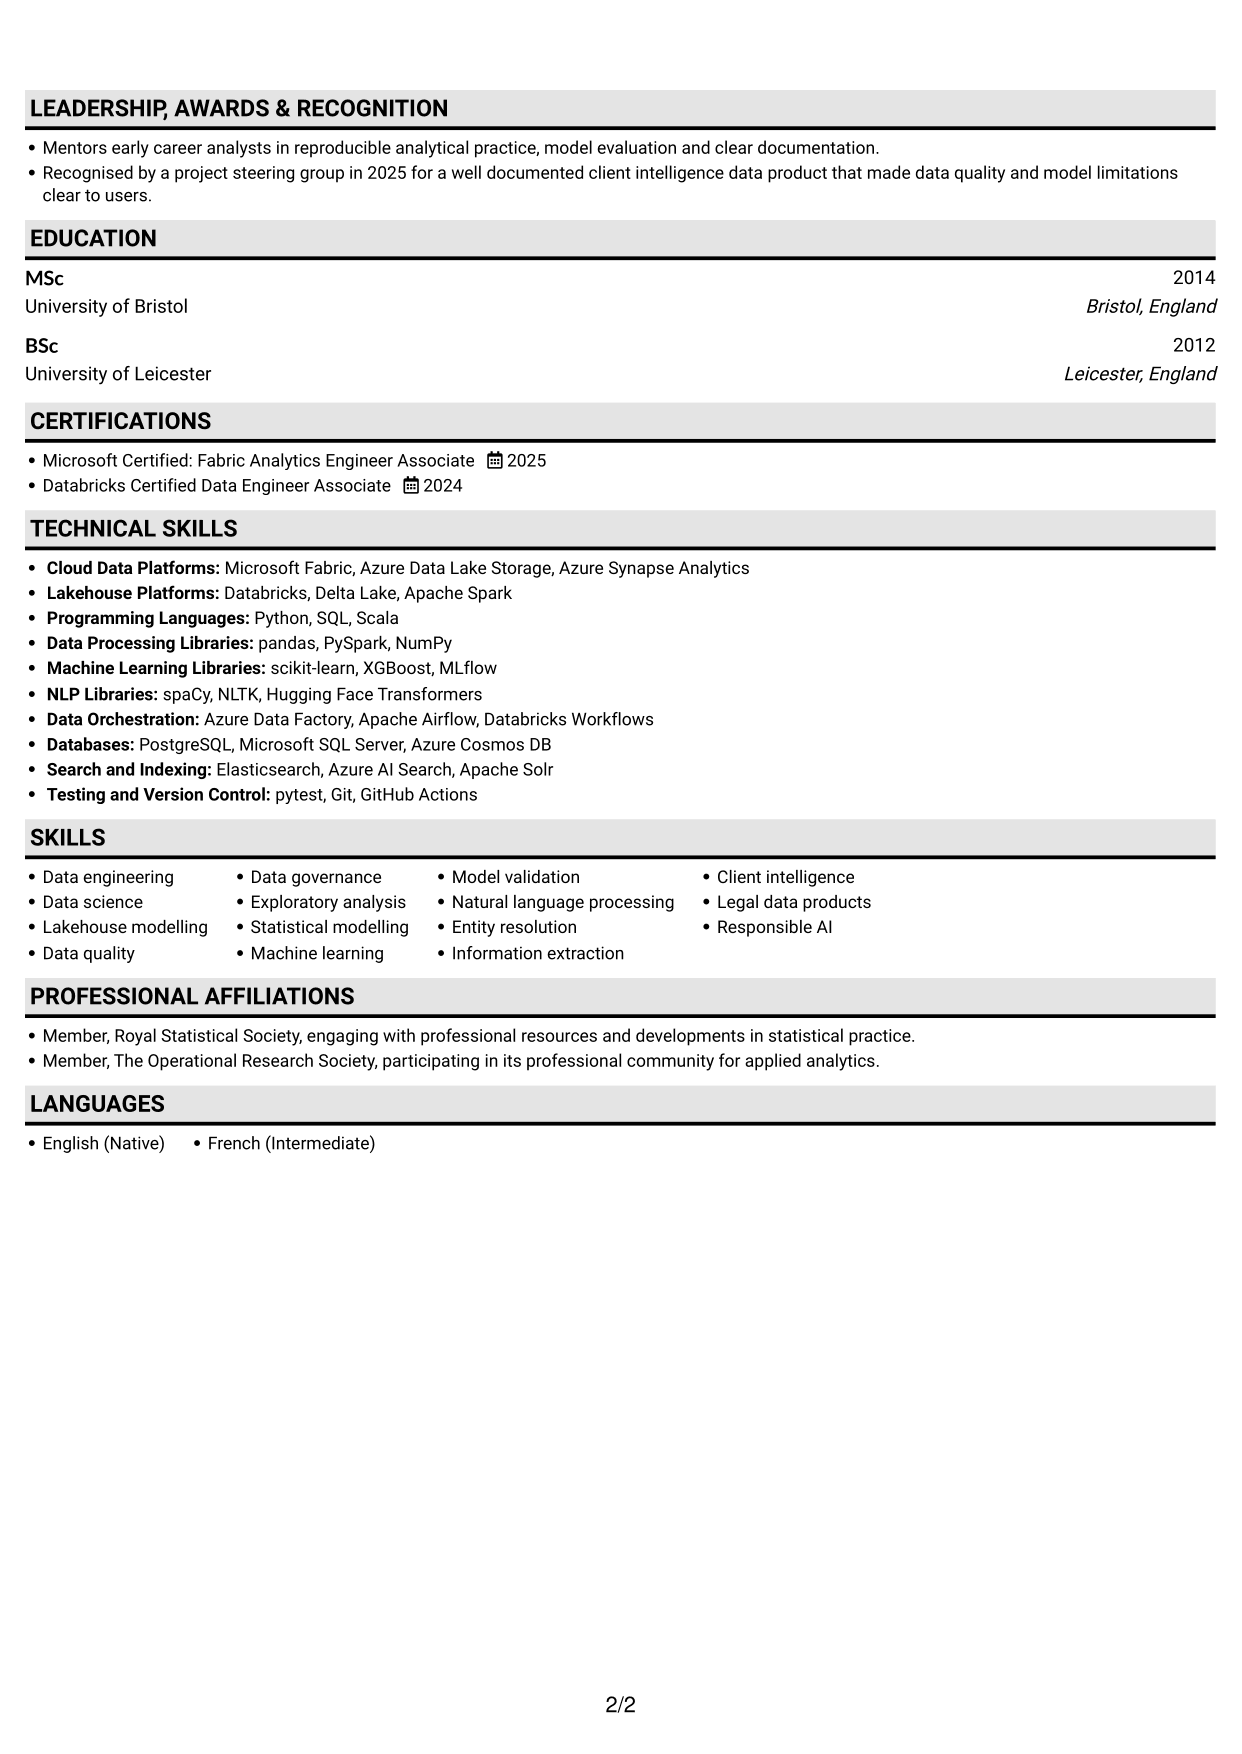
Plain One Column with Shaded Labels uses a single reading column, a useful choice when reviewers need to follow detailed CV content in sequence.
 
CV example — page 1   CV example — page 2

Why This Format Works

  • A single reading path keeps detailed experience entries together for careful review.
  • Data product achievements can be read with their supporting context.
  • Skills, education and credentials stay within one route through the CV.

Best For

  • Detailed career histories
  • In-sequence experience review
  • Achievement bullets with context
  • Single-column content preference
  • Skills and credentials in one reading path
 

#4 One Column Format with Photo Right CV Example

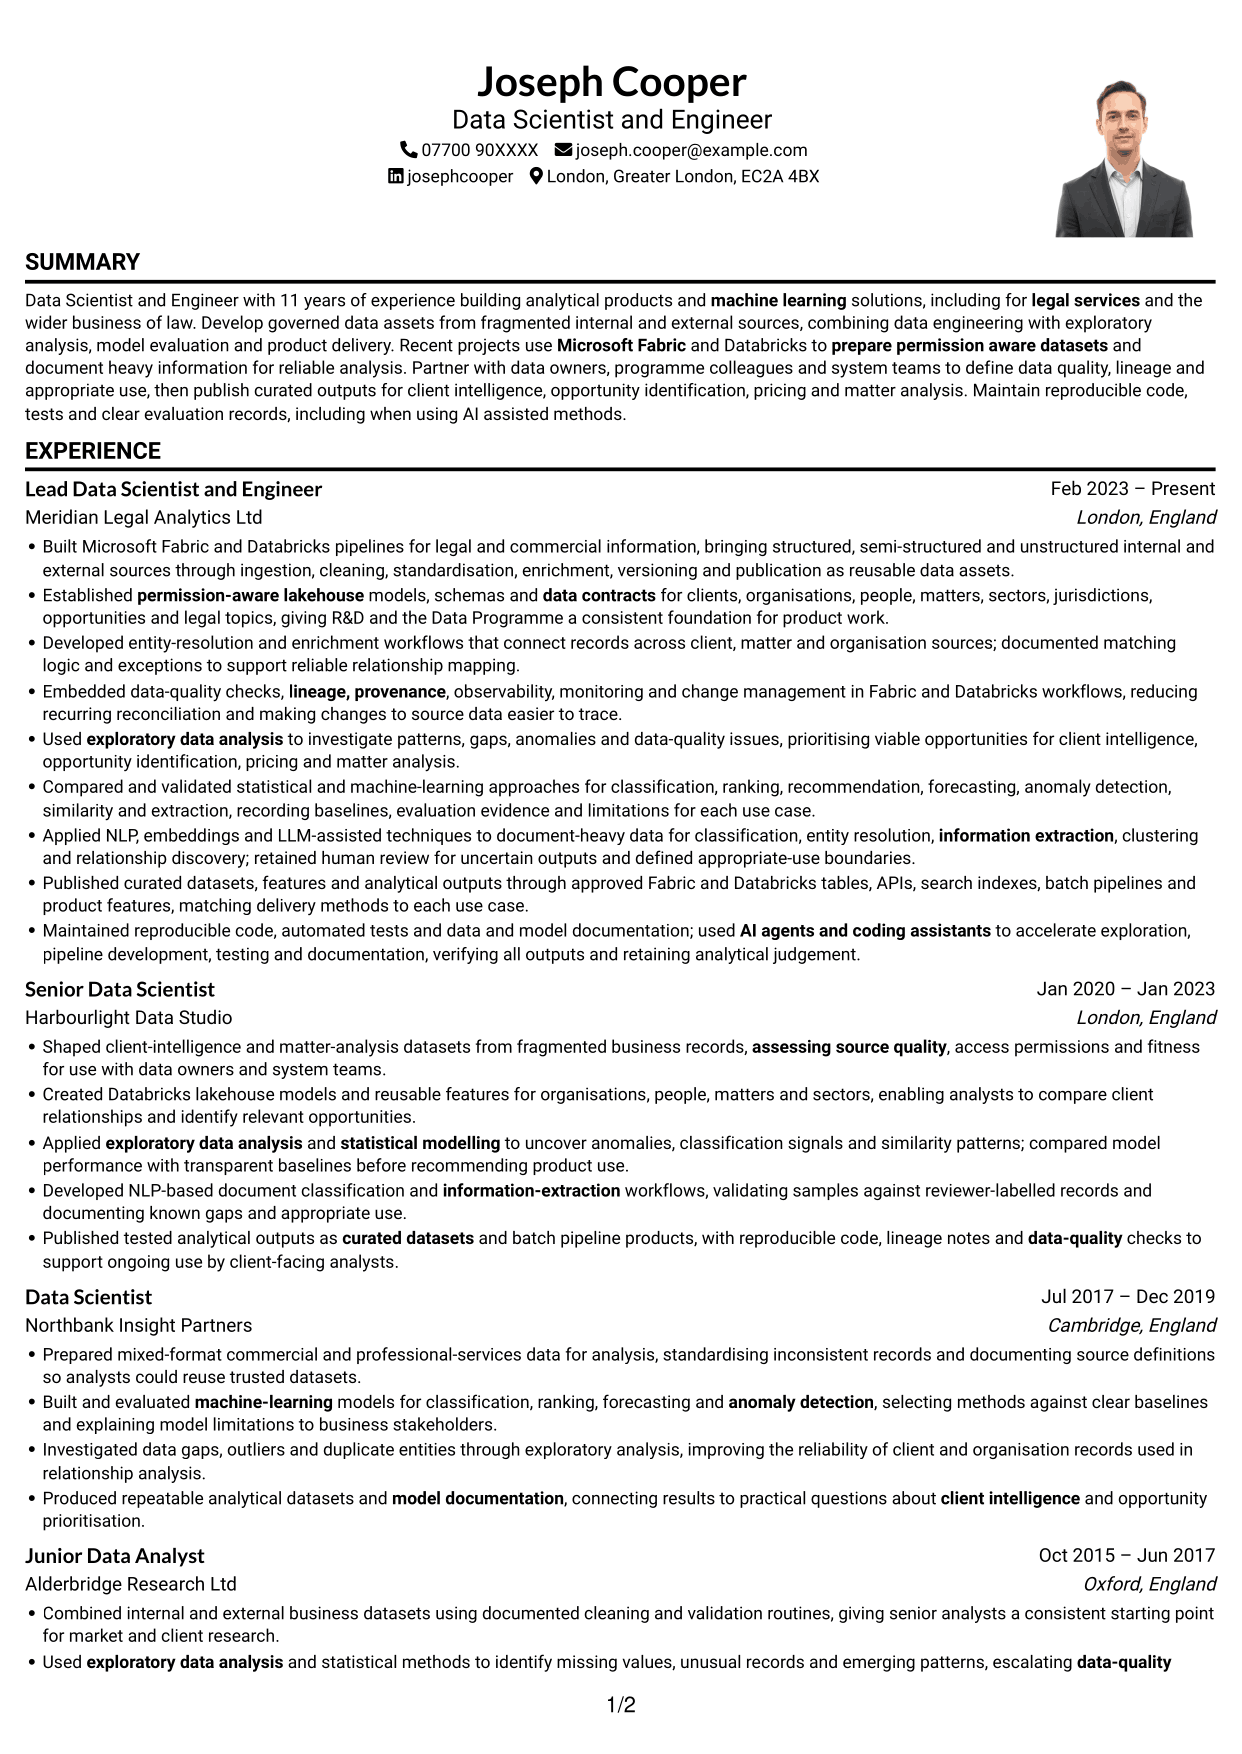
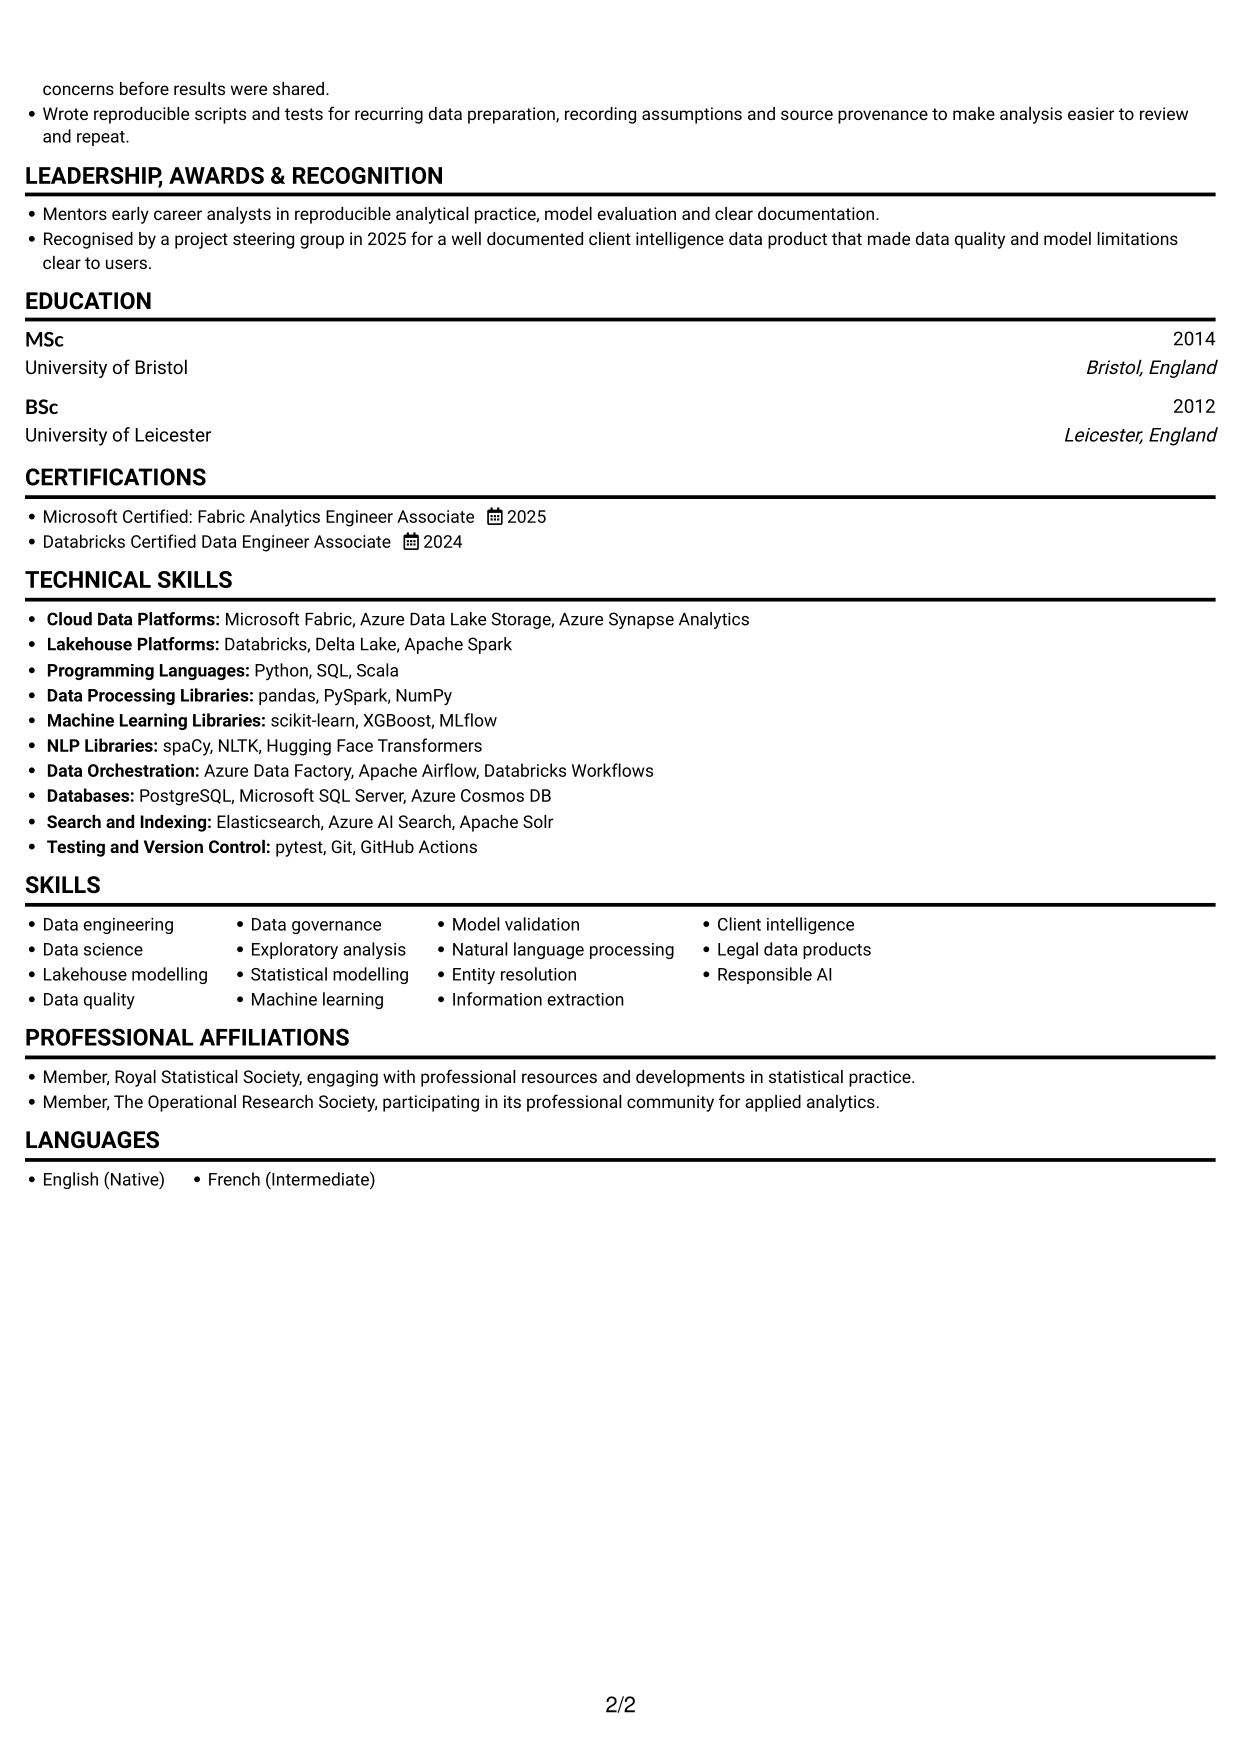
One Column Format with Photo Right combines a single-column CV with a photo, a practical option for readers who prefer a personal image alongside the document.
 
CV example — page 1   CV example — page 2

Why This Format Works

  • Experience bullets follow one reading path, keeping their context together.
  • A single column lets reviewers move through work history in sequence.
  • Skills, education and credentials remain within the same text flow.

Best For

  • Photo-inclusive CVs
  • Sequential work histories
  • Experience details with context
  • Single-column reading preference
  • Personal image alongside CV content
 

#5 Clean Two Column Sidebar Format CV Example

Clean Two Column Sidebar Format presents CV content in two columns, suiting readers who want career information arranged side by side.
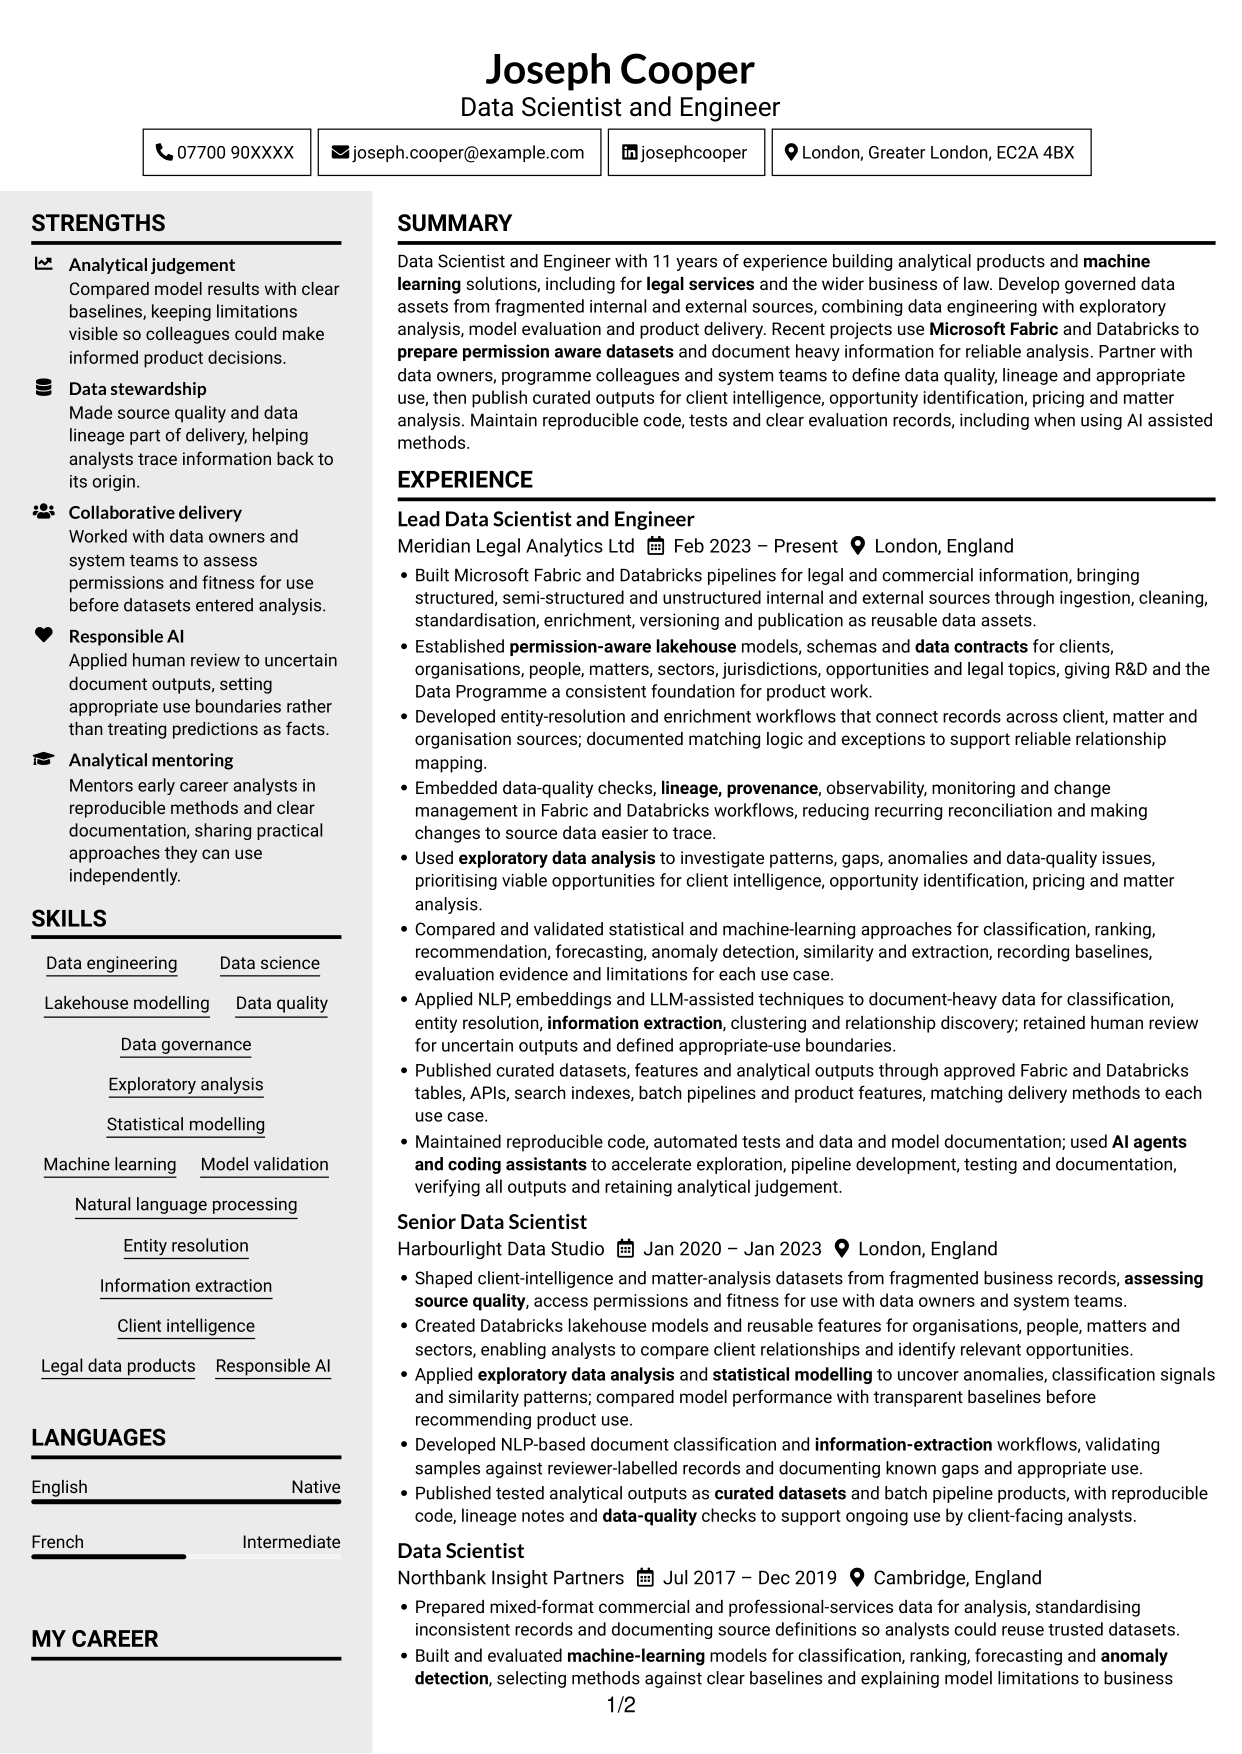
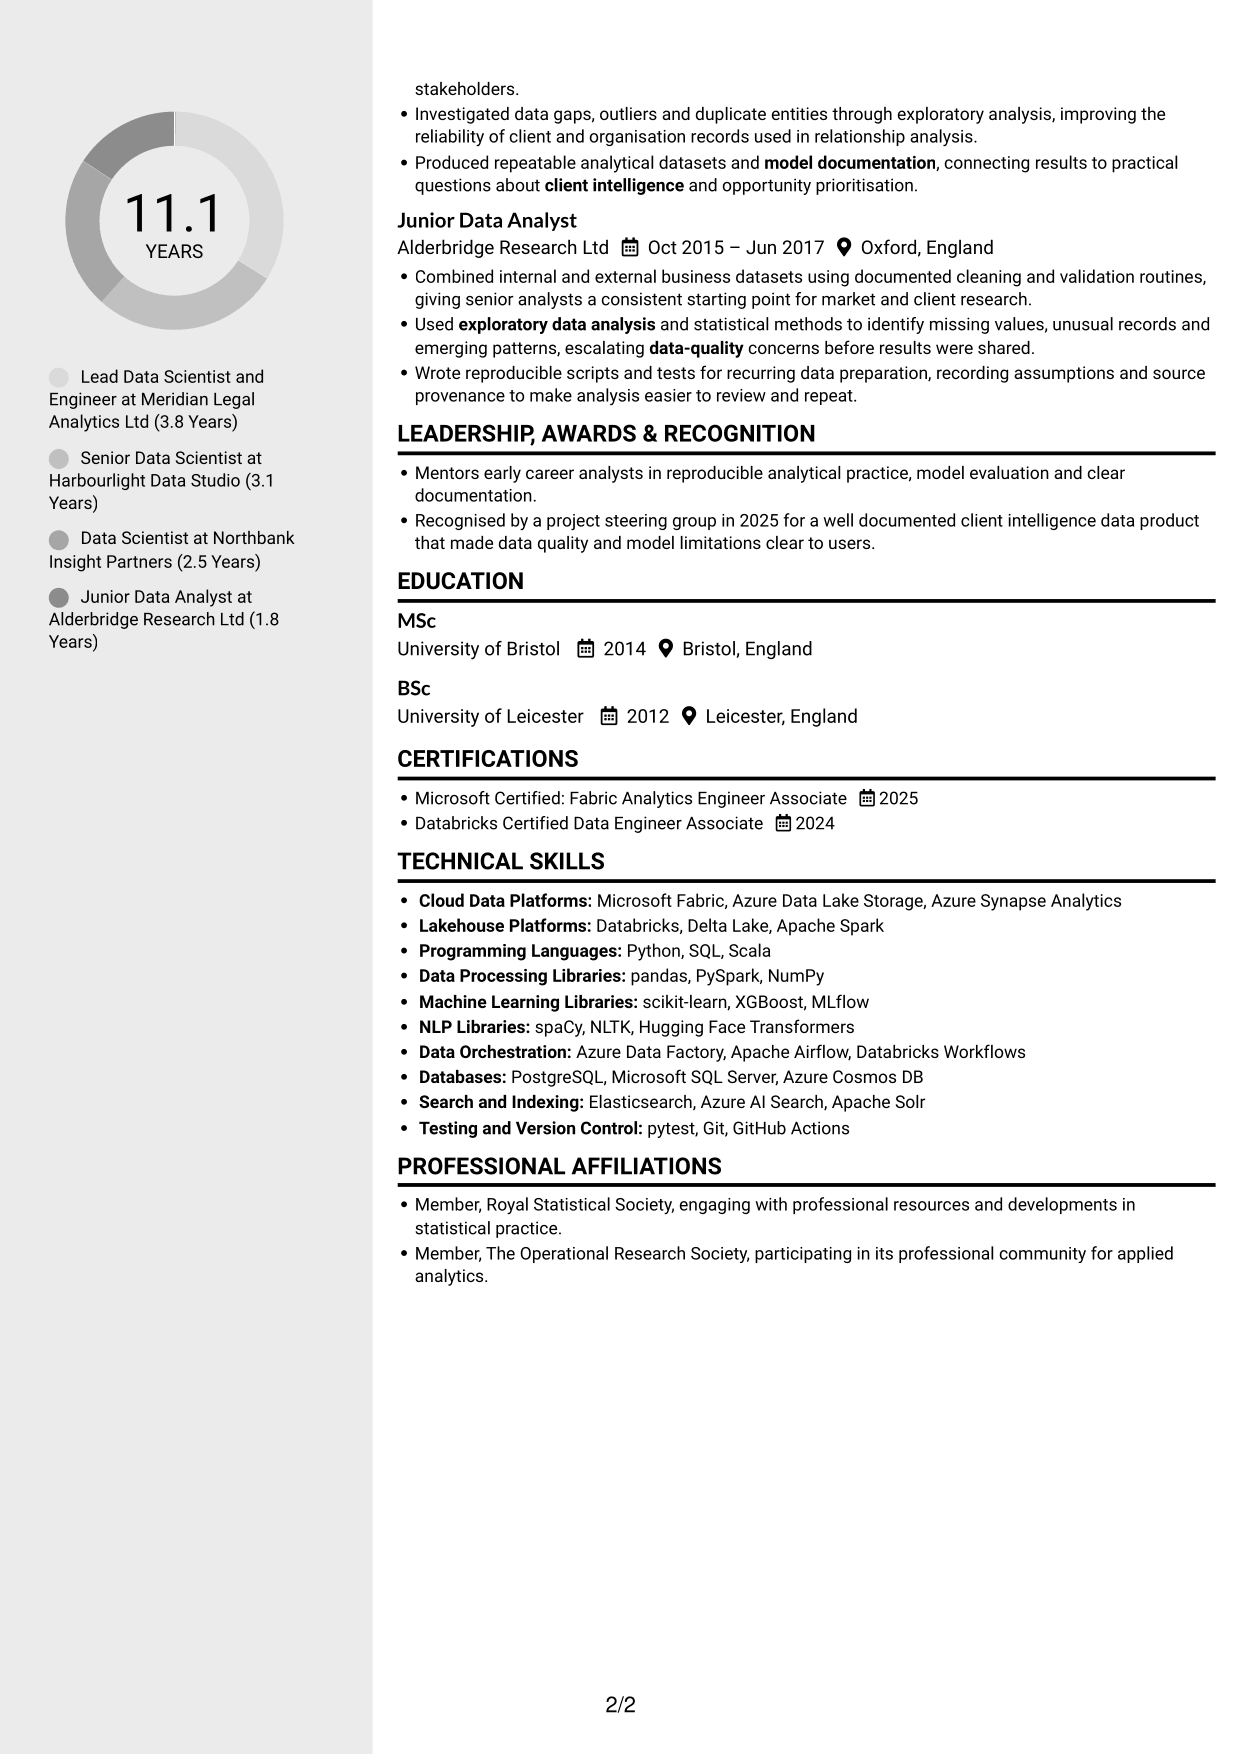
 
CV example — page 1   CV example — page 2

Why This Format Works

  • Two-column organisation separates experience details from other CV information.
  • Reviewers can locate skills and tools without leaving the CV page flow.
  • Education and credentials have a distinct place within the overall content.

Best For

  • Side-by-side content organisation
  • Experience with supporting details
  • Skills and tools sections
  • Education and certification records
  • Compact CV section navigation


#6 Two Column Format CV Example

Two Column Format arranges the CV across two columns, a practical choice when readers want to compare different types of information at a glance.
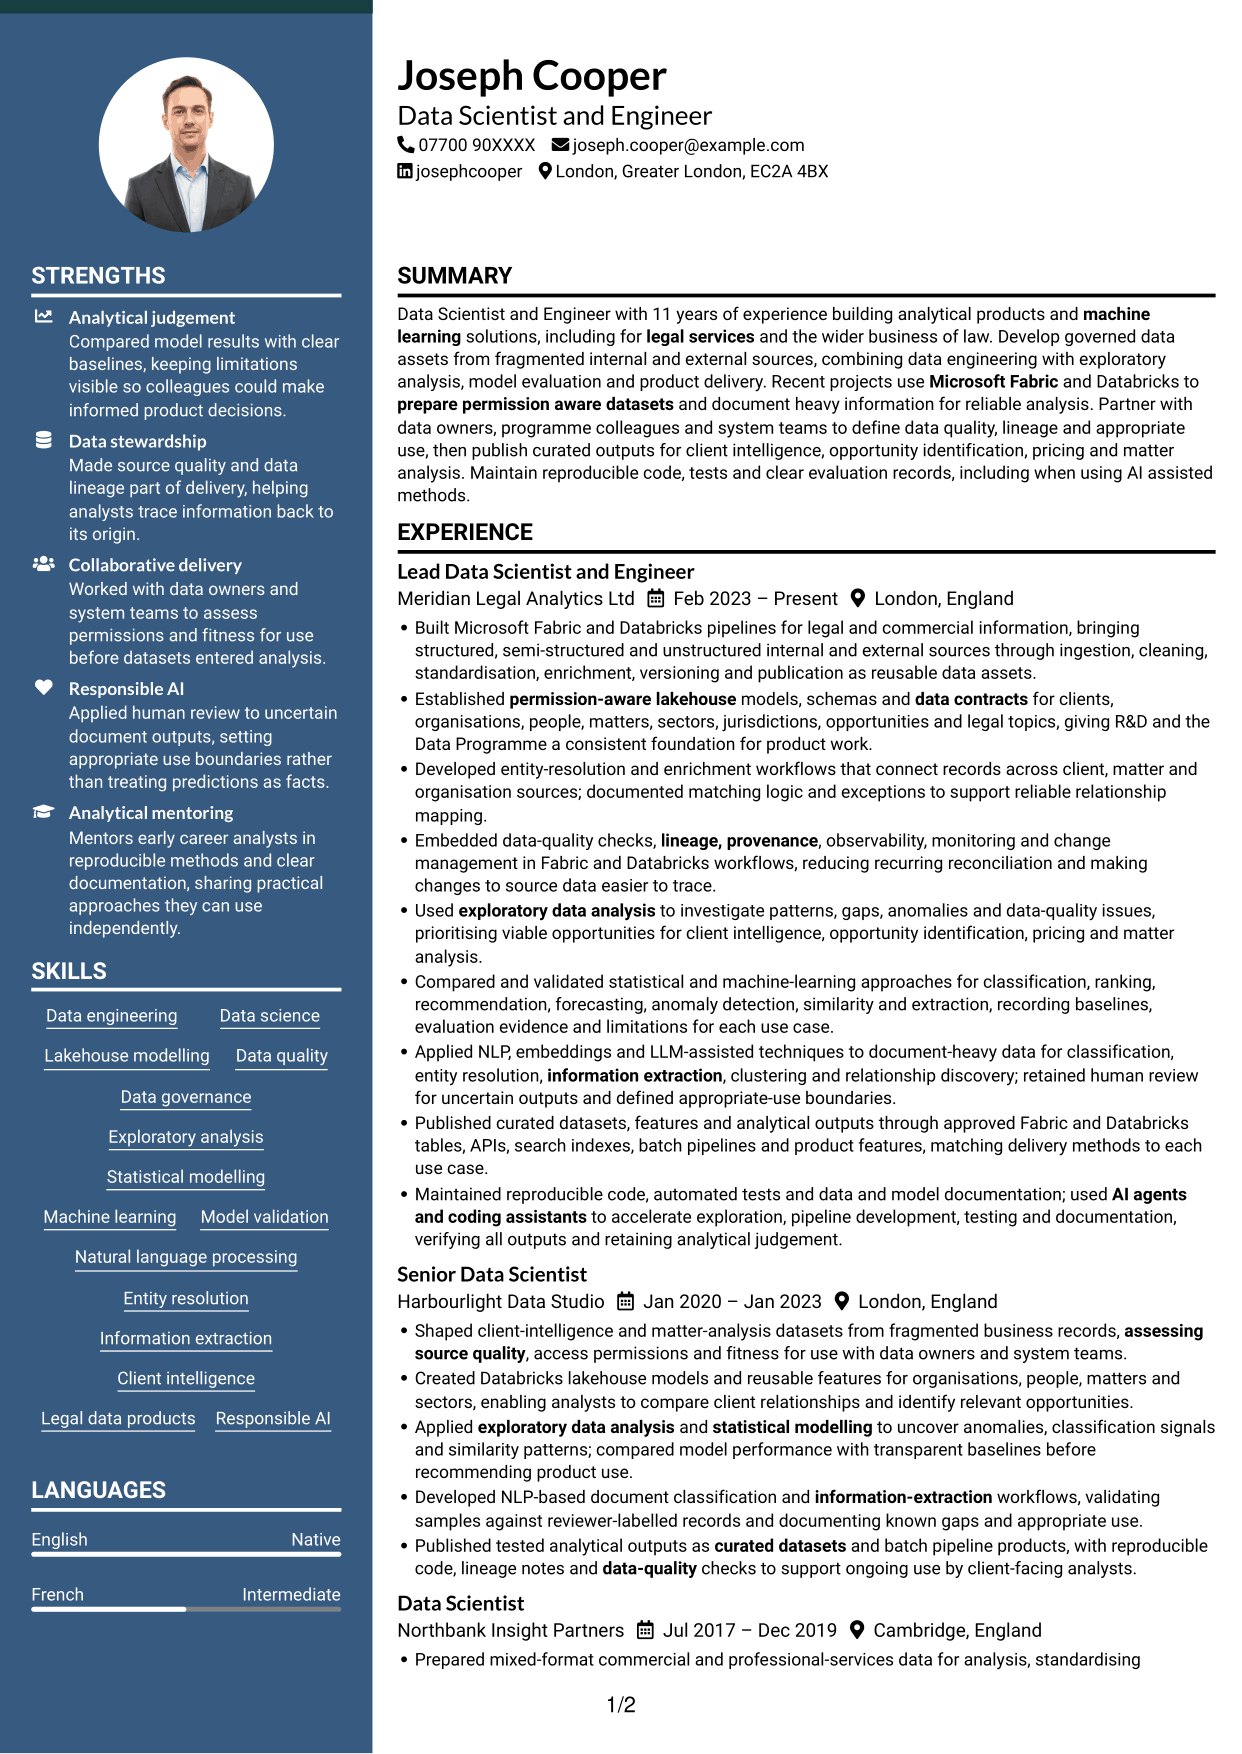
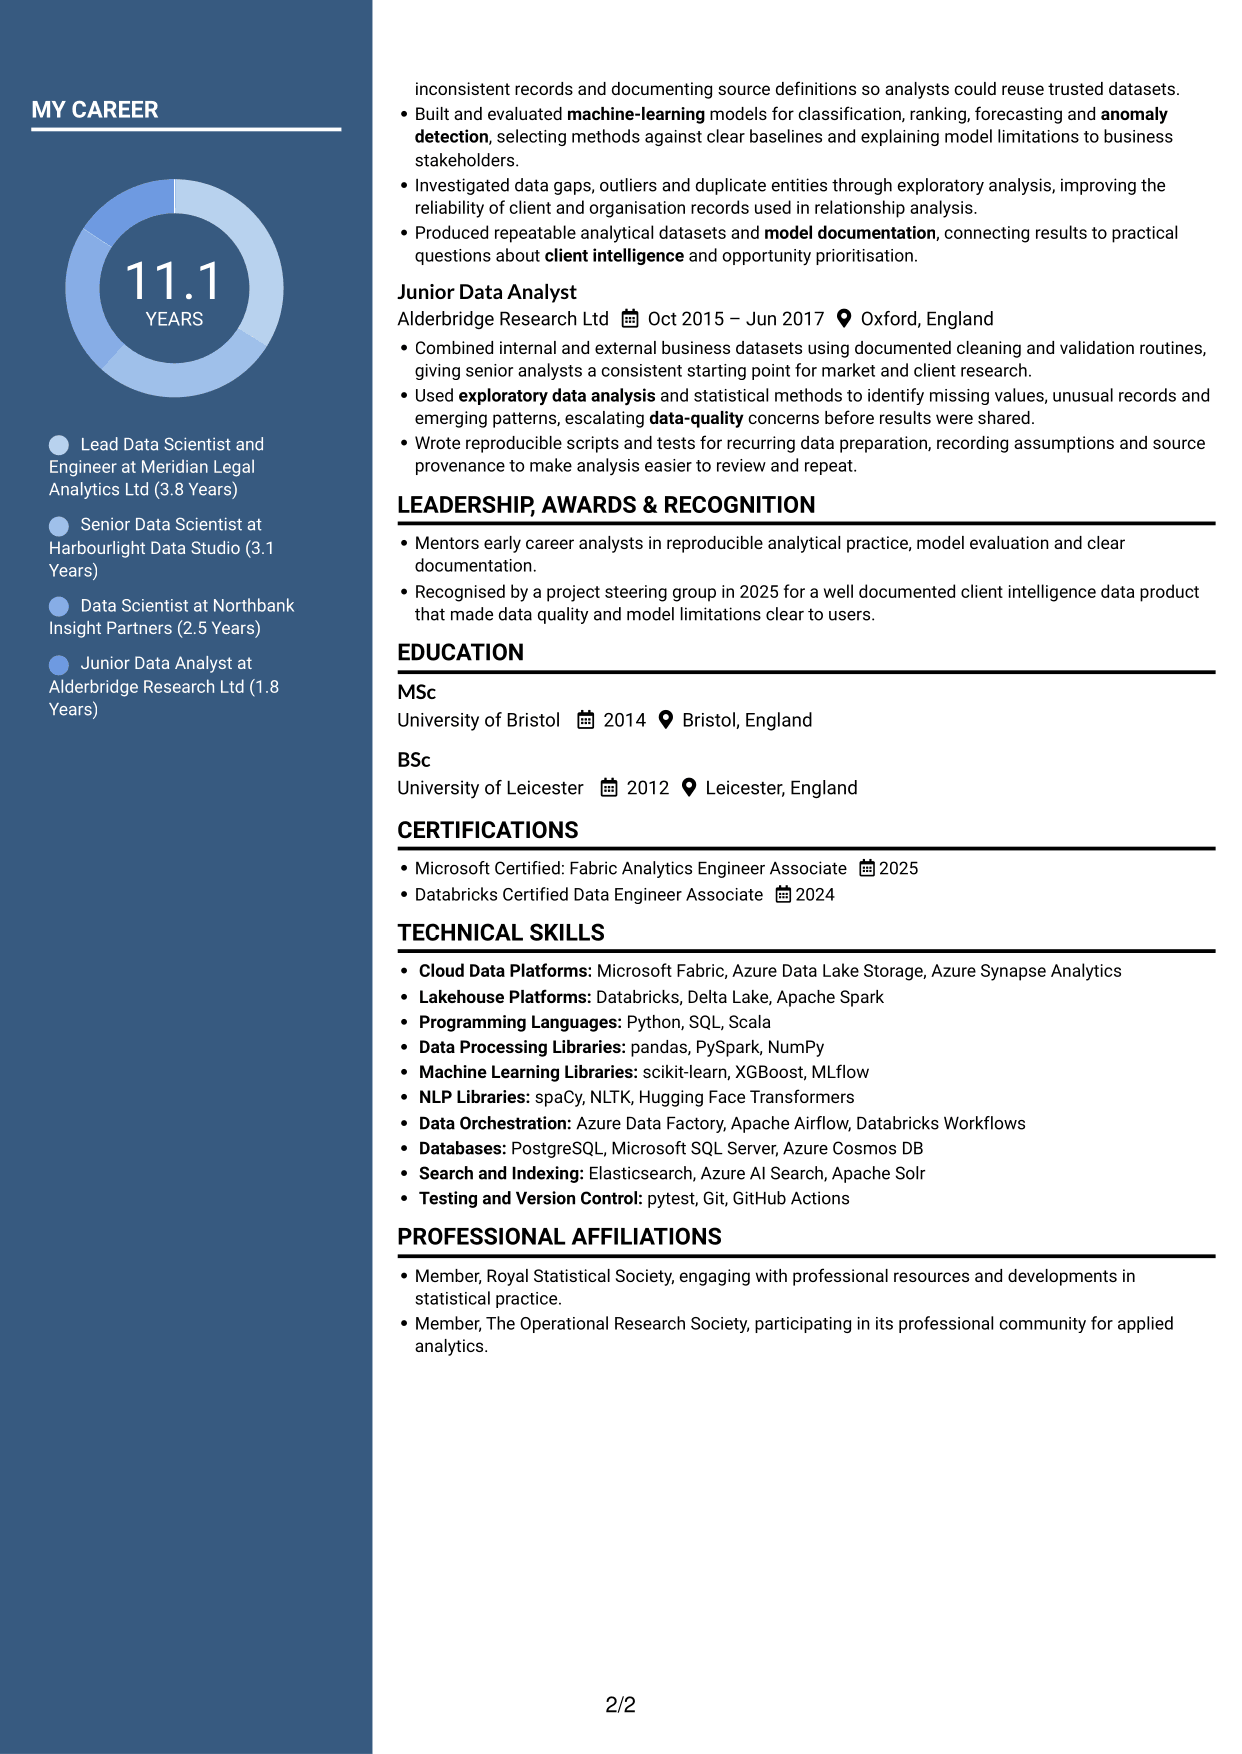
 
CV example — page 1   CV example — page 2

Why This Format Works

  • The two-column structure gives career history and supporting details separate reading areas.
  • Experience bullets remain grouped, helping reviewers follow changes across roles.
  • Skills, education and credentials are easy to find within the layout.

Best For

  • Parallel CV content areas
  • Role-by-role experience records
  • Skills beside career history
  • Education and credential details
  • Readers who prefer two columns
 

#7 Photo Header Two Column Format CV Example

Photo Header Two Column Format pairs two-column CV content with a photo, offering a personal visual element alongside a separated reading layout.
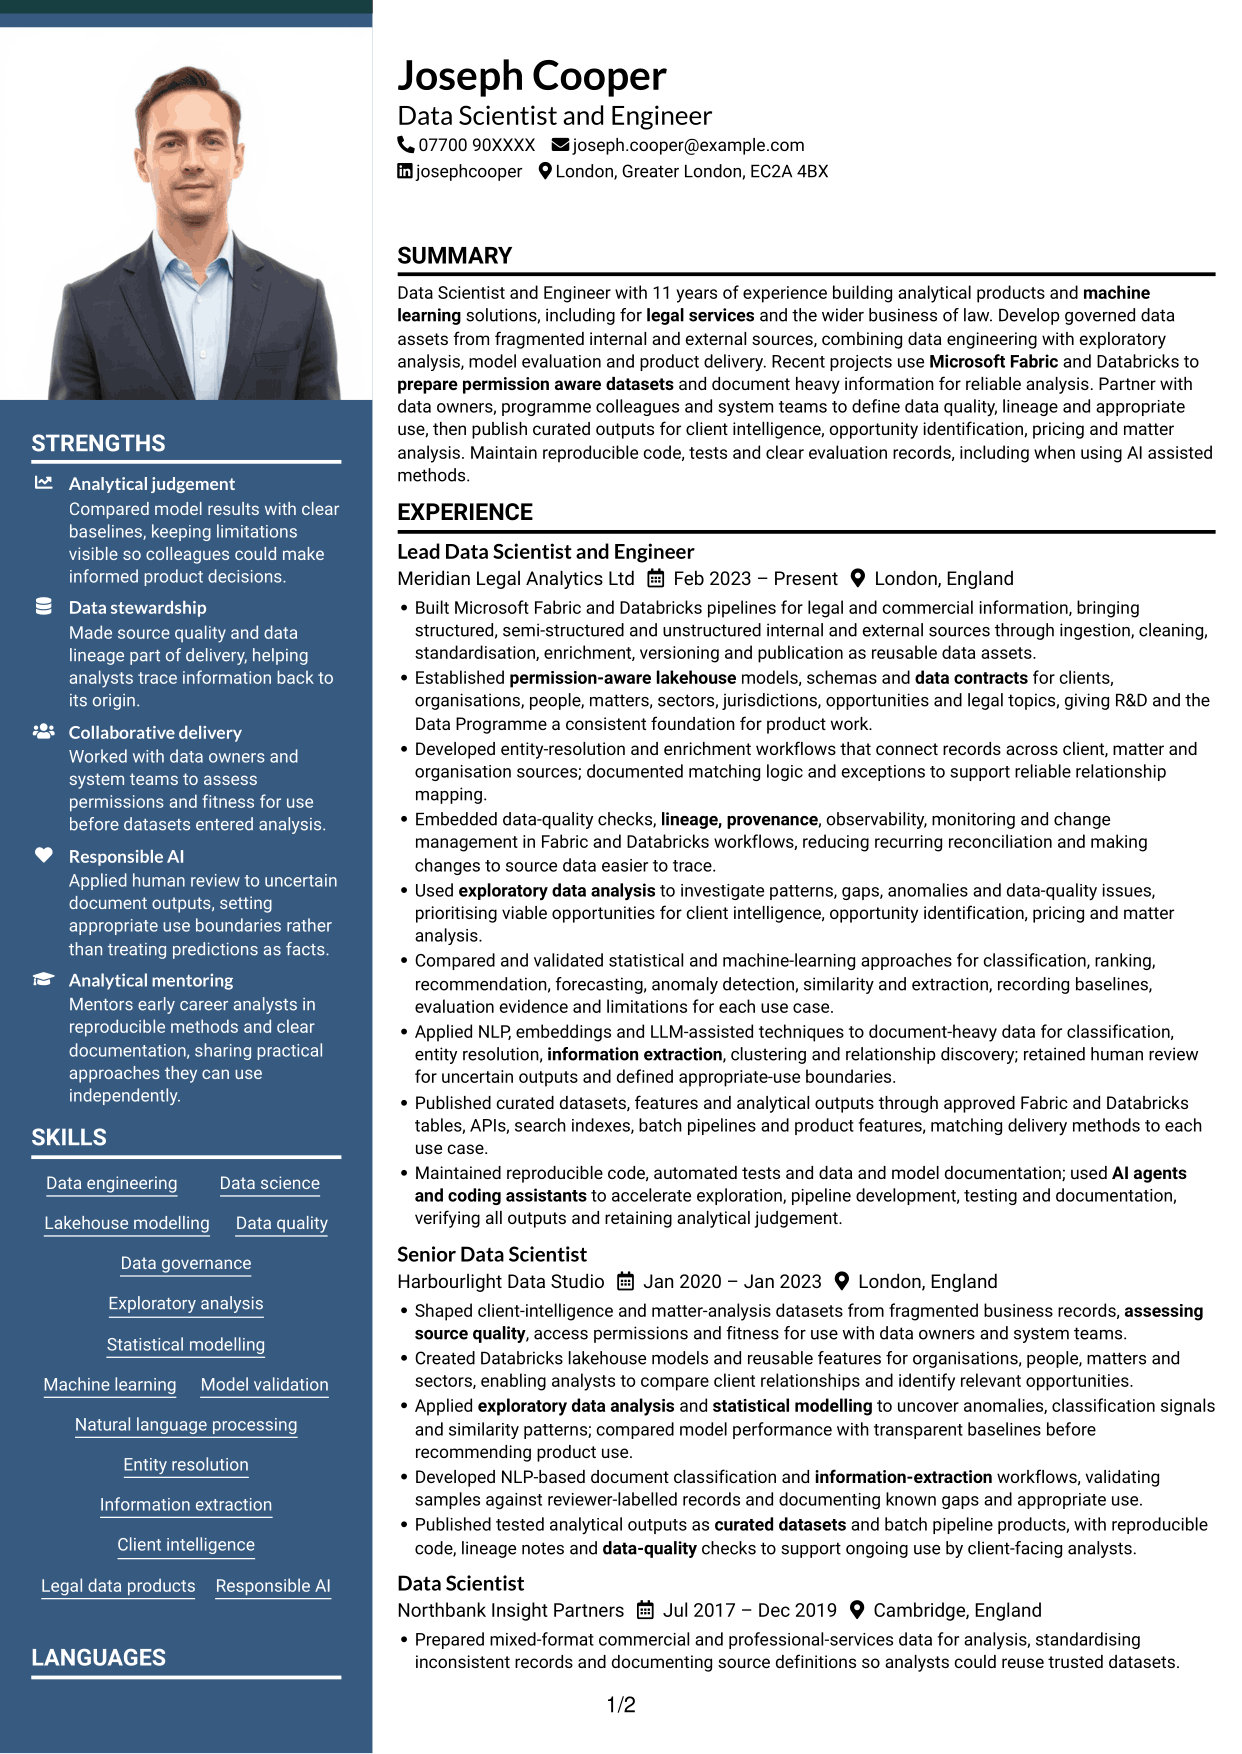
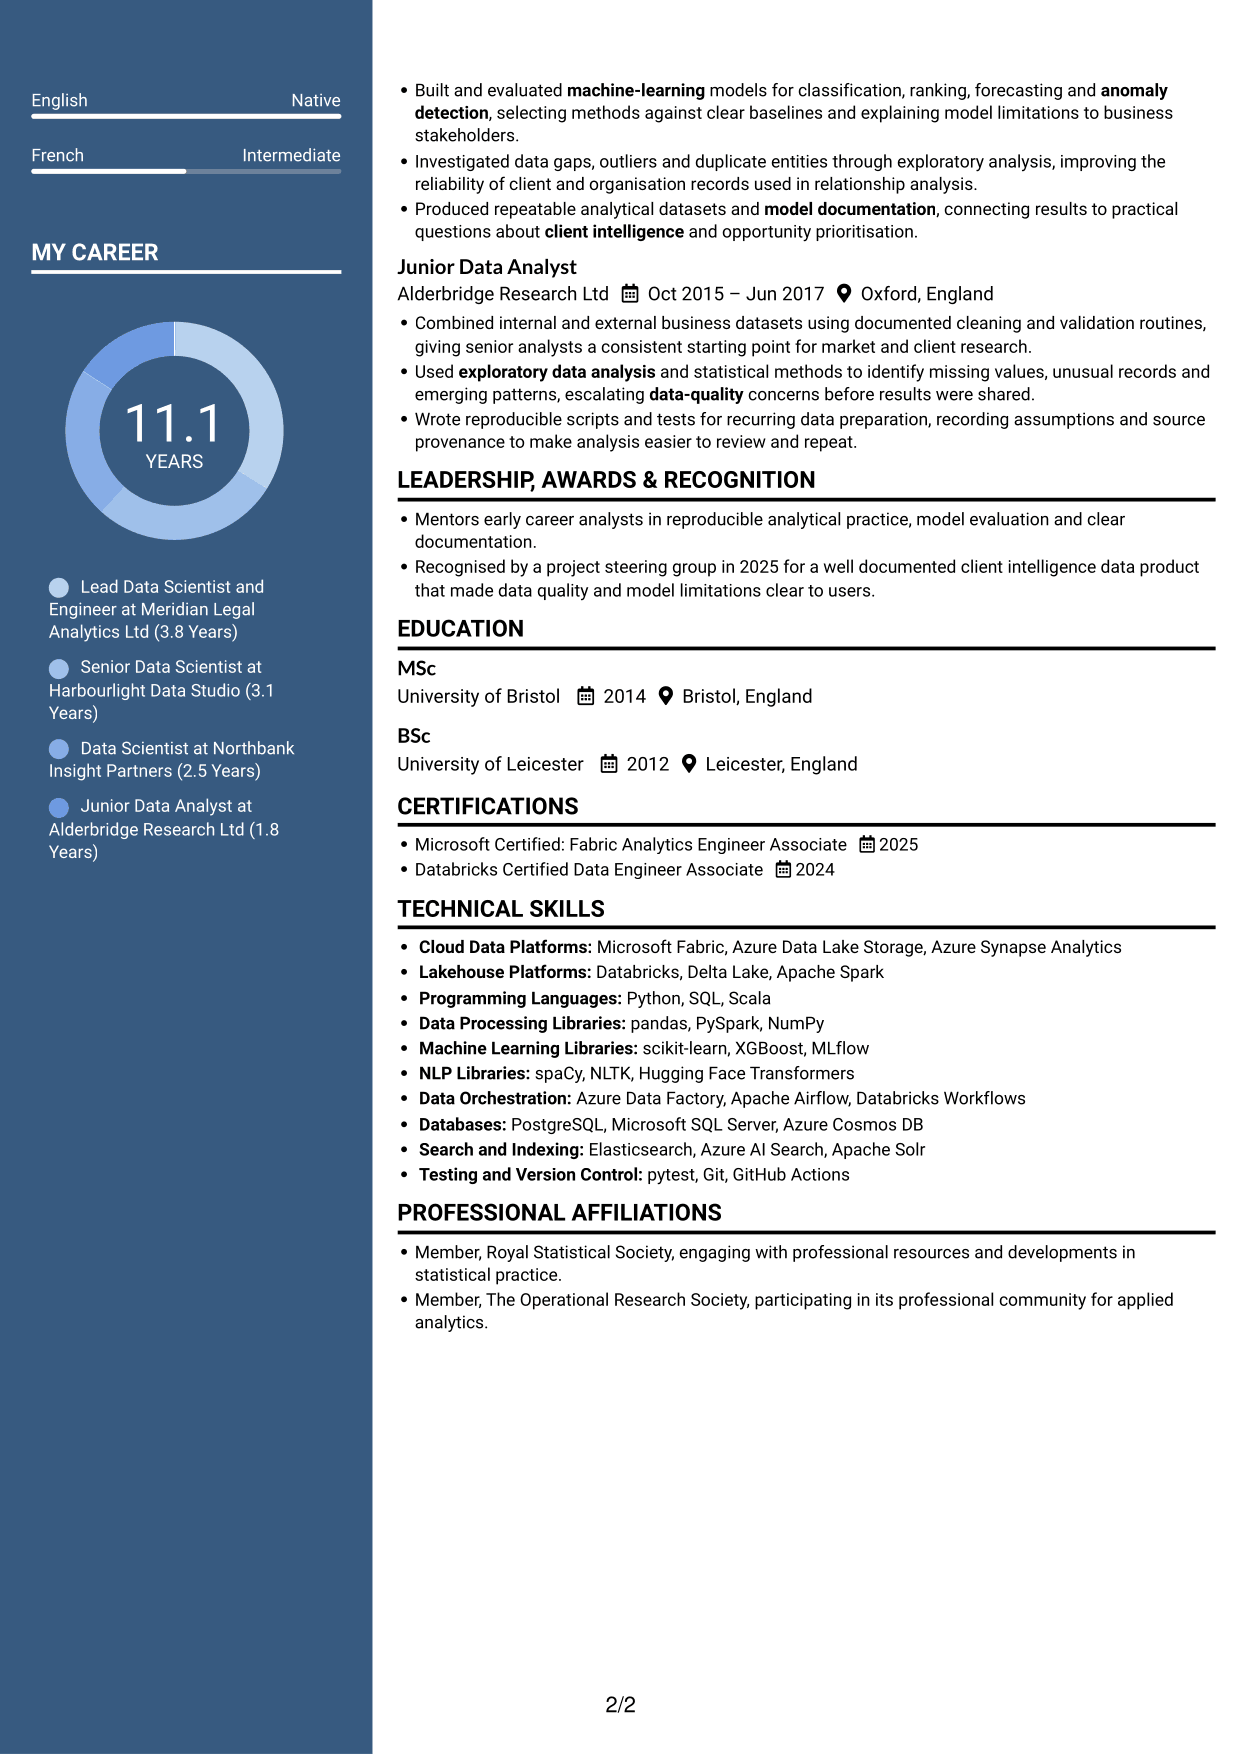
 
CV example — page 1   CV example — page 2

Why This Format Works

  • Two-column organisation keeps experience and supporting information in distinct areas.
  • Grouped experience entries help reviewers follow career progression across roles.
  • Skills, education and credentials can be found without reading every detail.

Best For

  • Photo-inclusive two-column CVs
  • Separate experience and supporting information
  • Grouped career progression
  • Quick access to skills and credentials
  • Personal image with divided content


Why Build Your Data Scientist & Engineer - Legal Data Products CV with ResumeInMinutes

ResumeInMinutes helps you organise your data engineering and data science evidence in a clear CV. Compare PNG image previews, then open an example in the editor to customise its content and layout.

  • Clear CV layouts
  • Readable section structure
  • Space for role-specific keywords
  • Organised skills and experience
  • PNG image previews
  • CV customisation in the editor

Choose a format that makes your work easy to follow. Keep the focus on governed data assets, dependable pipelines, careful model evaluation and clear documentation.


See Also


Frequently Asked Questions

Are these Data Scientist & Engineer - Legal Data Products CV templates ATS-friendly?

The examples use clear headings and sections to support scanning. Add relevant terms naturally, including Microsoft Fabric, Databricks, data quality, lineage, machine learning and NLP.

Are these separate CV examples or different layouts of one example?

This page presents one role-focused CV example in different layouts. Compare the PNG image previews, then open an example in the editor to customise it.

What should a Data Scientist & Engineer - Legal Data Products CV include?

Include a focused summary, relevant experience, skills, education and certifications. Show evidence of data pipelines, governed lakehouse assets, model evaluation, data quality and product delivery.

Which CV layout works well for this role?

Choose a layout with clear headings and a simple order for your experience, skills and education. This helps readers find technical terms and results without searching through dense text.

How can I show data product achievements on my CV?

Use concise bullet points to explain the task, your contribution and the result. Include supported evidence about reliable data assets, reduced reconciliation, model evaluation or how users applied the outputs.

Should I include a photo on my CV?

A photo is usually not needed for UK applications. Use the space for relevant skills, experience and evidence of your work instead.
ATS Score 98%

How we calculate this score

  • Keywords: 60% of the total. AI extracts keywords from your job description. If you do not provide one, a standard job description for the title matching your CV is used. This is not a match to a specific vacancy.
  • Text-based CV: 20%. The text CV assessed here receives 100 for this part.
  • CV quality: 20%. We start at 100 and subtract points for issues found by our CV checks, down to a minimum of zero.
  • Keyword coverage = round(100 × confirmed matches ÷ total keywords). Exact matches and supported equivalents verified by AI receive full credit; unsupported keywords receive none. Live text checks use the saved equivalents and do not request a new AI review. Without keywords, no overall ATS score is available.
  • Final score = 60% of keyword coverage + 20% of the text score + 20% of the quality score, rounded to a whole number. Without keywords, no overall ATS score is available.

What this score means

Our scores are estimates, not employer ratings. They may contain errors and do not guarantee accurate parsing, a ranking, an interview, or a job. Check your document against the employer’s requirements. You are responsible for relying on this score.

Terms and Conditions

Score weights: Keywords 60% · Text based CV 20% · CV quality 20%

Keyword coverage: 46 of 48 (96%) · CV quality: 100%

CV quality 100% · Weight 20% · Issues (0)

Details
  • ✓Name present: Joseph Cooper
  • ✓Email format: joseph.cooper@example.com
  • ✓Phone format: 07700 90XXXX
  • ✓Experience 1: Job title: Lead Data Scientist and Engineer
  • ✓Experience 1: Company name: Meridian Legal Analytics Ltd
  • ✓Experience 1: Work location: London, England
  • ✓Experience 1: Employment dates: Feb 2023 – Present
  • ✓Experience 1: Description or achievements: Present
  • ✓Experience 2: Job title: Senior Data Scientist
  • ✓Experience 2: Company name: Harbourlight Data Studio
  • ✓Experience 2: Work location: London, England
  • ✓Experience 2: Employment dates: Jan 2020 – Jan 2023
  • ✓Experience 2: Description or achievements: Present
  • ✓Experience 3: Job title: Data Scientist
  • ✓Experience 3: Company name: Northbank Insight Partners
  • ✓Experience 3: Work location: Cambridge, England
  • ✓Experience 3: Employment dates: Jul 2017 – Dec 2019
  • ✓Experience 3: Description or achievements: Present
  • ✓Experience 4: Job title: Junior Data Analyst
  • ✓Experience 4: Company name: Alderbridge Research Ltd
  • ✓Experience 4: Work location: Oxford, England
  • ✓Experience 4: Employment dates: Oct 2015 – Jun 2017
  • ✓Experience 4: Description or achievements: Present
  • ✓No placeholder fields
  • ✓No repeated achievement bullets
  • ✓No empty bullets

No issues found by the current checks.

Text Based CV 100% · Weight 20%

Parsed text
Joseph Cooper
07700 90XXXX
joseph.cooper@example.com
josephcooper
London, Greater London, EC2A 4BX
SUMMARY
Data Scientist and Engineer with 11 years of experience building analytical products and machine learning solutions, including for legal services and the wider business of law. Develop governed data assets from fragmented internal and external sources, combining data engineering with exploratory analysis, model evaluation and product delivery. Recent projects use Microsoft Fabric and Databricks to prepare permission aware datasets and document heavy information for reliable analysis. Partner with data owners, programme colleagues and system teams to define data quality, lineage and appropriate use, then publish curated outputs for client intelligence, opportunity identification, pricing and matter analysis. Maintain reproducible code, tests and clear evaluation records, including when using AI assisted methods.
EXPERIENCE
Lead Data Scientist and Engineer
Feb 2023 – Present
Meridian Legal Analytics Ltd
London, England
Built Microsoft Fabric and Databricks pipelines for legal and commercial information, bringing structured, semi-structured and unstructured internal and external sources through ingestion, cleaning, standardisation, enrichment, versioning and publication as reusable data assets.
Established permission-aware lakehouse models, schemas and data contracts for clients, organisations, people, matters, sectors, jurisdictions, opportunities and legal topics, giving R&D and the Data Programme a consistent foundation for product work.
Developed entity-resolution and enrichment workflows that connect records across client, matter and organisation sources; documented matching logic and exceptions to support reliable relationship mapping.
Embedded data-quality checks, lineage, provenance, observability, monitoring and change management in Fabric and Databricks workflows, reducing recurring reconciliation and making changes to source data easier to trace.
Used exploratory data analysis to investigate patterns, gaps, anomalies and data-quality issues, prioritising viable opportunities for client intelligence, opportunity identification, pricing and matter analysis.
Compared and validated statistical and machine-learning approaches for classification, ranking, recommendation, forecasting, anomaly detection, similarity and extraction, recording baselines, evaluation evidence and limitations for each use case.
Applied NLP, embeddings and LLM-assisted techniques to document-heavy data for classification, entity resolution, information extraction, clustering and relationship discovery; retained human review for uncertain outputs and defined appropriate-use boundaries.
Published curated datasets, features and analytical outputs through approved Fabric and Databricks tables, APIs, search indexes, batch pipelines and product features, matching delivery methods to each use case.
Maintained reproducible code, automated tests and data and model documentation; used AI agents and coding assistants to accelerate exploration, pipeline development, testing and documentation, verifying all outputs and retaining analytical judgement.
Senior Data Scientist
Jan 2020 – Jan 2023
Harbourlight Data Studio
London, England
Shaped client-intelligence and matter-analysis datasets from fragmented business records, assessing source quality, access permissions and fitness for use with data owners and system teams.
Created Databricks lakehouse models and reusable features for organisations, people, matters and sectors, enabling analysts to compare client relationships and identify relevant opportunities.
Applied exploratory data analysis and statistical modelling to uncover anomalies, classification signals and similarity patterns; compared model performance with transparent baselines before recommending product use.
Developed NLP-based document classification and information-extraction workflows, validating samples against reviewer-labelled records and documenting known gaps and appropriate use.
Published tested analytical outputs as curated datasets and batch pipeline products, with reproducible code, lineage notes and data-quality checks to support ongoing use by client-facing analysts.
Data Scientist
Jul 2017 – Dec 2019
Northbank Insight Partners
Cambridge, England
Prepared mixed-format commercial and professional-services data for analysis, standardising inconsistent records and documenting source definitions so analysts could reuse trusted datasets.
Built and evaluated machine-learning models for classification, ranking, forecasting and anomaly detection, selecting methods against clear baselines and explaining model limitations to business stakeholders.
Investigated data gaps, outliers and duplicate entities through exploratory analysis, improving the reliability of client and organisation records used in relationship analysis.
Produced repeatable analytical datasets and model documentation, connecting results to practical questions about client intelligence and opportunity prioritisation.
Junior Data Analyst
Oct 2015 – Jun 2017
Alderbridge Research Ltd
Oxford, England
Combined internal and external business datasets using documented cleaning and validation routines, giving senior analysts a consistent starting point for market and client research.
Used exploratory data analysis and statistical methods to identify missing values, unusual records and emerging patterns, escalating data-quality concerns before results were shared.
Wrote reproducible scripts and tests for recurring data preparation, recording assumptions and source provenance to make analysis easier to review and repeat.
LEADERSHIP, AWARDS & RECOGNITION
Mentors early career analysts in reproducible analytical practice, model evaluation and clear documentation.
Recognised by a project steering group in 2025 for a well documented client intelligence data product that made data quality and model limitations clear to users.
EDUCATION
MSc
2014
University of Bristol
Bristol, England
BSc
2012
University of Leicester
Leicester, England
CERTIFICATIONS
Microsoft Certified: Fabric Analytics Engineer Associate
2025
Databricks Certified Data Engineer Associate
2024
TECHNICAL SKILLS
Cloud Data Platforms: Microsoft Fabric, Azure Data Lake Storage, Azure Synapse Analytics
Lakehouse Platforms: Databricks, Delta Lake, Apache Spark
Programming Languages: Python, SQL, Scala
Data Processing Libraries: pandas, PySpark, NumPy
Machine Learning Libraries: scikit-learn, XGBoost, MLflow
NLP Libraries: spaCy, NLTK, Hugging Face Transformers
Data Orchestration: Azure Data Factory, Apache Airflow, Databricks Workflows
Databases: PostgreSQL, Microsoft SQL Server, Azure Cosmos DB
Search and Indexing: Elasticsearch, Azure AI Search, Apache Solr
Testing and Version Control: pytest, Git, GitHub Actions
SKILLS
Data engineering
Data science
Lakehouse modelling
Data quality
Data governance
Exploratory analysis
Statistical modelling
Machine learning
Model validation
Natural language processing
Entity resolution
Information extraction
Client intelligence
Legal data products
Responsible AI
PROFESSIONAL AFFILIATIONS
Member, Royal Statistical Society, engaging with professional resources and developments in statistical practice.
Member, The Operational Research Society, participating in its professional community for applied analytics.
LANGUAGES
English (Native)
French (Intermediate)

Matched keywords (46)

  • Microsoft Fabric
  • Databricks
  • data engineering
  • Data science
  • Built Microsoft Fabric and Databricks pipelinesOriginal keyword in JD: Data pipelines
  • Established permission-aware lakehouse models, schemas and data contractsOriginal keyword in JD: Lakehouse architecture
  • Lakehouse modellingOriginal keyword in JD: Data modelling
  • data contracts
  • data quality
  • Data governance
  • lineage, provenanceOriginal keyword in JD: Data provenance
  • observabilityOriginal keyword in JD: Data observability
  • exploratory data analysis
  • statistical modelling
  • machine learning
  • Model validation
  • Natural language processing
  • embeddings
  • Applied NLP, embeddings and LLM-assisted techniquesOriginal keyword in JD: Large language model-assisted methods
  • entity-resolution
  • information extraction
  • relationship mapping
  • enrichmentOriginal keyword in JD: Data enrichment
  • classification
  • ranking
  • recommendationOriginal keyword in JD: Recommendation systems
  • forecasting
  • anomaly detection
  • similarityOriginal keyword in JD: Similarity analysis
  • clustering
  • structured, semi-structured and unstructured internal and external sourcesOriginal keyword in JD: Structured, semi-structured and unstructured data
  • prepare permission aware datasetsOriginal keyword in JD: Permission-aware data access
  • assessing source qualityOriginal keyword in JD: Source quality assessment
  • curated datasets
  • APIs
  • search indexes
  • batch pipelines
  • reproducible code
  • automated testsOriginal keyword in JD: Automated testing
  • model documentation
  • recording baselines, evaluation evidence and limitations for each use caseOriginal keyword in JD: Evaluation baselines
  • Responsible AI
  • AI agents and coding assistants
  • client intelligence
  • including for legal services and the wider business of lawOriginal keyword in JD: Legal services and the business of law
  • Partner with data owners, programme colleagues and system teams to define data quality, lineage and appropriate useOriginal keyword in JD: Data owner and system team collaboration

Missing keywords (2)

  • data lineage
  • Reusable data products
Disclaimer: All names, images, contact information, employment histories, achievements, security clearances, military credentials, and other qualifications shown in this content are fictional and used for illustrative purposes only. Any resemblance to actual persons, living or deceased, is purely coincidental.

CV and cover letter examples and recommendations in this article reflect general best practices and professional experience and are provided for guidance only. Results may vary based on role, industry, region, and hiring organisation.

Content Accuracy and Verification: To the fullest extent permitted by applicable law, we do not represent or warrant that CV or cover letter guidance, examples, recommendations, or related information are accurate, complete, current, error-free, or suitable for any particular purpose. You are responsible for independently reviewing and verifying the information before relying on it.

ATS and Cover Letter Scores: ATS scores are estimates calculated using our own formula, informed by publicly available guidance on CV formatting and keyword matching. They are not scores issued or endorsed by an ATS provider or employer. Cover letter scores are also our own assessments. Parsing, weighting, screening criteria, and results vary between systems, employers, job descriptions, and document formats. No score guarantees successful parsing, a particular ranking, an interview, or employment. Use scores as general guidance and independently check your documents against the employer’s requirements. To the fullest extent permitted by applicable law, we accept no liability for errors in scores or parsing, or losses arising from reliance on these assessments. Nothing in this notice excludes liability or limits consumer rights that cannot lawfully be excluded or limited.

Terms and Conditions
 
> JP 1 1
PDF Footer and Margins Setup
The margins are applied to the document, and the footer appears in both the preview and the PDF

Footer Font Settings

Are you applying for a specific job
so we can tailor your CV to it?
Are you applying for a specific job
so we can tailor your cover letter to it?

Your data stays private and is never used for training.Privacy Policy

Type your details as text to generate a personalised CV Type your details as text to generate a personalised cover letter
Website link found! Ready to create CV from:

Your data stays private and is never used for training.Privacy Policy

Drag the into the box to verify you're human.
Drop here

My CVs

Showing {number_of_files} files (out of {total_of_all_files} total)
Name File Type Last Modified: Description:

Rename File

Filename already exists!

Delete Files

Warning: This action is irreversible. Once you click submit, the files will be permanently deleted.

Heading text
Upload From Computer Upload
Select From Existing
LinkedIn
Drag & Drop files anywhere in this tab, or

Uploaded Files

Delete Name Last Updated Use This File
Select this to use the file for generating your CV and cover letter. Only one source—uploaded file, selected file, or LinkedIn text—can be used.

My Files

CVs or cover letters you create will appear here. No files available yet.
Delete Name Last Updated Use This File
Select this to use the file for generating your CV and cover letter. Only one source—uploaded file, selected file, or LinkedIn text—can be used.

Add LinkedIn Profile PDF

You can download your LinkedIn profile as a PDF by opening linkedin.com in a web browser, clicking your profile photo, selecting the “More” or “Resources” button, and choosing “Save to PDF.” You can then attach the PDF using the Upload From Computer tab.

Paste Your LinkedIn Profile Text

If you have copied the LinkedIn profile text, paste it below. See how to copy your profile from LinkedIn

Select this to use the LinkedIn profile text for generating your CV and covering letter. Only one source—uploaded file, selected file, or LinkedIn text—can be used.

Try these controls

<
>