197 Mechanical Engineer Interview Questions & Answers

83 top • 12 Boeing • 9 Bosch • 12 Caterpillar • 9 Ford • 12 GE Aerospace • 12 Honeywell • 11 John Deere • 10 Lockheed Martin • 10 Rolls-Royce • 4 Siemens Energy • 10 Tesla • 3 Trane Technologies

Mechanical Engineer icon

Questions with Detailed ExplanationsWith Detailed Explanations

(Last Updated: September 13, 2026)

71. Which software tools have you used for failure analysis?Troubleshooting And Failure AnalysisEasy

Question Details

Identify software you have used in your failure investigations.

Short Interview Answer (30-60 seconds)

I would name only the software I have actually used and briefly explain what each tool contributed to the investigation. Depending on the work, that could include CAD software for reviewing geometry and interfaces, FEA software for checking stress or deformation hypotheses, and spreadsheet or numerical-analysis tools for reviewing measurements and trends. I may also use structured methods such as Five Whys, fault tree analysis, or FMEA to organize possible causes. The key is that I use software to test hypotheses against physical evidence rather than treating the software result as the root cause by itself, and I verify the corrective action with a repeatable test.

Detailed Explanation

Software is useful in failure analysis when it helps organize evidence, quantify a suspected mechanism, or test competing explanations. I would not simply list software names. I would explain what I used each tool for, what evidence it helped evaluate, and how I checked its results against the failed hardware and actual operating conditions.

I would start by preserving the failed component and available evidence. Then I would document the symptom, inspect the component, review service history, and compare actual operating conditions with the original design assumptions. After that, I would select tools that directly support the investigation.

CAD software can help review geometry, interfaces, fits, clearances, alignment, and assembly conditions. FEA or other simulation software can help evaluate whether a proposed loading condition could produce the observed stress, deformation, contact behavior, or fatigue-sensitive region. Spreadsheet or numerical-analysis software can help evaluate vibration, temperature, pressure, load, dimensional, or other measurement data and identify trends or abnormal behavior. Structured root cause methods such as Five Whys, fault tree analysis, FMEA, or fishbone analysis can help organize competing causes and keep the investigation focused on evidence.

The software result is only one part of the investigation. For example, a high-stress region in an FEA model does not prove that stress caused an actual fracture. I would compare the predicted location and mechanism with physical evidence such as the fracture surface, crack origin, wear pattern, corrosion, overheating, misalignment, lubrication condition, or other inspection findings. I would also review the model assumptions, including loads, restraints, contacts, geometry, material inputs, and operating conditions, before relying on the result.

Because the question asks what I have personally used, I would only name specific products that genuinely match my experience. Representative software categories may include CAD packages, FEA solvers, spreadsheets, numerical-analysis environments, vibration-analysis software, or data-acquisition and plotting tools, but I would not claim experience with a particular product unless I had actually used it.

Useful Questions to Ask the Interviewer
  • Are you mainly interested in simulation tools, measurement-data tools, or tools used to document root cause analysis?
  • What types of failures are most common in this role, such as fatigue, wear, vibration, bearing failures, seal failures, overheating, or structural problems?
  • Does the team normally perform detailed simulation internally, or is failure analysis mainly driven by inspection and test data?
How to Explain It in an Interview

A strong response is to name the software you genuinely know, state the specific failure-analysis task you used it for, explain what hypothesis or evidence it helped evaluate, and describe how you verified the conclusion. For example, instead of saying only that you know an FEA package, explain that you used it to investigate whether a suspected load path could create a critical stress region and then compared that prediction with the actual damage location and inspection evidence. If you used spreadsheet or numerical-analysis software, explain how it helped compare expected and actual operating behavior or identify trends in measurements. Finish by emphasizing that the final root cause should be supported by multiple consistent pieces of evidence and that the corrective action should be confirmed under representative conditions.

Technical Approach
  1. Preserve the failed component, photographs, measurements, service history, and other available evidence.
  2. Separate the observed symptom from the failure mode, physical failure mechanism, and possible root causes.
  3. Compare actual operating conditions with design assumptions and expected service conditions.
  4. Develop competing hypotheses instead of committing immediately to one cause.
  5. Select software that directly helps evaluate those hypotheses, such as CAD for geometry and interfaces, simulation for physical response, or data-analysis tools for measured trends.
  6. Check important software inputs, assumptions, constraints, units, and limitations.
  7. Compare software predictions with inspection findings and measured physical evidence.
  8. Identify the root cause only when the available evidence consistently supports it and competing explanations have been addressed.
  9. Define corrective action that addresses the root cause rather than only the symptom.
  10. Verify the correction with a repeatable test under representative operating conditions and define measures to reduce recurrence.
Practical Insights

The main tradeoff is between analysis detail and confidence. A spreadsheet, hand calculation, or simple model may be enough when the failure mechanism is clear and measurements strongly support it. A detailed simulation may be useful when geometry, load paths, contact, thermal behavior, or stress distribution are important, but it requires reliable inputs and careful validation. More sophisticated software does not automatically produce a more reliable conclusion. The investigation is strongest when software results agree with physical inspection, measurements, operating history, and a plausible failure mechanism.

Why Interviewers Ask This

Interviewers want to assess whether you can use engineering software as part of an evidence-based failure investigation rather than treating software output as proof of the root cause. They are evaluating whether you understand how tools for CAD review, simulation, data analysis, and structured root cause analysis support inspection, measurements, operating-history review, hypothesis testing, corrective action, and verification.

Common interview mistakes

Common mistakes include listing software names without explaining how they supported the investigation; claiming a simulation result proves the root cause; naming tools the candidate has not actually used; replacing failed components before preserving evidence; focusing only on the visible symptom instead of the failure mechanism and root cause; using unrealistic loads, restraints, contacts, or other model assumptions; ignoring service history and actual operating conditions; and implementing a corrective action without a verification test.

Interview tip

Name only software you have genuinely used. For each tool, give one clear connection between the tool and the engineering decision it supported: what evidence you examined, what hypothesis you tested, and how you checked the result. A short example showing that connection is stronger than a long list of software packages.
Interviewer may ask next
How would you validate a simulation result used in a failure investigation?

I would first check the model inputs and assumptions, including geometry, loads, restraints, contacts, units, material inputs, and operating conditions. Then I would compare the predicted behavior with independent physical evidence such as the actual damage location, fracture or wear pattern, measured deformation, vibration, temperature, or other test data. I would also consider competing hypotheses where practical. I would not treat agreement from one simulation as proof; confidence increases when simulation, inspection, measurements, service history, and the expected failure mechanism all support the same conclusion.

What would you do if detailed simulation software was not available?

I would still follow the same root cause process. I would preserve evidence, inspect the failed component, review operating history, compare expected and actual conditions, take relevant measurements, and develop competing hypotheses. I could use hand calculations, basic engineering models, CAD measurements, spreadsheets, test data, Five Whys, fault trees, or FMEA as appropriate. The objective is not to use the most sophisticated tool; it is to gather enough reliable evidence to identify the root cause and verify that the corrective action prevents recurrence.

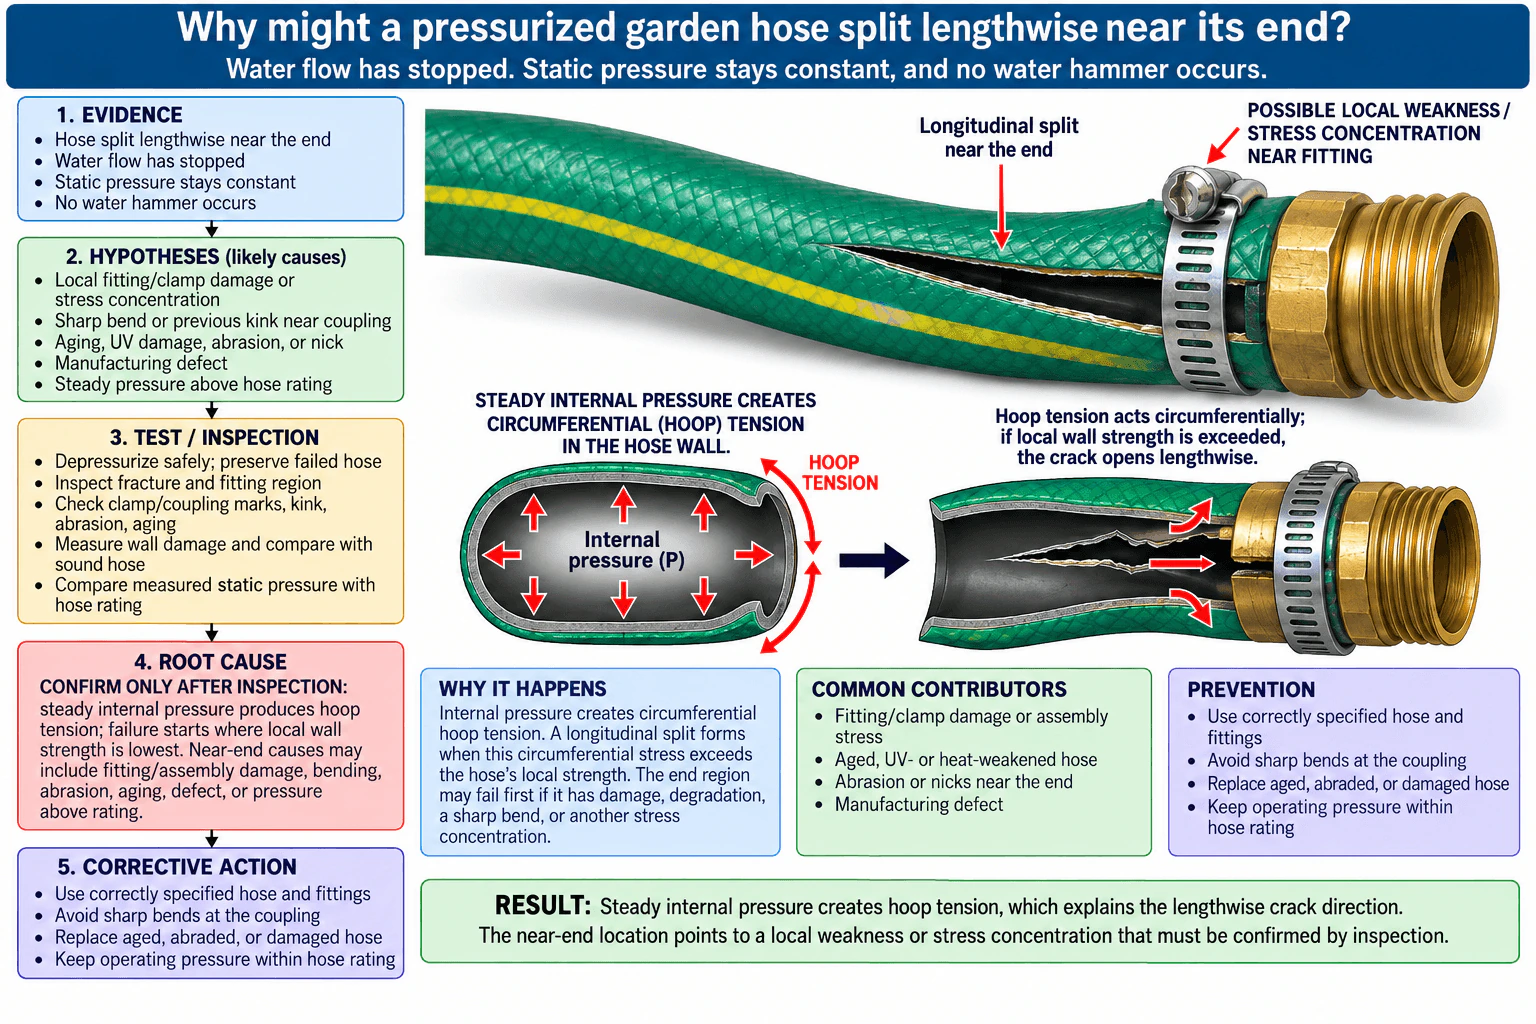
72. Why might a pressurized garden hose split lengthwise near its end?Troubleshooting And Failure AnalysisMedium

Question Details

Water flow has stopped. Static pressure stays constant, and no water hammer occurs.

Short Interview Answer (30-60 seconds)

Internal pressure creates circumferential, or hoop, tension in the hose wall. If that tension exceeds the local wall strength, a crack can open lengthwise. Since the pressure is steady and there is no water hammer, I would look for a local weakness or stress concentration near the fitting rather than blame a transient surge. I would check for fitting or clamp damage, a sharp bend or previous kink, abrasion, aging, a manufacturing defect, and whether the static pressure exceeds the hose rating, then confirm the cause with inspection and measurement.

Detailed Explanation

A lengthwise split gives an important clue about the loading mechanism. Internal water pressure acts outward on the hose wall and produces circumferential, or hoop, tension around the hose. If that circumferential tensile stress exceeds the hose's local strength, the crack can open and propagate in the longitudinal direction.

The supplied operating evidence narrows the diagnosis. Water flow has stopped, so the hose is in a static pressurized condition. The pressure remains constant, and water hammer is explicitly absent, so a transient surge should not be the default explanation. However, constant pressure does not automatically mean acceptable pressure; the measured static pressure still needs to be compared with the hose's rated working pressure.

The observed symptom is a split near the end. The failure mode is rupture of the hose wall. The loading mechanism is internal pressure producing circumferential hoop tension. The root cause is not yet known. Because the failure is near the end fitting, plausible competing causes include local fitting or clamp damage, assembly stress, a sharp bend or previous kink near the coupling, abrasion or a nick, aging or UV degradation, a manufacturing defect, or steady pressure above the hose rating.

The investigation should begin by preserving the failed hose and fitting as evidence and establishing a safe, depressurized condition. Inspect the fracture and the region directly under and beside the fitting. Look for clamp or coupling marks, cuts, abrasion, cracking, hardening, damaged reinforcement if visible, and evidence of a previous kink or excessive bend. Compare the damaged region with an undamaged section of the same hose where practical. Measure the actual static pressure and compare it with the hose rating rather than assuming that steady pressure is normal pressure.

The diagnosis should remain conditional until the physical evidence supports one hypothesis better than the others. Concentrated damage at the coupling with otherwise sound hose would support a fitting or assembly-related cause. A permanent bend, flattened section, or damaged reinforcement near the coupling would support excessive bending or a previous kink. Widespread degradation would make aging or environmental exposure more credible. If the measured static pressure is above the hose rating, excessive steady pressure becomes a strong contributing or root-cause candidate.

Corrective action should follow the confirmed cause. That can include using a correctly specified hose and fitting, eliminating sharp bends at the coupling, removing abrasion sources, replacing aged or damaged hose, and keeping operating pressure within the hose rating. After repair, verify the system under representative conditions and inspect for leakage, bulging, fitting movement, renewed damage, or abnormal bending. Recurrence prevention should address the confirmed failure mechanism rather than simply replacing the failed hose.

Useful Questions to Ask the Interviewer
  • What is the hose's rated working pressure, and what static pressure was actually measured?
  • Is the split directly under the fitting, immediately beside it, or farther away?
  • Are there clamp marks, abrasion, cuts, a sharp bend, or evidence of a previous kink near the failed region?
  • How old is the hose, and has it been exposed to sunlight, heat, chemicals, or repeated mechanical damage?
  • Has the same failure occurred on other hoses in the same installation?
Why might a pressurized garden hose split lengthwise near its end? diagram
How to Explain It in an Interview

I would start with the crack direction. A longitudinal split is consistent with circumferential hoop tension produced by internal pressure. Then I would use the supplied evidence to narrow the possibilities: pressure is steady and water hammer is absent, so I would not blame a transient surge without evidence. The near-end location suggests a local weakness or stress concentration, but that is still a hypothesis. I would preserve the failed hose, inspect the fracture and fitting region, check for fitting damage, bending, kinking, abrasion, aging, and other local defects, and compare the measured static pressure with the hose rating. Only after those checks would I identify the root cause. I would then correct that specific cause and verify the repair under representative pressure and routing conditions.

Technical Approach
  1. Establish a safe, depressurized condition and preserve the failed hose and fitting as evidence.
  2. Record the known facts: longitudinal split near the end, stopped flow, constant static pressure, and no water hammer.
  3. Separate the symptom, failure mode, loading mechanism, and unknown root cause.
  4. Use the crack orientation to identify internal pressure and circumferential hoop tension as the relevant loading mechanism.
  5. Form competing hypotheses: fitting or clamp damage, assembly stress, sharp bending or a previous kink, abrasion or a nick, aging or UV degradation, manufacturing defect, and static pressure above the hose rating.
  6. Inspect the fracture and fitting region and compare the damaged area with sound hose.
  7. Measure the actual static pressure and compare it with the hose's rated working pressure.
  8. Select the root cause only when physical evidence and measurements support one hypothesis more strongly than the alternatives.
  9. Apply corrective action tied to the confirmed cause, such as proper hose and fitting selection, improved routing, removal of abrasion sources, replacement of degraded hose, or pressure correction.
  10. Verify the repair under representative conditions and define recurrence-prevention actions.
Practical Insights

The main tradeoff is between quickly replacing the failed hose and doing enough diagnosis to prevent recurrence. A visual inspection is fast but can miss excessive static pressure or internal reinforcement damage. Pressure measurement and closer inspection take more time but provide stronger evidence. Another important tradeoff is avoiding premature conclusions: the fitting is close to the failure, but proximity alone does not prove that the fitting caused it. Fitting damage, bending, abrasion, aging, defects, and excessive steady pressure should remain competing explanations until inspection and measurement distinguish them.

Why Interviewers Ask This

This tests whether the candidate can distinguish the observed symptom, failure mode, loading mechanism, and root cause; use the supplied evidence to reject unsupported explanations; form competing hypotheses; and define inspections and measurements that confirm the actual cause before recommending corrective action.

Common interview mistakes

Common mistakes include assuming that constant pressure must be safe pressure, blaming water hammer even though it is explicitly excluded, treating the fitting as the confirmed root cause without inspection, confusing radial pressure loading with the circumferential hoop tension carried by the hose wall, replacing the hose before preserving failure evidence, ignoring bend or kink damage near the coupling, and failing to compare measured static pressure with the hose rating.

Interview tip

Use the crack direction as a diagnostic clue, not as the complete root-cause conclusion. Explain the pressure-to-hoop-tension mechanism first, separate confirmed facts from competing hypotheses, and finish with the inspection and pressure measurements that would confirm the cause and the verification steps you would perform after correction.

Interviewer may ask next
What evidence would support a fitting or coupling-related root cause?

I would look for localized clamp or coupling marks, cuts, crushed or displaced reinforcement, deformation, assembly damage, or a sharp bend immediately beside the fitting while the rest of the hose remains comparatively sound. Those findings would support a local fitting or assembly-related stress concentration. I would still compare the actual static pressure with the hose rating before closing the investigation because excessive pressure could also contribute.

How would your diagnosis change if the measured static pressure were above the hose's rated working pressure?

Excessive steady pressure would become a strong root-cause or contributing-factor candidate because higher internal pressure increases the circumferential tension carried by the hose wall even without water hammer. I would still inspect the near-end region for local damage because a weakened area may determine where the rupture begins. The corrective action would need to address both conditions if both are present: reduce operating pressure to an acceptable level and replace the damaged hose with a correctly specified assembly, then verify the system under representative operating conditions.

73. How would you gather evidence from failed components or systems?Troubleshooting And Failure AnalysisEasy

Short Interview Answer (30-60 seconds)

I would first make the system safe and preserve the failed components in their as-found condition. Before cleaning, disassembling, or replacing anything, I would document the failure with photographs, component locations and orientations, service history, alarms, operating conditions, and relevant witness observations. Then I would inspect and measure the failed parts, looking for evidence such as fracture features, fatigue cracking, wear, corrosion, overheating, lubrication problems, misalignment, or abnormal vibration. I would compare the evidence with the design assumptions and normal operating conditions, develop competing root-cause hypotheses, and use targeted measurements or tests to eliminate them. Finally, I would confirm the most strongly supported cause and verify the corrective action with a repeatable test under representative conditions.

Detailed Explanation

Gathering good failure evidence starts before I try to repair anything. A failed component can contain information about how the failure developed, and careless handling, cleaning, disassembly, or replacement can destroy that information. My goal is to preserve the as-found condition, document what happened, collect objective measurements, and build a defensible chain from symptom to failure mode, mechanism, and root cause.

I would begin by establishing safe conditions and defining the physical boundary of the investigation. I would identify what equipment failed, what neighboring systems could have influenced it, and what conditions existed immediately before and during the event. I would separate confirmed facts from assumptions and unknowns.

Next, I would document the scene and failed hardware before disturbing it. That can include photographs from several angles, component orientation, fastener positions, leak paths, debris locations, discoloration, wear marks, deformation, fracture locations, lubricant condition, and evidence of overheating or impact. If several parts are removed, I would label and preserve them so their original locations and orientations remain traceable.

I would also collect operating evidence. Depending on the system, that could include service history, maintenance records, previous repairs, load history, temperature, pressure, speed, vibration, alignment, lubrication condition, alarms, operator observations, and environmental exposure. I would compare actual service conditions with the design assumptions and expected operating envelope rather than assuming the failed component alone caused the event.

The failed component itself would then be inspected using non-destructive or minimally destructive methods first. I would look for clues associated with plausible failure mechanisms. For example, fracture-surface features can help identify an initiation region and crack-growth direction; progressive fatigue features may support a fatigue mechanism, while substantial plastic deformation can support an overload mechanism in a ductile material. Wear patterns can indicate possibilities such as misalignment, inadequate lubrication, contamination, or abnormal contact. Corrosion products, heat discoloration, seal damage, bearing damage, fretting, or unusual debris can provide additional evidence. I would avoid cleaning a fracture surface or removing deposits until their condition has been documented and, if appropriate, sampled.

Measurements are important because visual impressions alone can be misleading. I would measure relevant dimensions, clearances, runout, alignment, surface condition, vibration, temperatures, or other parameters only when they are relevant to the suspected failure. When appropriate and available, I would compare the failed part with an undamaged reference component, engineering drawing, specification, baseline measurement, or known-good operating condition.

After gathering the evidence, I would organize it into competing explanations instead of immediately selecting one cause. I might use Five Whys, fault tree analysis, fishbone analysis, or FMEA depending on the complexity of the problem. I would clearly separate the symptom, such as a seized bearing, from the failure mode, such as loss of intended rotation, the physical mechanism, such as adhesive wear or overheating, and the underlying root cause that allowed the condition to occur.

For each hypothesis, I would ask what evidence should exist if that hypothesis were true and what evidence would contradict it. I would then perform targeted inspections or tests that discriminate between the possibilities. This reduces confirmation bias and helps avoid replacing components without understanding why they failed.

Once the evidence supports a root cause strongly enough, I would define a corrective action that addresses that cause rather than only the damaged part. The final step is verification. I would test the repaired or modified system under representative operating conditions and confirm that the relevant failure indicator, such as abnormal temperature, vibration, wear, leakage, or misalignment, has been corrected. I would also identify any appropriate inspection, maintenance, design, or operating changes needed to reduce recurrence.

Useful Questions to Ask the Interviewer
  • What type of component or system failed, and is the equipment currently in a safe condition for inspection?
  • Has the failed component already been removed, cleaned, repaired, or otherwise disturbed?
  • What operating conditions existed immediately before the failure, such as load, speed, temperature, pressure, or vibration?
  • Is service history, maintenance history, alarm data, or previous failure information available?
  • Are there undamaged comparison parts, drawings, specifications, or baseline measurements available?
  • Is the goal immediate troubleshooting, a formal root-cause investigation, or both?
How to Explain It in an Interview

I would explain that my first priority is to preserve evidence rather than immediately replace the failed part. I would document the as-found condition, operating history, and failed hardware, then collect measurements relevant to the suspected mechanisms. I would compare actual operation with intended design conditions and develop more than one possible cause. I would use the evidence to eliminate hypotheses systematically and clearly distinguish the observed symptom from the failure mode, mechanism, and root cause. Finally, I would verify the corrective action with a repeatable test under representative conditions so I know the underlying problem was addressed rather than temporarily hidden.

Technical Approach
  1. Make the equipment safe and define the investigation boundary without unnecessarily disturbing the failed hardware.
  2. Preserve the as-found condition and retain failed parts, debris, fluids, and other potentially useful evidence when appropriate.
  3. Photograph and document component locations, orientations, fracture areas, wear patterns, discoloration, leakage, deformation, deposits, and surrounding conditions.
  4. Collect relevant service history, maintenance history, alarms, operating data, loads, temperatures, pressures, speeds, vibration information, environmental exposure, and witness observations when available.
  5. Separate confirmed facts, assumptions, and unknowns.
  6. Compare actual operating conditions with drawings, specifications, design assumptions, and known-good behavior.
  7. Inspect failed components using non-destructive or minimally destructive methods first and identify plausible failure modes and mechanisms.
  8. Take relevant measurements such as dimensions, clearances, alignment, runout, vibration, temperature, surface condition, or material-related measurements when justified by the hypotheses.
  9. Develop competing root-cause hypotheses using methods such as Five Whys, fault tree analysis, fishbone analysis, or FMEA as appropriate.
  10. Identify evidence that would support or contradict each hypothesis and perform targeted tests or inspections to distinguish between them.
  11. Select corrective action based on the supported root cause rather than merely replacing the visibly damaged component.
  12. Verify the correction under representative operating conditions and define actions that reduce the likelihood of recurrence.
Practical Insights

The main tradeoff is gathering enough reliable evidence to support the root-cause conclusion while avoiding unnecessary testing, downtime, cost, or destruction of evidence. Simple failures may be resolved through careful documentation, measurements, and service history, while complex or high-consequence failures may require specialized laboratory analysis. The order of work matters because destructive examination can permanently remove evidence, so the as-found condition and appropriate non-destructive observations should be preserved first. Another challenge is uncertainty: operating records may be incomplete, and different mechanisms can create similar symptoms. Comparing competing hypotheses against objective evidence reduces the risk of accepting the first plausible explanation.

Why Interviewers Ask This

Interviewers want to see whether I can investigate a failure systematically without destroying useful evidence or jumping to conclusions. They are evaluating whether I preserve failed parts, document operating conditions, distinguish the visible symptom from the failure mode, mechanism, and root cause, use measurements to test competing explanations, and verify that corrective action actually prevents recurrence.

Common interview mistakes

Common mistakes include immediately replacing the failed part before documenting it, cleaning fracture surfaces or deposits before inspection, discarding debris or lubricant that may contain useful evidence, assuming the visibly damaged component is the root cause, relying only on visual impressions without measurements, ignoring operating and maintenance history, changing several variables at once during troubleshooting, considering only one hypothesis, confusing a symptom with the underlying failure mechanism, and declaring the problem solved without a verification test.

Interview tip

Emphasize the sequence: make the system safe, preserve the evidence, document the as-found condition, gather operating history and measurements, compare expected versus actual conditions, test competing root-cause hypotheses, and verify the corrective action. Mentioning that you would avoid cleaning, disassembling, or replacing evidence before documenting it demonstrates strong practical failure-analysis judgment.

Interviewer may ask next
How would you handle the investigation if important operating data was missing?

I would clearly label the missing information as an unknown instead of filling the gap with assumptions. I would look for independent evidence such as physical damage patterns, maintenance records, control-system logs, neighboring equipment behavior, witness observations, retained parts, lubricant or debris condition, and measurements from comparable equipment. I would then build several plausible hypotheses and identify which conclusions are strongly supported and which remain uncertain. If the missing data prevents a confident root-cause conclusion, I would state that limitation and recommend appropriate monitoring or instrumentation so the suspected mechanism can be tested if the condition occurs again.

What would change if the failed component had already been cleaned or replaced?

I would recognize that some primary evidence may have been permanently lost, especially surface deposits, wear debris, lubricant condition, fracture-surface contamination, component orientation, and the original installation state. I would preserve whatever evidence remains and place more emphasis on existing photographs, removed parts, maintenance records, replacement history, measurements, operating data, adjacent components, and witness observations. I would avoid claiming a level of certainty that the remaining evidence cannot support. I would also improve the evidence-preservation process for future failures so failed parts are documented and retained before repair or cleaning.

74. How do you record and present the findings of a failure investigation?Troubleshooting And Failure AnalysisEasy

Short Interview Answer (30-60 seconds)

I would document a failure investigation so another engineer can trace the conclusion back to the evidence. I would record the failed component identification, operating history, observed symptoms, photographs, measurements, inspection results, and any relevant test data while preserving the original evidence. Then I would separate the failure mode, physical failure mechanism, contributing factors, and root cause. In the final report, I would present the evidence, competing hypotheses, reasoning, corrective actions, and verification plan, while clearly identifying assumptions, unknowns, and limitations. The goal is a factual and reproducible record, not just a statement of what I think failed.

Detailed Explanation

A good failure-investigation report should allow someone who was not involved in the investigation to understand what happened, what evidence was collected, how the evidence was interpreted, and why the recommended corrective action follows from the identified root cause. I keep observations separate from interpretations and conclusions so the reasoning remains traceable.

Useful Questions to Ask the Interviewer
  • What type of component or system failed, and what function was it expected to perform?
  • Is the failed hardware still available, and are there any evidence-preservation or safety requirements before inspection?
  • What operating, maintenance, and service-history information is available?
  • Is the objective only to identify the physical failure mechanism, or also to determine the underlying root cause and define corrective actions?
  • Who will use the final report, such as engineering, maintenance, quality, management, or a customer?

I would first create a controlled record of the available evidence. That normally includes component identification, location, date and circumstances of the failure, operating conditions, service history, maintenance history, photographs, sketches where useful, inspection observations, dimensional measurements, test results, and the condition of nearby components. Failed parts should be preserved so that cleaning, cutting, disassembly, or other examination does not destroy important evidence.

Next, I would organize the findings into distinct levels. The symptom is what was noticed, such as excessive vibration or leakage. The failure mode describes how the component stopped performing its function, such as a fractured shaft or failed seal. The failure mechanism explains the physical process, such as fatigue cracking, abrasive wear, corrosion, overheating, or inadequate lubrication. The root cause explains why conditions existed that allowed that mechanism to occur. Keeping these levels separate prevents a symptom from being incorrectly presented as the root cause.

I would compare actual operating conditions with the design assumptions and known service history. Measurements and observations should be recorded with units, instrument identification when relevant, and enough context to understand what was measured. If several explanations are possible, I would document the competing hypotheses and state what evidence supports or contradicts each one. Methods such as Five Whys, fault tree analysis, fishbone analysis, or FMEA can help organize the reasoning, but the conclusion still has to be supported by physical evidence.

How to Explain It in an Interview

I would explain that my final report follows a simple evidence-to-conclusion structure. I start with the problem statement and scope, then document the equipment and operating context, preserve and catalogue the evidence, record inspections and measurements, identify the failure mode and mechanism, evaluate possible causes, and state the most strongly supported root cause. I clearly label assumptions, unresolved questions, and limitations instead of presenting uncertain conclusions as facts.

The corrective-action section should connect directly to the root cause. For example, replacing a damaged bearing may restore operation, but if the evidence shows misalignment caused the bearing damage, the report should address the misalignment rather than treating bearing replacement as the complete corrective action. I would also distinguish immediate containment or repair from longer-term recurrence-prevention actions.

Finally, I would define how the corrective action will be verified. The verification should reproduce representative operating conditions and use measurable acceptance criteria, such as vibration, temperature, leakage, dimensional condition, or another relevant performance measure. If the verification does not demonstrate that the failure-driving condition has been removed, I would reopen the investigation rather than assume the repair solved the root cause.

The final presentation should be concise enough for decision-makers but detailed enough for technical review. I would usually lead with the failure, root cause, supporting evidence, corrective action, and verification result or plan, followed by the detailed evidence and analysis. That gives management a clear conclusion while preserving the engineering traceability needed for future troubleshooting and recurrence prevention.

Technical Approach
  1. Define the failed item, investigation scope, safety conditions, and purpose of the report.
  2. Preserve and identify failed parts and other evidence before destructive inspection or cleaning.
  3. Record the event timeline, symptoms, operating conditions, design expectations, maintenance history, and service history that are actually available.
  4. Document observations with photographs, inspection notes, measurements, test results, units, and relevant instrument or test conditions.
  5. Separate the symptom, failure mode, physical failure mechanism, contributing factors, and root cause.
  6. Develop competing hypotheses and compare each one against the available evidence rather than selecting a cause too early.
  7. Use an appropriate root-cause method, such as Five Whys, fault tree analysis, fishbone analysis, or FMEA, when it improves the investigation.
  8. State the supported conclusion together with assumptions, uncertainties, limitations, and unresolved questions.
  9. Recommend corrective actions that address the identified root cause, while distinguishing temporary repair from recurrence prevention.
  10. Define a repeatable verification test with measurable acceptance criteria under representative operating conditions.
  11. Present an executive-level conclusion first, then provide the detailed evidence and reasoning needed for engineering traceability.
Practical Insights

The main tradeoff is between completeness and clarity. A report needs enough evidence and detail for another engineer to reproduce the reasoning, but excessive unrelated data can hide the important findings. Another challenge is uncertainty: failure investigations may have incomplete service history, damaged evidence, or several plausible causes. In those cases, the report should show the strength and limits of the evidence rather than claiming more certainty than the investigation supports.

Why Interviewers Ask This

Interviewers want to know whether you can turn a failure investigation into a clear, traceable engineering record that distinguishes observations from conclusions, supports the identified failure mechanism and root cause with evidence, documents uncertainty, and gives others enough information to evaluate corrective actions and recurrence prevention.

Common interview mistakes

Common mistakes are documenting only the final conclusion without the supporting evidence; cleaning, repairing, or discarding failed parts before preserving evidence; confusing a symptom such as vibration with the root cause; treating the failed component as the cause when another condition produced its failure; omitting actual operating history; choosing one hypothesis before testing alternatives; mixing observations with assumptions; recommending component replacement without addressing recurrence; and failing to define how the corrective action will be verified.

Interview tip

Emphasize traceability. A strong answer is not simply 'I write a report.' Explain that every important conclusion should be connected to documented evidence, that failure mode, mechanism, and root cause are different concepts, and that the investigation is not complete until the corrective action has a repeatable verification method.

Interviewer may ask next
What would you do if the available evidence was not sufficient to prove one root cause?

I would not force a definitive conclusion. I would document the plausible hypotheses, identify the evidence supporting and contradicting each one, state the limitations of the investigation, and identify what additional inspection, measurement, testing, or service-history information could distinguish between them. Corrective actions could still be recommended where justified, but their basis and uncertainty should be explicit.

How would your report change if the same failure had already occurred several times?

I would place more emphasis on recurrence history and whether previous actions addressed only the failed component rather than the underlying cause. I would compare the earlier and current failures for common operating conditions, locations, failure mechanisms, maintenance patterns, or design features. The corrective-action section should then address the recurring system-level cause and include a verification and monitoring plan that can demonstrate whether recurrence has actually been prevented.

75. How do you check whether a corrective action has resolved a failure?Troubleshooting And Failure AnalysisMedium

Short Interview Answer (30-60 seconds)

I verify a corrective action by defining measurable success criteria, then testing the equipment under representative conditions related to the original failure. I repeat the measurements that supported the diagnosis, such as vibration, temperature, pressure, alignment, leakage, wear, or performance, and compare the results with the pre-correction condition and the required operating limits. I also confirm that the suspected failure mechanism is no longer active and that the corrective action has not introduced a new problem. When the failure develops over time, I include follow-up monitoring for recurrence. I would not consider the action verified simply because the immediate symptom disappeared.

Detailed Explanation

A corrective action is verified by showing with objective evidence that the cause or controlling mechanism of the failure has been addressed, not merely that the equipment works immediately after repair.

The verification should connect directly to the original troubleshooting evidence. For example, if excessive vibration was traced to shaft misalignment, replacing a damaged bearing might remove noise temporarily, but that alone would not prove the failure was resolved. I would verify the alignment correction and then repeat the vibration measurements under the operating conditions associated with the original problem.

Useful Questions to Ask the Interviewer
  • What was the original symptom and identified failure mode?
  • What evidence supported the suspected root cause?
  • Under what operating conditions did the failure occur?
  • What measurements or inspection results are available from before the corrective action?
  • What acceptance criteria define successful operation?
  • Can the relevant operating condition be reproduced safely during verification?
  • Does successful verification require only an immediate functional test, or also monitoring for recurrence over time?
How to Explain It in an Interview

I would use a structured verification process.

  1. Define success before testing. I would establish measurable acceptance criteria related to the original failure. Depending on the problem, these could involve vibration, temperature, pressure, leakage, alignment, dimensional condition, wear, noise, or another relevant parameter. I would use applicable design requirements, specifications, validated baseline data, or approved procedures rather than inventing limits.
  1. Connect the corrective action to the root cause. I would confirm that the action actually addresses the root-cause logic established during troubleshooting. If shaft misalignment caused abnormal bearing loading, for example, I would verify that the alignment condition was corrected rather than checking only that the bearing was replaced.
  1. Confirm that the corrective action was implemented correctly. I would inspect the repaired or modified system and verify installation, assembly, adjustment, lubrication, alignment, clearances, fastener condition, or other relevant details. I would also inspect related components for secondary damage where appropriate.
  1. Repeat the diagnostic measurements. Whenever possible, I would repeat the same measurements that identified the original problem. This provides a direct before-and-after comparison. If elevated vibration at a particular operating speed was part of the original evidence, I would measure vibration again at that operating point after the corrective action.
  1. Test under representative operating conditions. A successful idle or no-load test may not be sufficient if the original failure occurred only at a certain load, speed, temperature, pressure, duty cycle, or other operating condition. I would safely reproduce the relevant condition within approved operating limits.
  1. Confirm that the failure mechanism is no longer active. I would separate the visible symptom from the physical mechanism. If overheating was caused by inadequate lubrication, I would verify lubricant delivery and operating temperature rather than simply confirming that the machine runs. If the failure involved fatigue, wear, corrosion, or another time-dependent mechanism, an immediate functional test might not be enough to demonstrate long-term resolution.
  1. Check for unintended consequences. A corrective action can eliminate one problem while creating another. I would check relevant interfaces and neighboring components for changes in load, alignment, clearances, temperature, vibration, pressure, or other conditions that could introduce a new failure mode.
  1. Check repeatability. One successful run is weaker evidence than repeated successful operation. When practical, I would repeat the test or operating cycle to determine whether the improvement is consistent.
  1. Monitor for recurrence when needed. Some failures develop only after time, cycling, wear, corrosion, or thermal exposure. In those cases, I would define an appropriate follow-up inspection or condition-monitoring interval and identify the indicators that would show recurrence.
  1. Document the verification. I would record the original condition, identified failure mode and root cause, corrective action, test conditions, measurements, acceptance criteria, results, remaining uncertainty, and any required follow-up monitoring.

If the equipment does not meet the defined acceptance criteria, or if evidence suggests that the original failure mechanism is still active, I would not declare the corrective action successful. I would reopen the root-cause analysis, reconsider competing hypotheses, and determine whether the corrective action was incomplete or the original diagnosis was incorrect.

The main principle is that a corrective action is verified by a repeatable test under relevant conditions, using measurements tied to the original failure and clear acceptance criteria. Disappearance of the symptom alone is not sufficient proof.

Technical Approach
  1. Restate the original symptom, failure mode, suspected mechanism, and root cause.
  2. Define measurable acceptance criteria before verification.
  3. Confirm that the corrective action was implemented as intended.
  4. Inspect the repaired system and related components.
  5. Repeat the measurements that supported the original diagnosis.
  6. Test under representative operating conditions associated with the failure.
  7. Compare post-correction measurements with the failed condition, expected condition, and applicable acceptance criteria.
  8. Confirm that the original failure mechanism is no longer active.
  9. Check that the corrective action has not introduced a new failure mode.
  10. Repeat the verification test when practical to establish consistency.
  11. Monitor for recurrence when the failure mechanism is time-dependent.
  12. Document the evidence and conclusion.
  13. If acceptance criteria are not met, reopen the root-cause analysis rather than assuming the repair was successful.
Practical Insights

The main tradeoff is between test effort and confidence in the corrective action. A short functional test is fast and may confirm basic operation, but it can miss failures that appear only under full load, high temperature, certain speeds, repeated cycles, or extended service. A longer or more instrumented verification provides stronger evidence but may require more downtime, testing resources, and engineering effort. The verification depth should therefore match the failure mechanism, uncertainty in the diagnosis, operating conditions, and consequence of recurrence.

Why Interviewers Ask This

Interviewers want to know whether you treat a corrective action as something that must be verified with evidence rather than assuming the problem is solved because a component was repaired or replaced. They are evaluating whether you can define measurable acceptance criteria, reproduce the relevant operating conditions safely, compare before-and-after behavior, distinguish symptom removal from root-cause elimination, and monitor for recurrence.

Common interview mistakes

Common mistakes include declaring success because the machine starts after repair, checking only the symptom instead of the identified failure mechanism, replacing the failed component without correcting the root cause, changing several variables at once so the effective corrective action cannot be identified, failing to reproduce the operating condition associated with the failure, using different measurements before and after the repair, having no defined acceptance criteria, ignoring new problems introduced by the corrective action, and ending verification too early for a time-dependent failure mechanism.

Interview tip

Structure the answer around evidence: define success, connect the corrective action to the root cause, repeat the original diagnostic measurements, test under representative conditions, compare the results with acceptance criteria, and monitor for recurrence when necessary. Explicitly state that disappearance of the symptom alone does not prove that the failure has been resolved.

Interviewer may ask next
What would you do if the equipment passes the immediate verification test but the original failure occurred only after several weeks of operation?

I would treat the immediate test as preliminary verification rather than complete proof. I would confirm that short-term measurements are consistent with the expected corrected condition, then establish follow-up monitoring appropriate to the failure mechanism. Depending on the problem, that could include vibration trends, temperature, lubricant condition, wear measurements, leakage, dimensional inspection, corrosion checks, or scheduled visual inspection. I would define what evidence would indicate recurrence and review the equipment after a representative amount of service. For fatigue, wear, corrosion, thermal cycling, and similar mechanisms, sufficient operating exposure may be necessary before the corrective action can be considered fully validated.

How would your verification approach change if reproducing the original failure condition could damage the equipment or create a safety risk?

I would not deliberately recreate an unsafe or destructive condition. Instead, I would use the safest representative test that still challenges the corrective action and combine it with other evidence. That could include controlled testing at reduced load, inspection, dimensional measurements, vibration or temperature monitoring, analytical checks, validated simulation, material examination, or gradually increasing operating severity while monitoring critical parameters. I would clearly document which parts of the original condition could not be reproduced and keep the conclusion appropriately limited until enough operating evidence is available.

76. How would you respond if essential machinery failed during the busiest part of production?Troubleshooting And Failure AnalysisHard

Short Interview Answer (30-60 seconds)

I would first make the situation safe and confirm the failed machine is isolated according to the site's procedures. I would quickly establish what stopped, what changed immediately before the failure, and whether there are signs such as abnormal vibration, temperature, noise, leakage, pressure, or electrical trips. I would preserve failed parts and operating evidence, compare actual conditions with normal operation, and test the most likely failure hypotheses with measurements rather than replacing parts blindly. Once the failure mode and immediate cause are understood, I would coordinate the safest practical repair or approved production contingency. Before returning the machine to full production, I would verify the repair through a controlled test and monitored ramp-up. After production is stabilized, I would complete the root cause analysis and corrective actions needed to prevent recurrence.

Detailed Explanation

The main objective is not simply to restart the machine as fast as possible. During peak production, the pressure to restore output is high, but an uncontrolled restart or rushed component replacement can damage equipment, destroy failure evidence, create a safety hazard, or cause another shutdown. I would therefore separate the response into safe stabilization, evidence-based diagnosis, controlled recovery, verification, and recurrence prevention.

Useful Questions to Ask the Interviewer
  • What type of machinery failed, and what function does it perform in the production process?
  • Did the equipment shut down automatically, or did an operator stop it because of an abnormal condition?
  • Are there immediate hazards involving stored mechanical energy, pressure, temperature, electrical energy, chemicals, or moving components?
  • What symptoms occurred immediately before the failure, such as vibration, noise, overheating, leakage, loss of pressure, reduced speed, or poor product quality?
  • Are alarms, historian data, maintenance records, lubrication records, inspection results, or recent repair information available?
  • Was there a recent change in load, speed, material, tooling, lubrication, alignment, maintenance condition, or operating procedure?
  • Is an approved redundant machine, bypass, spare assembly, or alternative production route available while troubleshooting continues?

Without those details, I would not assume a specific failed component or root cause.

How to Explain It in an Interview

First, I would establish a safe condition. If the machine could create a hazard, I would stop or isolate it using the applicable site procedures before inspection. I would not repeatedly reset trips or restart the equipment just because production demand is high. A protective trip may be evidence of a real mechanical or process problem.

Second, I would preserve evidence. I would record the machine state, alarms, operating conditions, relevant temperatures, pressures, speeds, loads, vibration observations, leakage, unusual sounds, and operator observations. If a bearing, seal, coupling, fastener, gear, shaft, or other component is damaged, I would preserve the failed part whenever practical rather than immediately discarding or cleaning it. Fracture surfaces, wear patterns, discoloration, debris, lubricant condition, and contact marks can contain important root-cause evidence.

Third, I would define the symptom separately from the failure mode and root cause. For example, 'the machine stopped' is a symptom. A seized bearing could be a failure mode. Lubrication loss, contamination, excessive load, misalignment, or incorrect installation could be possible underlying causes. Keeping those levels separate prevents the team from treating the first visible problem as the complete explanation.

Fourth, I would compare actual operating conditions with expected conditions and service history. I would review whether the equipment was operating within its normal load, speed, temperature, pressure, alignment, lubrication, and maintenance conditions. I would also look for changes that occurred shortly before the event. This helps determine whether the failure is isolated or connected to a changed operating condition.

Fifth, I would build a small set of competing hypotheses and test them with measurements. Depending on the machine and symptoms, that might include checking alignment, shaft runout, vibration, bearing temperature, lubricant level and condition, clearances, drive tension, pressure, flow, fastener condition, or coupling condition. I would choose measurements based on the evidence instead of replacing several components at once, because replacing multiple items can hide the actual cause.

For a complex failure, I could organize the reasoning with a fault tree, Five Whys, fishbone analysis, or FMEA. The tool is secondary to the discipline of asking what evidence supports or contradicts each proposed cause. During an urgent production interruption, I would keep the immediate diagnosis focused enough to restore the equipment safely, then perform the deeper root cause analysis after the process is stable.

Sixth, after identifying the failed component and an adequately supported immediate cause, I would implement the appropriate corrective action within my authority and the site's procedures. That could mean repairing or replacing the failed component, correcting alignment, restoring lubrication, removing contamination, correcting an operating condition, or addressing another verified cause. I would avoid temporary modifications that bypass safeguards or knowingly operate equipment outside acceptable conditions simply to recover production.

If the plant has an approved spare machine, redundant line, alternate routing, or other contingency, I would coordinate with production and maintenance so output can be recovered without interfering with the investigation or creating additional risk. The decision should consider personnel safety, equipment damage potential, product quality, repair time, and the consequences of another failure rather than production rate alone.

Seventh, I would verify the repair before declaring the problem solved. I would perform the applicable inspection and a controlled functional test, initially at a conservative condition where appropriate. I would compare measurable behavior with normal or specified behavior and monitor the parameters that were relevant to the failure, such as vibration, temperature, pressure, speed, leakage, noise, or product quality. If those results are satisfactory, I would support a monitored ramp-up toward representative production conditions. A machine that runs unloaded for a few minutes is not necessarily proven under its actual production duty.

Finally, once production is stable, I would complete the root cause and recurrence-prevention work. I would distinguish the failed component from the mechanism that damaged it and from the organizational or technical condition that allowed that mechanism to occur. Corrective actions might involve inspection intervals, lubrication controls, alignment procedures, condition monitoring, spare-part strategy, maintenance instructions, operating limits, or design changes, but only where supported by the investigation. I would document what was observed, what was measured, what was changed, and how the repair was verified.

The overall principle is to respond quickly without allowing production pressure to replace engineering judgment: make it safe, preserve evidence, diagnose with measurements, correct the supported cause, verify under representative conditions, and prevent recurrence.

Technical Approach
  1. Establish a safe machine condition and isolate hazardous energy according to applicable procedures.
  2. Define the production impact and determine whether an approved alternate production route is available.
  3. Capture alarms, operating data, operator observations, service history, and the machine condition before disturbing evidence.
  4. Inspect the failed system and preserve damaged components or other physical evidence where practical.
  5. Separate the observed symptom from the failure mode, physical failure mechanism, and possible root causes.
  6. Compare actual load, speed, temperature, pressure, vibration, alignment, lubrication, maintenance history, and other relevant conditions with expected operation.
  7. Form a limited set of competing hypotheses based on the evidence.
  8. Select measurements or inspections that can confirm or reject those hypotheses without unnecessary component replacement.
  9. Identify the most strongly supported immediate cause and apply an authorized corrective action.
  10. Inspect the completed repair and perform a controlled functional test.
  11. Monitor relevant parameters while ramping toward representative production conditions.
  12. After stable recovery, complete the deeper root cause analysis and implement evidence-based recurrence-prevention actions.
Practical Insights

The main tradeoff is recovery speed versus confidence that the machine is safe and the actual failure mechanism has been addressed. A very fast component swap may reduce downtime initially, but if the underlying cause is misalignment, contamination, lubrication loss, overload, or another unresolved condition, the replacement can fail again. A very long investigation can also create unnecessary production losses when enough evidence already exists for a safe repair. The practical approach is to collect the highest-value evidence first, use targeted measurements to narrow the causes, restore operation only after an adequate repair and verification test, and continue the deeper root cause work once production is stable. The amount of testing should reflect the failure severity, uncertainty, and consequences of recurrence.

Why Interviewers Ask This

Interviewers are evaluating whether I can stay calm under production pressure, protect people and equipment, distinguish symptoms from root causes, use evidence rather than guesswork, coordinate a controlled recovery, and balance production urgency against the risk of causing a larger failure. They also want to see whether I verify the repair under representative conditions and take action to prevent recurrence.

Common interview mistakes

Common mistakes include repeatedly resetting the machine without understanding why it tripped; allowing production pressure to override safety controls; immediately replacing the visibly damaged component and calling it the root cause; cleaning or discarding failed parts before examining fracture, wear, heat, or contamination evidence; changing several components at once so the real cause cannot be isolated; relying on opinions instead of measurements; assuming a successful unloaded restart proves the machine at full production conditions; bypassing safeguards as a temporary production fix; and stopping the investigation after production resumes without completing recurrence-prevention actions.

Interview tip

Structure the response around priorities rather than listing troubleshooting tools. A strong answer shows that safety and evidence preservation come first, then diagnosis using actual measurements, then a controlled repair and verification, followed by root cause and recurrence prevention. Mention production continuity, but make clear that production urgency does not justify an unsafe restart or an unsupported guess.

Interviewer may ask next
What would you do if the machine ran normally after the repair but you were still uncertain about the root cause?

I would distinguish successful restoration from confirmed root cause. I would keep the machine under appropriate monitoring and define which measurements could reveal recurrence, such as vibration, temperature, pressure, leakage, lubricant condition, or another parameter relevant to the original symptoms. I would preserve the failed components and continue the root cause investigation using the service history, operating data, physical evidence, and competing hypotheses. If the remaining uncertainty creates an unacceptable safety, equipment, or product-quality risk, I would not treat a short successful run as sufficient evidence for unrestricted operation. The final corrective action should address the supported cause, and the verification plan should demonstrate that the failure mechanism has actually been controlled.

How would your response change if there were no spare machine and every minute of downtime caused major production losses?

The urgency would change how I prioritize the work, but not the safety or evidence requirements. I would immediately bring the necessary production, maintenance, operations, and engineering resources together, collect the highest-value evidence first, and focus measurements on the most likely causes so decisions can be made quickly. I would evaluate whether a technically justified temporary repair or reduced operating condition is permitted and whether its risks can be controlled, but I would not bypass safeguards or knowingly operate damaged equipment outside acceptable conditions merely to recover output. I would verify any repair with a controlled test and monitored return to production. Once operation was restored, I would complete the full root cause investigation and permanent corrective actions so the urgency does not create a repeat failure.

77. What experience do you have using stress-analysis results to investigate failures?Troubleshooting And Failure AnalysisHard

Question Details

Focus on failure investigations informed by your stress-analysis results.

Short Interview Answer (30-60 seconds)

I would answer this with a real failure-investigation example from my own experience rather than inventing project details. My approach is to use stress analysis as one source of evidence, not as proof by itself. I compare predicted stress concentrations, load paths, deformation, and contact regions with the actual crack, yielding, wear, or other failure evidence. If the prediction does not match the physical failure, I recheck loads, constraints, geometry, contacts, material assumptions, assembly conditions, and service history. I then combine the analysis with inspection and measurements to identify the root cause and verify the corrective action under representative conditions.

Detailed Explanation

Stress-analysis results are most useful in a failure investigation when they are used to test hypotheses against physical evidence. Because no specific past project, component, load case, material, or measured result was supplied here, I would not invent personal experience or numerical findings. In an interview, I would replace the general method below with a truthful project example.

I would begin by preserving the failed component and documenting its condition before cleaning, machining, replacing, or otherwise disturbing evidence. I would identify the symptom, such as a cracked or permanently deformed component, and then separate that symptom from the failure mode, physical mechanism, and root cause.

For example, fracture is a failure mode. Fatigue crack growth could be the mechanism. The root cause could be an underestimated cyclic load, an unintended stress concentration, misalignment, an assembly constraint, insufficient section geometry, or another condition supported by evidence. Those are different levels of the investigation and should not be treated as interchangeable.

Next, I would compare the actual operating conditions with the assumptions used in the stress analysis. Relevant inputs can include applied loads, supports, contact conditions, assembly preload, temperature, vibration, alignment, geometry, material behavior, and service history. I would clearly separate measured facts from assumptions and unknowns.

I would then examine the stress-analysis results for the predicted load path, deformation pattern, stress concentrations, contact regions, and the type and direction of stress relevant to the observed failure. I would not rely only on the single maximum stress value. A local peak can represent a real geometric stress concentration, insufficient mesh resolution, an idealized constraint, or a mathematical singularity, so its physical meaning has to be evaluated.

If the physical crack initiation or yielding occurs in the same region where the model predicts a credible high-stress condition, that agreement supports the hypothesis, but it still does not prove the root cause. I would look for independent evidence through inspection, dimensional measurements, operating data, fracture-surface observations, alignment checks, vibration measurements, or other evidence appropriate to the failure.

If the model predicts the critical stress in a different location from the actual failure, I would treat that disagreement as useful diagnostic evidence. I would recheck boundary conditions, missing loads, contacts, local geometry, assembly preload, thermal effects, material assumptions, residual stresses where relevant, and whether real service conditions differ from the design case. I would not change the model merely to force it to reproduce the observed failure.

For a suspected fatigue problem, I would focus on cyclic stress range and loading history rather than comparing only a static maximum stress with a material strength value. I would determine whether the predicted fatigue-critical location is consistent with the observed crack initiation region and whether the assumed loading represents actual service conditions. For suspected overload or yielding, I would instead examine whether the calculated stress state, deformation, and load path are consistent with the observed permanent deformation or fracture evidence.

I would organize competing explanations with an appropriate root-cause method such as a fault tree, Five Whys, FMEA, or fishbone analysis. The purpose is not to use every tool mechanically, but to keep plausible causes visible until inspection, measurements, calculations, or testing eliminate them.

Before trusting the model, I would also check whether the results are sufficiently credible for the decision. Depending on the analysis, that can include checking reactions and equilibrium, deformation shape, mesh sensitivity, contact behavior, boundary-condition sensitivity, and whether a local stress peak is physically meaningful. A finer mesh cannot correct an incorrect load case, unrealistic constraint, or missing physical effect.

After identifying a root cause supported by both physical evidence and analytical results, I would evaluate the corrective action. That might involve changing geometry, improving the load path, reducing a stress concentration, correcting alignment, modifying an interface or support condition, controlling the applied load, or addressing another verified cause. I would also check whether the modification creates a new critical stress concentration, transfers load to another weak region, or introduces a different failure mode.

Finally, I would verify the corrective action with representative inspection, measurement, or testing. A revised simulation showing lower stress is useful, but it is not enough by itself to establish that the real failure has been prevented. The investigation is complete only when the physical evidence, operating conditions, analysis, and verification results support the same conclusion and there is a repeatable way to confirm the fix and prevent recurrence.

Useful Questions to Ask the Interviewer
  • Are you looking for an example involving fatigue, static overload, thermal stress, contact stress, or another failure mechanism?
  • Was the stress model available before the failure, or was it developed specifically for the investigation?
  • What physical evidence was available from the failed part, such as fracture-surface features, deformation, wear, or dimensional measurements?
  • Were the actual loads, temperatures, vibration, alignment, and assembly conditions measured or initially estimated?
  • Is the main emphasis on determining the failure mechanism, validating the stress model, identifying the root cause, or verifying the corrective action?
How to Explain It in an Interview

Start with the real failure evidence rather than the analysis software. Explain what failed, what evidence was preserved, and what operating conditions were known. Then describe the hypothesis you tested with the stress analysis and compare the predicted stress concentration, load path, deformation, or contact condition with the physical failure location. Explain which assumptions you checked and what evidence would have caused you to reject the hypothesis. Finish with the corrective action and how you verified it under representative conditions. If you did not personally perform every part of the investigation, clearly distinguish your own analysis and decisions from work performed by other team members.

Technical Approach
  1. Establish safe conditions and preserve the failed component and associated evidence.
  2. Document the failure location, fracture, deformation, wear, corrosion, overheating, or other observable condition before disturbing the evidence.
  3. Separate the symptom, failure mode, physical mechanism, and possible root causes.
  4. Gather relevant service history and actual operating conditions, including loads, supports, temperature, vibration, alignment, assembly state, and abnormal events where available.
  5. Review the stress-analysis model, including geometry, material assumptions, loads, constraints, contacts, preload, thermal conditions, and mesh.
  6. Check basic model credibility through reactions or equilibrium, deformation behavior, mesh or sensitivity checks where appropriate, and the physical meaning of local stress peaks.
  7. Compare predicted stress concentrations, load paths, deformation, contact regions, and relevant stress components with the actual failure evidence.
  8. Develop competing root-cause hypotheses using an appropriate method such as a fault tree, Five Whys, FMEA, or fishbone analysis.
  9. Use inspection, measurements, service data, calculations, or testing to eliminate unsupported hypotheses and refine assumptions only when evidence justifies the change.
  10. Determine the root cause that best explains both the physical evidence and the analytical results.
  11. Evaluate the proposed corrective action and check that it does not create a new critical stress concentration, undesirable load path, or different failure mode.
  12. Verify the corrective action under representative conditions and define how recurrence will be prevented or detected.
Practical Insights

The main tradeoff is between model detail and confidence in the physical inputs. A highly detailed model is not necessarily more accurate if the actual loads, supports, contacts, temperature, assembly state, or material behavior are uncertain. More mesh refinement increases computational effort and can improve resolution of legitimate stress gradients, but it cannot repair incorrect physics and can make a mathematical singularity appear even larger. Failure investigations therefore often gain more value from sensitivity studies, field measurements, inspection, and representative testing than from adding model complexity without better evidence.

Why Interviewers Ask This

Interviewers are evaluating whether you can use stress-analysis results as engineering evidence within a disciplined failure investigation. They want to see whether you can connect calculated stresses, deformation, and load paths to physical failure evidence, challenge modeling assumptions, distinguish the failure mechanism from the root cause, consider competing hypotheses, and verify that corrective action addresses the actual cause rather than only the symptom.

Common interview mistakes

Common mistakes include treating the maximum stress from a simulation as proof of root cause; changing model inputs until the result matches the failure without supporting evidence; ignoring the fracture surface or other physical evidence; using nominal design loads when actual service conditions may have been different; interpreting a numerical singularity as a physical stress value; refining the mesh while leaving unrealistic boundary conditions unchanged; using only a static stress result for a suspected fatigue failure; confusing the failure mode with the root cause; replacing or cleaning the failed part before preserving evidence; ignoring competing hypotheses; and declaring success solely because a revised model reports a lower stress.

Interview tip

Use one truthful project example and tell it as an evidence chain: what physically failed, what facts were known, what hypothesis the stress analysis tested, how the predicted stress state compared with the actual failure evidence, what assumptions you challenged, what additional measurements supported the root cause, and how the corrective action was verified. Do not claim measurements, analysis ownership, or results that you did not personally have.

Interviewer may ask next
What would you do if the stress analysis predicted the highest stress in a different location from where the component actually failed?

I would treat the mismatch as evidence that the current model or failure hypothesis may be incomplete rather than forcing the analysis to match the failure. I would first confirm the actual failure origin and mechanism from the physical evidence. Then I would review the real loads, constraints, contacts, local geometry, assembly preload, alignment, temperature, vibration, and material assumptions. I would look for missing load cases or service conditions and use sensitivity studies to identify which assumptions move the critical stress region. I would update the model only when inspection, measurements, or operating evidence support the change. If a credible model still does not explain the failure, I would keep alternative root-cause hypotheses open.

How would your investigation change if the component experienced highly variable cyclic loads instead of mainly static loading?

I would shift the investigation toward the load history, stress range, and crack-initiation conditions rather than focusing only on maximum static stress. I would establish what is known about the magnitude, sequence, and number of load cycles and examine whether the physical fracture evidence is consistent with fatigue. The stress analysis would be used to identify cyclic hot spots and local stress concentrations under representative load cases. Where relevant and supported by evidence, I would also consider mean stress, surface condition, residual stress, geometry, and other influences on fatigue. I would compare the predicted fatigue-critical region with the observed crack origin and validate important assumptions with measurements or representative cyclic testing. The corrective action would need to address the damaging cyclic condition or its root cause, not merely reduce one static peak.

78. Describe how you explained a difficult technical idea to someone without a technical background.BehavioralEasy

Question Details

Use a situation in which you had to make a complex technical concept understandable to a nontechnical audience.

Interview tip:

Use STAR to structure your answer: briefly explain the Situation and Task, make Action the most detailed part, and finish with the Result. For example, describe a situation where you simplified a difficult mechanical concept, used a familiar example or visual, checked understanding, answered questions in plain language, and helped a nontechnical audience make an informed decision.

Situation

During a previous project, I was reviewing a metal bracket that would experience repeated loading during normal use. My analysis showed that a sharp corner in the design could create a local area of high stress. The project manager needed to understand why this mattered before approving a small design change, but they did not have a mechanical engineering background.

Task

My responsibility was to explain the risk clearly without turning the discussion into a lesson on stress analysis. I needed to help the project manager understand why a part that looked strong enough could still develop a crack after many repeated load cycles.

Action

I first avoided equations and technical terms. I compared the sharp corner to bending a paper clip repeatedly at the same spot. I explained that the paper clip may handle one bend without a problem, but repeated bending concentrates damage in one small area. I then connected that example to the bracket and explained that the sharp corner caused force to become concentrated in a similar way. I showed a simple image from the analysis and pointed out the small region where the stress was highest. Instead of focusing on the color scale or calculation method, I explained what the image meant for the actual part. I also explained that adding a smoother radius would spread the load over a larger area and reduce the chance of a crack starting there. After explaining it, I asked the project manager to describe the concern back to me in their own words. That helped me confirm that my explanation was clear and gave me a chance to correct one misunderstanding about the part failing immediately versus becoming more vulnerable over repeated use.

Result

The project manager understood both the risk and the reason for the proposed design change, so the team was able to make the decision with a shared understanding of the engineering concern. I learned that explaining a technical idea well is not about removing all technical detail. It is about choosing only the detail that helps the listener understand the decision they need to make.

Why Interviewers Ask This

Interviewers ask this question to evaluate whether a Mechanical Engineer can translate complex engineering information into clear language for people in other functions. A strong answer demonstrates communication, audience awareness, practical judgment, and the ability to confirm understanding before an important decision is made.

Interviewer may ask next
Why did you choose the paper clip example to explain the problem?

I chose it because repeated bending is something most people have seen, so it gave the project manager a familiar way to understand how repeated loading can damage one small area over time. Once that basic idea was clear, it was much easier to connect it to the sharp corner in the bracket.

How did you know your explanation was successful?

I asked the project manager to explain the concern back to me in their own words. Their response showed that they understood why the sharp corner increased the risk during repeated loading and why a smoother radius would help. It also revealed one misunderstanding, which I was able to correct before the team made the design decision.

79. How do you keep your mechanical-engineering knowledge and working methods current?BehavioralEasy

Question Details

Describe how you stay informed about developments and current practices in this field.

Interview tip:

Use STAR to structure your answer: briefly explain the Situation and Task, make Action the most detailed part, and finish with the Result. For example, describe a time when you needed to keep your mechanical engineering knowledge current, how you identified useful technical updates and working methods, how you discussed them with colleagues, how you decided what was relevant to your work, and what you learned from applying the updated approach.

Situation

During a previous project, I was supporting the design and review of mechanical components. I noticed that some of the analysis methods and reference material I had used before were no longer the best source for every design decision. I wanted to make sure my work reflected current engineering practice rather than relying only on habits from earlier projects.

Task

My responsibility was to keep my technical knowledge current while still meeting the project needs. I needed a practical way to find useful updates, judge whether they applied to our work, and bring relevant improvements into my normal design and review process.

Action

I created a simple routine for staying current. I regularly reviewed updated engineering standards, manufacturer technical information, and reliable technical publications related to the components and materials I was working with. When I found a new method or recommendation, I did not apply it automatically. I first compared it with the design requirements, the existing calculation method, and the assumptions behind our work. If the change could affect safety, reliability, manufacturability, or testing, I discussed it with the appropriate engineers before changing the approach. I also used design reviews as a learning opportunity. I asked why certain methods were preferred and kept notes on useful lessons that could improve future calculations, drawings, and checks. When I learned a better working method, I added it to my own checklist so that it became part of my normal process instead of something I had to remember later.

Result

This approach helped me keep my engineering decisions based on current and relevant information while avoiding unnecessary changes just because something was new. It also improved the consistency of my design reviews and gave me a repeatable way to continue learning. I learned that staying current is not only about reading new information. It is also about checking whether that information is appropriate for the specific engineering problem and then applying it carefully.

Why Interviewers Ask This

Interviewers ask this question to understand whether a mechanical engineer takes responsibility for continuous learning and can separate useful technical developments from changes that do not fit the work. A strong answer shows curiosity, sound engineering judgment, careful use of standards and technical sources, collaboration with other engineers, and a practical way to turn learning into better working methods.

Interviewer may ask next
How do you decide whether a new engineering method or recommendation is worth using?

I first check whether it is relevant to the actual design requirements and whether the source is reliable. Then I compare the new method with our existing assumptions, calculations, standards, and practical constraints. If it could affect safety, reliability, manufacturing, or testing, I discuss it with the appropriate engineers before making a change. That helps me improve the work without adopting something only because it is new.

What did you learn from creating a routine for keeping your knowledge current?

I learned that continuous learning is most useful when it is connected to real engineering work. Reading technical updates gives me information, but comparing them with project requirements, discussing them during reviews, and adding useful lessons to my own checklist is what turns that information into a better working method.

80. Describe how you worked with sales or marketing to develop a successful product.BehavioralHard

Question Details

Discuss your experience collaborating with either of these departments during product development.

Interview tip:

Use STAR to structure your answer: briefly explain the Situation and Task, make Action the most detailed part, and finish with the Result. For example, describe a product development project where you worked closely with sales or marketing to understand customer needs, translate those needs into practical engineering requirements, explain technical tradeoffs clearly, make design decisions together, and deliver a product that better matched the market need.

Situation

During a previous project, I was helping develop a new mechanical product for customers who needed a compact and easy to use solution. Our sales team was speaking with customers regularly and brought back feedback about installation space, ease of maintenance, and concerns about product complexity. The original engineering concept met the main technical requirements, but some details did not fully match how customers expected to use the product.

Task

My responsibility was to work with sales to understand the customer feedback and turn it into clear engineering requirements. I also needed to protect the product's reliability and manufacturability while making the design easier for customers to install and service.

Action

I first met with the sales team and asked them to separate direct customer feedback from their own interpretation. This helped me understand the real problems instead of designing around assumptions. I grouped the feedback into themes such as installation space, access for maintenance, and ease of operation. I then reviewed each theme against the existing design and identified which changes were practical without creating new reliability or manufacturing risks. For example, when sales explained that customers wanted easier access during maintenance, I reviewed the component layout and found that we could reposition a serviceable part without changing the main structural design. I created a simple concept showing the revised arrangement and explained to sales why some requests could be included directly while others would require larger design changes. I also described the tradeoffs in simple terms so the sales team could communicate them accurately to customers. After we agreed on the most important changes, I updated the design requirements, worked with the engineering team to refine the concept, and checked that the revised design still met the original functional and manufacturing needs. I kept sales involved during the review so they could confirm that the design was still addressing the customer concerns they had heard.

Result

The final product concept was better aligned with how customers expected to install, use, and maintain it while still meeting the engineering requirements. The collaboration also improved communication between engineering and sales because we had a clearer way to turn customer feedback into design decisions. I learned that sales can provide valuable information about real customer problems, but engineers need to ask careful questions and translate that feedback into requirements before changing the design.

Why Interviewers Ask This

Interviewers ask this question to understand whether a mechanical engineer can work effectively with commercial teams instead of treating product development as only a technical activity. A strong answer shows that the candidate can listen to customer needs, translate market feedback into engineering requirements, explain technical tradeoffs clearly, and balance customer value with reliability and manufacturability.

Interviewer may ask next
How did you handle customer requests that were not practical to include in the design?

I first tried to understand the problem behind the request instead of rejecting the requested solution immediately. Then I reviewed the engineering impact and explained the tradeoffs to sales in simple terms. If a request created too much risk or required a major redesign, I suggested a practical alternative that addressed the same customer concern with less impact on reliability or manufacturing.

What did you learn about working with sales during product development?

I learned that sales can provide useful context that engineers may not see directly because they speak with customers more often. At the same time, I learned that I need to ask detailed questions before turning feedback into a design change. The best results came when I combined the customer's need with engineering judgment and kept sales involved as the design evolved.

More questions load as you scroll

Disclaimer: This interview guide is for educational and informational purposes only. It is designed to help readers prepare, but it does not guarantee any interview result, hiring decision, offer, or outcome. Interview questions, hiring criteria, and preferred answers can vary by employer, interviewer, industry, location, and time. All answers, examples, and explanations in this guide are suggested examples for interview preparation, not definitive answers or instructions for professional practice. They are based on research and judgment, are provided without warranties of any kind, and should be adapted to the question, role, and applicable laws and professional requirements. Diagrams are simplified illustrations intended to highlight the main concepts and their relationships; actual situations, systems, and practices may be more complex. Alternative approaches may be equally valid or better suited to a particular question, context, or interviewer. To the fullest extent permitted by applicable law, the contributors and publisher are not liable for decisions made, actions taken, or losses incurred based on this guide.

State Laws and Professional Responsibilities: Laws and requirements governing an occupation vary by state and jurisdiction. You are responsible for checking the current laws, licensing requirements, and scope-of-practice rules that apply to your location and role, and for ensuring that your answers and actions comply with them. Adapt examples in this guide to those requirements. This guide is not legal advice.

Content Accuracy and Verification: To the fullest extent permitted by applicable law, we do not represent or warrant that interview guides, questions, answers, examples, or diagrams are accurate, complete, current, error-free, or suitable for any particular purpose. You are responsible for independently reviewing and verifying the information before relying on it.